Mobile AI news ticker

Tuesday 8 August 2023

Hugging Face publishes swift-transformers for Core ML models in Swift apps

Hugging Face published swift-transformers on August 8, 2023, the date of the repository’s first tag, a Swift package that gives iOS and Mac developers a transformers-like API for running language models on the device through Core ML. Pedro Cuenca introduced it as an in-development library built around four modules, Tokenizers, Hub, Generation and Models.

The Tokenizers module ports the normalisation and pre-processing rules that the Python tokenizers library keeps as configuration files next to a model on the Hub, so an app does not hardcode those decisions per model and can swap one checkpoint for another. It covered BPE at release, the family used by the GPT models, Falcon and Llama, with Unigram and WordPiece listed as later work. The Hub module downloads those configuration files and the model metadata, and Generation implements greedy decoding and top-k sampling.

The Models module wraps a converted Core ML package behind a LanguageModel type, and Core ML then decides whether to run it on the CPU, the GPU or the Neural Engine. Cuenca writes that flexible input shapes run on the CPU only, which is why Hugging Face’s exporters conversion tool switched to fixed sequence lengths, and that the Core ML path cached no attention keys and values at that point, both of which cap how long a context an app can work with.

Hugging Face states it tested the package with Llama 2, Falcon, StarCoder and the GPT family including GPT2, distilgpt, GPT-NeoX and GPT-J, and that encoder-decoder models such as T5 and Flan were not supported. The release came alongside swift-chat, a Mac app that loads a Core ML model and doubles as a model tester, plus converted weights for Llama 2 7B and Falcon 7B on the Hub. The package is licensed under Apache 2.0.
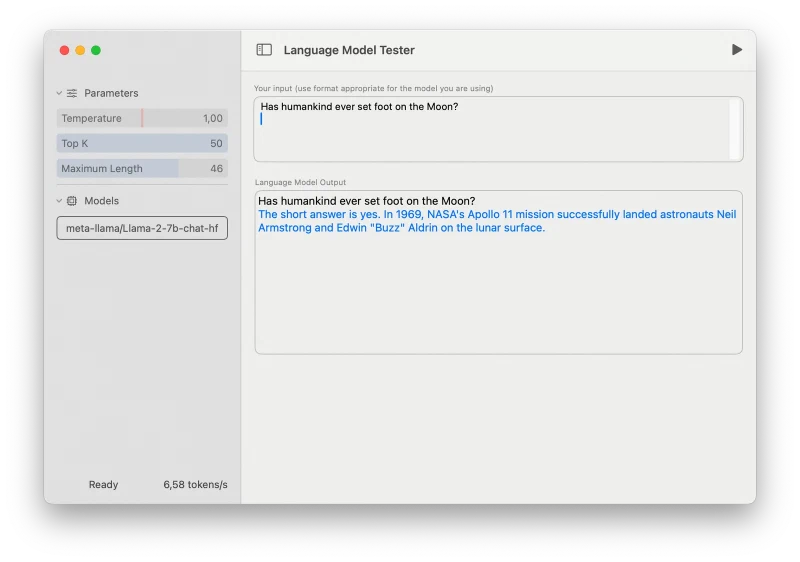
swift-chat window titled Language Model Tester running meta-llama/Llama-2-7b-chat-hf, answering a question about the Moon landing, with temperature 1.00, top-k 50 and a status line reading 6.58 tokens/s
Screenshot: Hugging Face. The demo app exposes the generation parameters and reports throughput.
Video: Hugging Face. swift-chat generating a haiku from Llama 2 7B on an M1 MacBook Pro. Open the Hugging Face post

Tuesday 20 June 2023

Microsoft trains phi-1 to 50.6 percent on HumanEval with 1.3B parameters

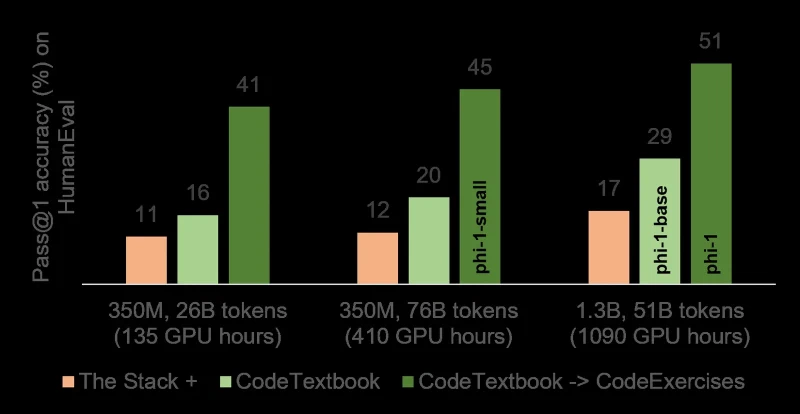
Microsoft Research published phi-1 on June 20, 2023, a Python code model with 1.3B parameters. The paper reports 50.6 percent pass@1 on HumanEval and 55.5 percent on MBPP, pass@1 being the share of problems the model solves with its first generated answer. The same table lists StarCoder at 15.5B parameters and 1 trillion training tokens with 33.6 percent and 52.7 percent, GPT-3.5 at 175B parameters with 47 percent, and CodeGen-Mono at 16.1B parameters and 577B tokens with 29.3 percent.

The training data comes to under 7B tokens in three parts. About 6B tokens are Python files pulled from The Stack and StackOverflow by a classifier the authors trained on roughly 100,000 GPT-4 ratings of how instructive a snippet is for someone learning to code. Under 1B tokens are synthetic Python textbooks written by GPT-3.5, and about 180M tokens are synthetic exercises with solutions, used only in the finetuning step that turns phi-1-base into phi-1.

Microsoft ran the training on 8 Nvidia A100 GPUs, reaching the base model in under 4 days and spending another 7 hours on the finetuning. That amounts to about 8 passes over the pretraining data and a little over 50B tokens seen, which the paper’s chart puts at 1090 GPU hours for the 1.3B run.

Bar chart of HumanEval pass@1 accuracy comparing three training data mixes at 350M and 1.3B parameters, where the textbook plus exercises mix reaches 51 percent at 1.3B against 17 percent for the same model trained on The Stack
Chart: Microsoft, Figure 2.1 of the paper. The GPU hours on the axis are the authors' own figures.

The same pipeline at 350M parameters yields phi-1-small, which the authors put at 45 percent on HumanEval and use to argue that parameter count still drives which capabilities appear at all. Microsoft posted phi-1 on Hugging Face in September 2023, where the model card lists the MIT license.

Wednesday 14 June 2023

LLMFarm runs llama.cpp models offline on iOS and macOS

Artem Savkin published the first release of LLMFarm on June 14, 2023, an iOS and macOS app that loads a quantised model file kept on the device and holds a chat with it offline. The app is built on ggml and llama.cpp, and the README asks for iOS 16 or later and macOS 13 or later.

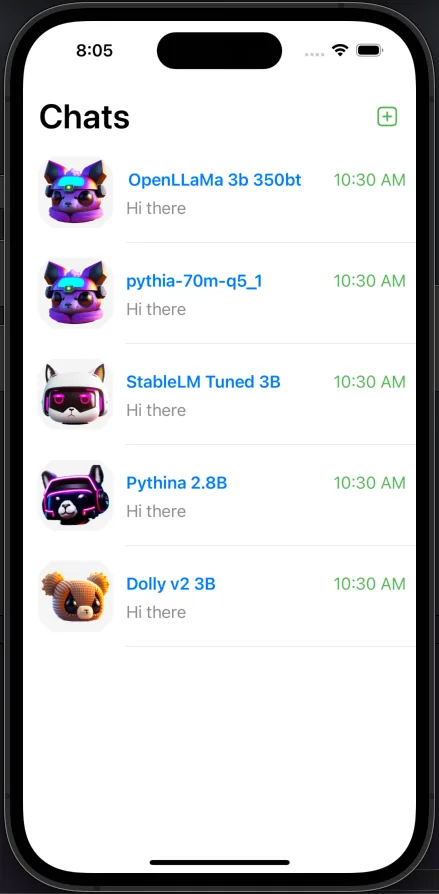
iPhone screen showing the LLMFarm chat list with five locally stored models, among them OpenLLaMa 3b 350bt, StableLM Tuned 3B and Dolly v2 3B
Screenshot from the first release. Screenshot: LLMFarm.

The app reads two llama.cpp file formats, the older ggjtv3 files with a .bin extension and GGUF files, according to the project FAQ. The first release covered LLaMA, GPT-NeoX and GPT-2 style models, with 3B builds of OpenLLaMa, StableLM and Dolly v2 among those it listed as working on an iPhone. The README has since added Gemma, Phi, Qwen, Mixtral, RWKV and LLaVA-style vision models, and marks most of them as running through Metal, Apple’s GPU interface, which it says does not work on Intel Macs.

Quantisation happens before a model reaches the phone, and the project’s on-device notes list 7B Llama 2 and Orca builds at 3-bit and 4-bit as the ones tried on an iPhone 12 Pro Max, with no published token rates. Each chat writes a JSON file of inference options, which the first release documented with defaults of temperature 0.8, top-k 40, top-p 0.95, a 2048-token context and a repeat penalty of 1.1. The app also offers tail free sampling, locally typical sampling, Mirostat, greedy decoding and grammar-constrained output. Models arrive either through an add model button that imports a file from local storage or through a download list inside the app, and the sandboxed app keeps them in its own models directory.

Memory sets the ceiling on an iPhone. The first release’s model table marked 3B models as working on an iPhone 12 Pro Max and 7B and 13B models as returning a “bad alloc” error, and the README said extended memory might be needed to solve it. The FAQ states that the Extended Virtual Addressing and increased-memory-limit entitlements are required to run models larger than 3B, and that the most common reason for a crash is lack of memory. LLMFarm is published under the MIT license, and the README now says the app is temporarily unavailable in TestFlight and the App Store.

Monday 22 May 2023

RWKV trains like a transformer and runs with constant memory per token

Bo Peng and 29 co-authors published RWKV on May 22, 2023, an architecture that trains in parallel like a transformer but runs as a recurrent network when it generates text. They released pretrained weights in six sizes from 169M to 14B parameters, all trained on the Pile, and describe the 14B model as by far the largest dense RNN trained to that point.

A transformer keeps a cache of every token it has already processed, so both the memory it holds and the work it does for each new token grow as the context gets longer. RWKV carries a fixed-size state instead, which holds the same amount of data at token 10 and at token 10,000. The complexity table in the paper puts RWKV at O(Td) time and O(d) space for a sequence of T tokens, against O(T²d) time and O(T² + Td) space for a standard transformer, and the authors note that the arithmetic per token does not depend on context length at all.

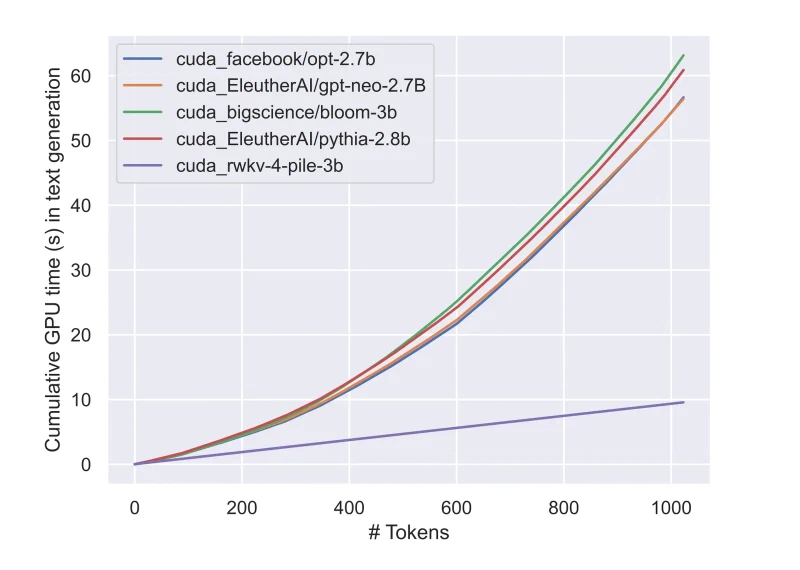
The authors measured text generation on an NVIDIA A100 with 80 GB in float32 and report cumulative time that rises in a straight line for RWKV while the transformer baselines curve upward. In their chart, RWKV-4 3B reaches about 10 seconds of cumulative GPU time after 1024 tokens, where OPT 2.7B, GPT-Neo 2.7B, BLOOM 3B and Pythia 2.8B need roughly 57 to 63 seconds.

Line chart of cumulative GPU time against generated tokens, with RWKV-4 3B rising in a straight line to about 10 seconds at 1024 tokens while OPT 2.7B, GPT-Neo 2.7B, BLOOM 3B and Pythia 2.8B curve upward past 55 seconds
Chart: Peng et al., licensed CC BY 4.0. Cumulative time to generate 1024 tokens in float32 on an A100.

On zero-shot benchmarks the paper puts RWKV close to transformers of comparable size trained on the same data. RWKV-4 at 169M scores 65.07 on PIQA where Pythia 160M scores 62.68 and GPT-Neo 125M scores 63.06, and at 14.2B it leads an interpolated GPT-level baseline on five of seven common sense tasks while trailing it on WinoGrande and ARC-Easy. The authors list the trade-off as a limitation, since funnelling everything through one fixed state limits how well the model recalls small details from very long contexts, and they report that RWKV is more sensitive to prompt wording than a transformer.

Peng publishes the code as RWKV-LM under Apache 2.0, and the weights on Hugging Face carry the same license. The repository lists rwkv.cpp among community projects, a ggml-based implementation that runs 4-bit, 8-bit and float inference on CPU, while optimised iOS and Android inference sits in the README as a to-do rather than finished work. Peng states the goal in that list.

RWKV is a RNN and very friendly for edge devices. Let’s make it possible to run a LLM on your phone.

Monday 15 May 2023

Qualcomm argues for hybrid AI, citing 10 times the cost per generative AI search query

Qualcomm published a whitepaper, The future of AI is hybrid, in May 2023 arguing that generative AI inference has to be distributed between the cloud and edge devices rather than run in data centres alone. The company’s case rests on cost. It cites a Reuters report estimating that a generative AI search costs 10 times more per query than traditional search, and a Morgan Stanley note from February 2023 saying that with more than 10 billion search queries a day, even a small share moving to language models could add multiple billions of dollars a year.

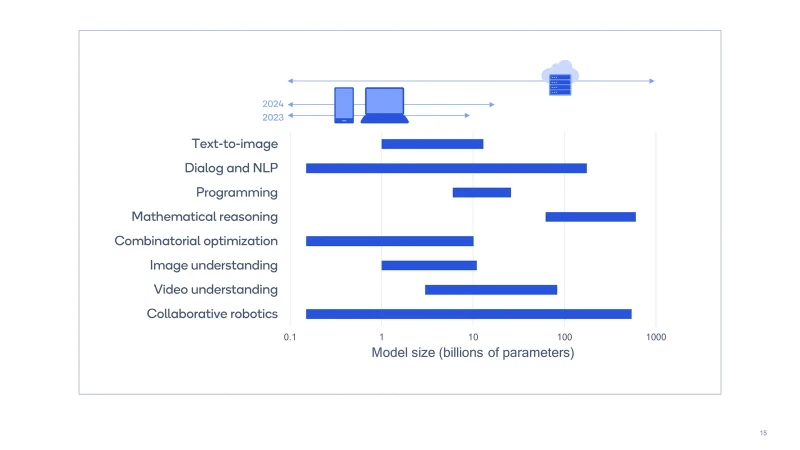
On what can run locally, Qualcomm writes that models of 1 to 10 billion parameters, assuming INT4 weights, cover capabilities including text-to-image, dialog, image understanding and video understanding. It states that models with more than 1 billion parameters, such as Stable Diffusion, already run on phones with performance and accuracy similar to the cloud equivalent, and that models of 10 billion parameters or more are slated to run on devices in the near future. The chart in the paper puts the phone and laptop reach at about 10 billion parameters for 2023 and extends it further for 2024, while the cloud range spans the whole axis to 1000 billion.

Chart of eight generative AI capabilities plotted against model size in billions of parameters, with the phone and laptop arrows reaching about 10 billion for 2023 and the cloud arrow covering the full range to 1000 billion
Chart: Qualcomm. The company's own figure for which model sizes it expects devices to handle.

The paper sets out three ways of splitting a workload. In the device-centric option the device runs most of the inference and an on-device neural network or rules-based arbiter decides when a query needs the cloud, with Qualcomm expecting laptops to run models of up to tens of billions of parameters. In the device-sensing option, speech recognition such as Whisper, computer vision and text-to-speech run on the phone while a cloud model does the language work, which the company argues cuts both compute and bandwidth.

The third option has device and cloud work on the same response through speculative decoding, a technique published by Google researchers in 2022. Qualcomm’s example has a draft model 7 to 10 times smaller than the target model generate four tokens on the device, which the cloud then checks by running the target model once across the four candidates, since a model like GPT-3 has to read all 175 billion parameters from memory to produce a single token. The company says its own early experiments and published results show 2 to 3 of the 4 draft tokens being accepted on average.

The only on-device demonstration the paper cites is Qualcomm’s own Stable Diffusion run on an Android phone from February 2023. Its other device claims are projections, including text-to-image models generating 3D textures on smartphones within a year and a 13 billion parameter LLaMA model reaching edge devices to voice avatars in XR. On energy the document argues only that edge devices run generative AI at a fraction of the cloud’s consumption once data transport is counted, without giving a figure. The whitepaper is Part I of two, announced in a Qualcomm blog post by Ziad Asghar and Jilei Hou, with Part II covering the company’s own products.

Monday 1 May 2023

MLC LLM brings local language models to iPhone, browsers and consumer GPUs

The MLC project released MLC LLM on May 1, 2023, a compiler and runtime that deploys language models natively on phones, browsers and consumer hardware rather than serving them from a data centre. The team pointed users to a TestFlight build to try the chat app on iOS.

Video: MLC. The iOS app generating a reply on the phone. Open the MLC post

MLC LLM compiles models through the Apache TVM Unity stack and maps them to the Vulkan and Metal graphics APIs, which the team says covers the majority of consumer platforms. Targets named at launch include Windows, Linux, macOS and iOS, plus AMD, NVIDIA, Intel and Apple GPUs and a Steam Deck. A companion project, WebLLM, offloads the same models into web browsers through WebGPU.

Three weeks later the team added RedPajama-3B across the same set of targets, with a browser demo and a command line tool for desktop machines.

The code is on GitHub under the Apache 2.0 license. The project now exposes an OpenAI-compatible API through a REST server as well as Python, JavaScript, iOS and Android bindings, and covers Android GPUs via OpenCL alongside CUDA and ROCm on the desktop.

Thursday 27 April 2023

LaMini-LM distils models from 61M parameters up on 2.58M instructions

Researchers at MBZUAI, the University of British Columbia and Monash University published LaMini-LM on April 27, 2023, a family of 17 distilled instruction-following models ranging from 61M to 7B parameters. The paper gives resource use as the motivation, stating that earlier distilled models of 7B to 13B parameters present “challenges for deployment in resource-constrained settings” and that the authors set out to make deployment in such settings easier. The paper names no target device and reports no memory footprint, no quantisation and no generation speed, and the authors state they trained and evaluated on V100 and A100 GPUs.

The models are fine-tuned on the LaMini instruction dataset, 2.58M instruction and response pairs that the team generated with gpt-3.5-turbo from prompts taken from self-instruct, P3, FLAN and Alpaca. The authors describe it as the largest instruction dataset of its kind at the time and 50 times the size of the dataset behind Alpaca. The students are 6 encoder-decoder models built on T5 and Flan-T5 and 11 decoder-only models built on GPT-2, GPT-Neo, Cerebras-GPT, GPT-J and LLaMA.

The authors evaluated the family on 15 NLP benchmarks with EleutherAI’s lm-evaluation-harness and report that LaMini-Flan-T5-248M performs on par with LLaMA-7B on the benchmark average, against a baseline with about 28 times as many parameters. They warn in the repository that their LLaMA figures are not comparable to the ones the LLaMA authors published, because they re-ran the evaluation themselves. A human rating of 114 user-oriented instructions follows the same size trend and leaves a gap to gpt-3.5-turbo, and the paper reports that the models do poorly on coding, maths and tasks that need reasoning.

MBZUAI publishes the weights and the instruction dataset on Hugging Face. The repository puts the code under Apache 2.0 and the models and the data under CC BY-NC 4.0, and states that both are intended for research use only. The paper was later accepted at the EACL 2024 main conference.

Monday 27 March 2023

Sherpa runs LLaMA on an Android phone through a Flutter chat app

Bip-Rep published Sherpa on March 27, 2023, a Flutter app that runs llama.cpp on the phone itself, so the chat works with no network connection. The README asks users to bring their own weights, Meta’s 7B LLaMA converted to a ggml model file, which the app loads through a file picker, and version 2.1.0 added Vicuna support and macOS builds next to the Android and Windows ones. The project publishes no tokens per second figure and states no minimum memory, and the only device it names is a OnePlus 7 with 8 GB of RAM in the demo video below, which the README says was recorded at real speed. The code is MIT licensed.

Development stopped three weeks after it started. All 43 commits fall between March 27 and April 14, 2023, the last of the seven releases went out on April 14, 2023, and the llama.cpp fork the app builds against was last touched on April 12, 2023, four months before llama.cpp moved to the GGUF format. Sherpa reads the older ggml files rather than the GGUF models that have been standard since, and requests for GGUF support have gone unanswered, with 23 of the 29 issues ever filed still open. A contributor answered one of them by writing that the original developers had abandoned the project, and pointed to his own fork, Maid.

A working chatGPT running on a mobile using llama.cpp

Loading connects your browser to www.youtube-nocookie.com, which may process your IP address and use cookies. Privacy details

Open externally
Video: tibzejoker.

Friday 10 March 2023

Georgi Gerganov publishes llama.cpp, LLM inference in plain C and C++

Georgi Gerganov pushed the first commits of llama.cpp on March 10, 2023, according to the repository’s commit history. The project is an inference engine for Meta’s LLaMA models written in plain C and C++, and the README states its goal as language model and vision-language model inference with minimal setup and state-of-the-art performance on a wide range of hardware, locally and in the cloud.

The core implementation carries no external dependencies. It supports integer quantisation at 1.5, 2, 3, 4, 5, 6 and 8 bits, which is what brings models within reach of consumer memory budgets. Apple silicon is a first-class target through ARM NEON, the Accelerate framework and Metal.

The project has since added backends for x86 with AVX, AVX2, AVX512 and AMX, RISC-V, NVIDIA CUDA, AMD HIP, Moore Threads MUSA, Vulkan, SYCL, OpenCL and WebGPU. It is published under the MIT license.

Thursday 23 February 2023

Qualcomm runs Stable Diffusion on an Android phone for the first time

Qualcomm AI Research has demonstrated Stable Diffusion v1.5, a model with more than 1 billion parameters, running entirely on an Android phone powered by a Snapdragon 8 Gen 2. The company reports image generation in under 15 seconds for 20 inference steps at 512x512 pixels, a workload that until then ran in the cloud.

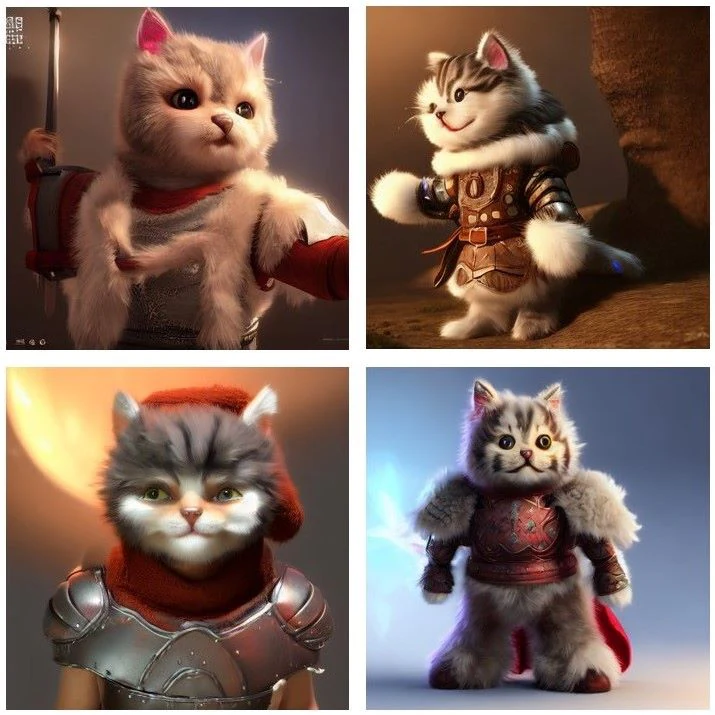
Four generated images arranged in a two by two grid, each showing a fluffy kitten in a different set of armour, one holding a sword and one wearing a red cape
Images: Qualcomm. Sample outputs from the demo, generated on the phone.

To fit the model on the phone, Qualcomm quantised it from FP32 to INT8 using its AI Model Efficiency Toolkit and a post-training method called AdaRound, which adapts how individual weights are rounded. According to the company, the model needed no retraining after the conversion.

Inference runs through the Qualcomm AI Engine direct framework on the Hexagon processor, with the model prepared in Qualcomm AI Studio. The company sums up the result in its post.

This is the fastest inference on a smartphone and comparable to cloud latency.

Sunday 18 October 2020

George Hotz starts tinygrad, a framework that ports to an accelerator in about 25 ops

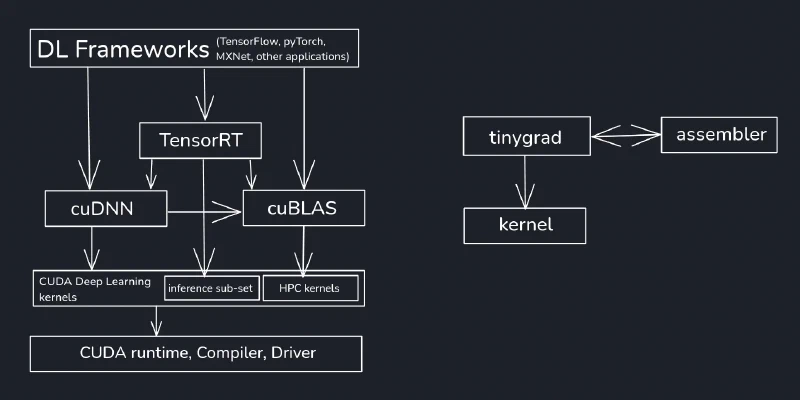
George Hotz pushed the first commit of tinygrad on October 18, 2020, with the message “start tinygrad”, according to the repository’s commit history. The README describes an end-to-end deep learning stack with a tensor library, an autograd, a compiler that fuses and lowers kernels, and a JIT, positioned between PyTorch and karpathy/micrograd. It also states that an accelerator port needs a total of about 25 low level ops. tiny corp, the company Hotz founded, maintains it.

The README lists backends for OpenCL, CPU, Metal, CUDA, AMD, NVIDIA, QCOM and WebGPU. The runtime documentation names the requirements for each one, Adreno 6xx series GPUs for the QCOM backend and M1 or newer Macs for Metal, with Metal 3.0 needed for bfloat support. The QCOM backend, which drives the Qualcomm GPU through the Adreno kernel driver interface instead of OpenCL, entered the repository on September 2, 2024, and the repository also carries a backend for Qualcomm’s Hexagon DSP in ops_dsp.py.

tiny corp states on its site that tinygrad is used in openpilot to run the driving model on the Snapdragon 845 GPU, where it replaces Qualcomm’s SNPE. The company says its framework is faster than SNPE, loads ONNX files, supports training and allows attention, which SNPE does not because it only allows fixed weights. The repository’s test workflow compiles an openpilot model with an image pitch alignment set to match the Adreno 630, the GPU in the Snapdragon 845.

The same workflow enforces the project’s size, failing the build when the repository goes over 26,500 lines as counted by sz.py. The repository ships a language model tool in tinygrad/llm that loads GGUF files, serves an OpenAI compatible API and benchmarks tokens per second, with a built-in model list that starts at quantised Llama 3.2 1B and Qwen3 0.6B. tinygrad is published under the MIT license, and the project recommends installing from source rather than from PyPI.

Block diagram contrasting a CUDA stack of deep learning frameworks, TensorRT, cuDNN, cuBLAS and several kernel layers with tinygrad, which connects only to an assembler and a kernel
Diagram: tinygrad.

Tuesday 29 September 2020

ONNX Runtime 1.5 adds a mobile build that ships only the operators a model uses

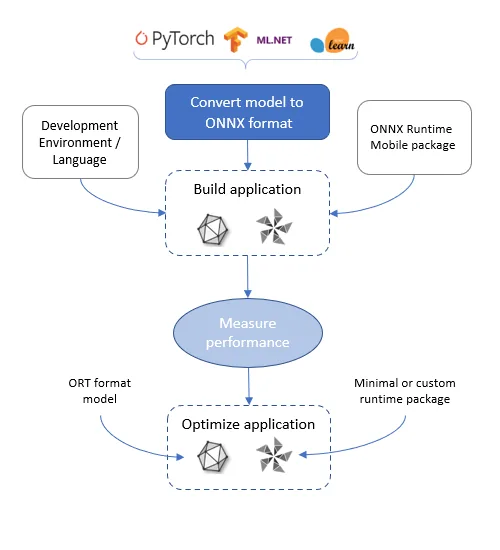
Microsoft released ONNX Runtime 1.5 on September 29, 2020 with a preview of ORT for Mobile Platforms, described in the release notes as minimising build size for mobile and embedded devices. The same release added a reduced operator kernel build, which compiles the runtime with only the operators the target models actually use, and the ORT model format that those reduced builds require. The format documentation records version 1 of the ORT format as introduced in 1.5.

Workflow diagram running from PyTorch, TensorFlow and ML.NET through conversion to ONNX format, then building an application with the ONNX Runtime Mobile package, measuring performance, and optimising with an ORT format model and a minimal or custom runtime package
Diagram: ONNX Runtime documentation.

The pre-built mobile packages, onnxruntime-android for Java, C and C++ and onnxruntime-c and onnxruntime-objc for iOS, carry the full operator set and load .onnx files directly, while a custom build takes models converted to the .ort format. Microsoft’s mobile guide puts numbers on the difference for version 1.18.0, where a custom build supporting the operators of a ResNet50 model produces an Android AAR of 7,532,309 bytes against 24,415,212 bytes for the pre-built package, and an arm64-v8a libonnxruntime.so of 3,962,832 bytes against 16,276,832 bytes.

Accelerators are called execution providers. The NNAPI provider requires Android 8.1 or higher and is recommended on Android 9 or higher, the Core ML provider requires iOS 13 or macOS 10.15 and higher, and the XNNPACK provider covers floating-point CPU work on both platforms. Microsoft’s guidance is to start on the CPU provider for a quantised model and on XNNPACK otherwise, then try NNAPI or Core ML if that misses the performance target. The QNN provider reaches Qualcomm Snapdragon chips on Android and Windows through the Qualcomm AI Engine Direct SDK, with pre-built packages for Windows only and an HTP backend that takes quantised models only.

Quantisation in ONNX Runtime is 8-bit linear quantisation, offered as dynamic and static post-training quantisation in two representations, QOperator with dedicated quantised operators and QDQ with QuantizeLinear and DequantizeLinear pairs inserted around the originals. The mobile guide states that moving 32-bit weights to 8 bits cuts model size by roughly a factor of 4. The tooling also does block-wise weight-only quantisation to int4 and uint4 for MatMul and Gather nodes, with RTN, HQQ and GPTQ algorithms, and models with GatherBlockQuantized nodes need ONNX Runtime 1.20 or later to run.

Generative models run through the separate onnxruntime-genai package, which implements the generation loop, KV cache management, search and sampling around the runtime. Its support matrix lists Android as supported and iOS as on the roadmap, with CPU, QNN, WebGPU, CUDA, DirectML and OpenVINO among the acceleration options. Microsoft reported in April 2024 that RTN int4 quantisation shrinks Phi-3 Mini enough to run on a Samsung Galaxy S21 at what it called a moderate speed, and recommends the int4_accuracy_level=4 variant on mobile. Both projects are published under the MIT license.