All updates

News and context on AI running on mobile devices.

Saturday 5 October 2024

PalmBench finds iPhones running local LLMs about three times faster than Android phones

Researchers at the University of Wisconsin-Madison, Amazon Web Services AI and Uber ran quantised language models across eight phones and edge boards and measured the widest gap between Apple and everything else. In PalmBench, published as a conference paper at ICLR 2025, TinyLlama-1.1B at 4-bit reached close to 100 tok/s on an iPhone 15 Pro against roughly 30 tok/s on the fastest Android phone in the set, a Pixel 7. The authors report that the three-year-old iPhone 12 Pro also stayed ahead of every Android device and of Nvidia’s Jetson Orin Nano.
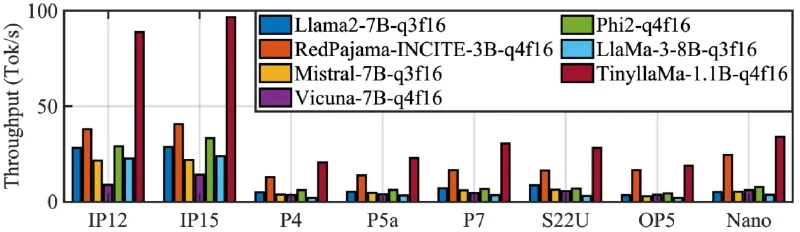
Bar chart of generation throughput in tokens per second for seven quantised models across eight devices, with both iPhones several times faster than the Pixels, the Galaxy S22 Ultra, the Orange Pi 5 and the Jetson Orin Nano
Chart: Li et al., licensed CC BY 4.0. Throughput measured with MLC LLM, which was the only framework that ran on all eight platforms.

The test bed covers a Pixel 4, Pixel 5a, Pixel 7, Galaxy S22 Ultra, iPhone 12 Pro, iPhone 15 Pro, an Orange Pi 5 and a Jetson Orin Nano, each with 6 GB or 8 GB of memory. Models include Llama-2-7B, Llama-3 and 3.1-8B, Llama-3.2-3B, Mistral-7B, Vicuna, Qwen2, Phi-2, Gemma-2-2B, RedPajama-INCITE-3B and TinyLlama-1.1B, quantised from 2-bit to 8-bit and additionally with GPTQ, AWQ and FasterTransformer. The team used two runtimes, MLC LLM and llama.cpp, and states that llama.cpp does not run on iPhone, so the cross-platform numbers come from MLC.

Quantisation costs more answer quality than the bit count alone suggests. Scoring each quantised build’s exact match against the unquantised model’s own answers on SQuAD and Natural Questions, the paper’s figure puts 4-bit builds between about 50 and 61 percent, 6-bit between roughly 62 and 78 percent, and 2-bit and 3-bit builds as low as 15 percent. The authors note that 3-bit did not clearly beat 2-bit, and that 5-bit landed close to 4-bit while consuming more resources and degrading more than any 4-bit variant.
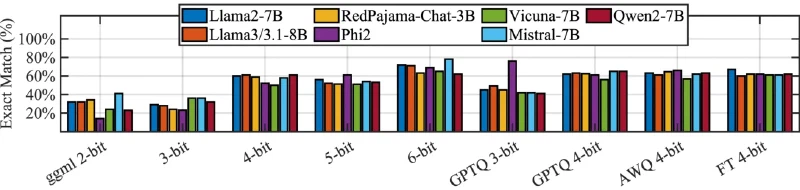
Grouped bar chart of exact match rates for seven models across nine quantisation settings, showing 6-bit highest, 4-bit variants clustered near 60 percent, and 2-bit and 3-bit far below
Chart: Li et al., licensed CC BY 4.0. Exact match is measured against the answers of the same model before quantisation, not against ground truth.

The 4-bit builds drew more power than the 3-bit ones rather than less. The paper’s table records 4-bit consuming more energy on all eight devices for the same 3B Llama model, rising from 10.13 to 13.05 mWh on the iPhone 15 Pro and from 14.54 to 14.68 mWh on the Pixel 7, which the authors put down to the higher-precision build occupying more GPU duty cycles. Surface temperature measured with a FLIR C5 thermal camera peaked at 75.4 °C on the Orange Pi 5 and 46.3 °C on the iPhone 15 Pro at 4-bit. Harmful output tracked the bit count more cleanly, with the hallucination rate on Llama-3-8B at 34.7 percent for 2-bit against 9.1 percent for 4-bit GPTQ and 7.9 percent at 8-bit.

The authors name several limits on their own work. They cannot compare the two runtimes on iOS because llama.cpp does not support the iPhone, they profiled total memory only at 3-bit and 4-bit because higher-bit MLC builds exceeded the devices’ capacity, and they dropped models that would not fit at all, such as the unquantised Llama-2-7B at 13.11 GB. They also note that both runtimes expose few decoding options, with beam search unavailable in llama.cpp. Artificial Analysis has since run an independent benchmark of 33 quantised models on a single iPhone 17 Pro.
Friday 27 September 2024

AMD trains its first small language model, AMD-Llama-135M, on MI250 accelerators

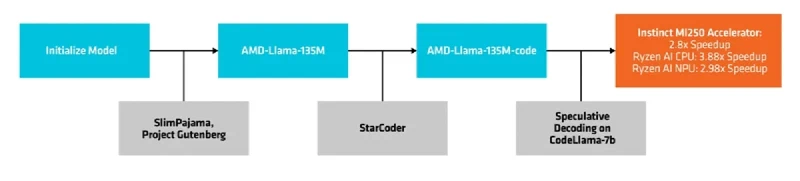
AMD released AMD-Llama-135M on September 27, 2024, its first small language model, at 135M parameters and trained from scratch on AMD’s own accelerators. AMD states that pretraining used 670B tokens drawn from SlimPajama and Project Gutenberg and took six days on four Instinct MI250 nodes holding four MI250 accelerators each. A second variant, AMD-Llama-135M-code, adds 20B tokens from the Python subset of StarCoder over another four days on the same hardware.

That code variant exists to work as a draft model for speculative decoding, where a small model guesses several tokens in one pass and a larger model then checks them, so the larger model can accept several tokens per forward pass rather than producing one at a time. AMD paired it with Meta’s CodeLlama-7b and measured throughput on the HumanEval coding benchmark. AMD reports about 2.8x higher throughput on an Instinct MI250 accelerator, about 3.88x on the CPU of a Ryzen AI processor, and about 2.98x with the 7B model running 4-bit on the Ryzen AI NPU while the draft model ran on the CPU, each against the same setup without speculative decoding. AMD’s footnotes name a Ryzen 9 PRO 7940HS as the test machine for the Ryzen AI numbers.

Flowchart from model initialisation through AMD-Llama-135M trained on SlimPajama and Project Gutenberg, then AMD-Llama-135M-code trained on StarCoder, ending in speculative decoding on CodeLlama-7b with 2.8x on Instinct MI250, 3.88x on Ryzen AI CPU and 2.98x on Ryzen AI NPU
Diagram: AMD, showing its own measured speedups.

AMD published the weights on Hugging Face and the training, dataset and inference code on GitHub, under the Apache 2.0 license. AMD states the training code builds on TinyLlama and uses PyTorch FSDP for distributed training across nodes.

Wednesday 25 September 2024

Meta ships Llama Stack with Swift and Kotlin clients for on-device inference

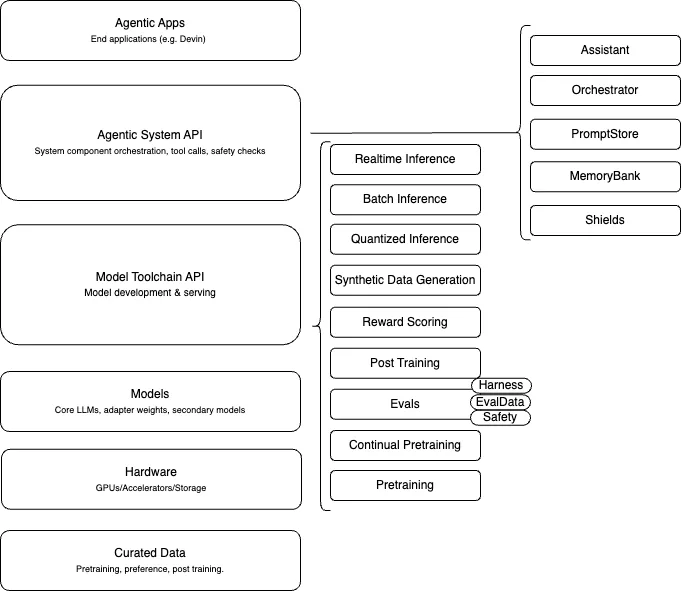
Meta announced Llama Stack at Connect on September 25, 2024, a set of REST APIs plus client SDKs for Python, Node, Swift and Kotlin that cover the same Llama features wherever the model runs. The repository defines APIs for Inference, Safety, Memory, Agentic System, Evaluation, Post Training, Synthetic Data Generation and Reward Scoring, and lists PyTorch ExecuTorch as the on-device provider, covering inference and agents on iOS. The models announced at the same event are covered separately.

Llama Stack separates providers from distributions. A provider is the implementation behind an API, which can be local code or a pointer to a remote service, and a distribution assembles providers behind one endpoint. Meta’s README states that providers can be mixed, that a hobbyist can serve a small model locally and use a cloud provider for a large one, and that the higher level APIs the app works with do not change, including across the server and mobile-device boundary.

Layer diagram stacking curated data, hardware, models, a Model Toolchain API and an Agentic System API under agentic apps, with inference, training, eval and safety endpoints branching off
Diagram: Meta. From the Llama Stack repository documentation.

On iOS the local provider is a Swift class called LocalInference, which the documentation describes as powered by ExecuTorch. It implements the same Inference interface the Swift client uses for remote servers, so an app that already streams chat completions or agent turns keeps its calling code and swaps the service it was given. Developers export the model to an ExecuTorch .pte file, bundle it with tokenizer.model in the app, and link the XNNPACK, Core ML and MPS backends plus the quantized and optimised kernels, with Meta’s own example loading a SpinQuant build of Llama 3.2 1B.

The Swift package is added through Xcode’s package manager and generates its types from the Llama Stack OpenAPI spec, and Meta listed its first release on October 10, 2024. The same iOS documentation stated that on-device inference for Android was coming soon, and pointed developers to ExecuTorch’s own Android demo app in the meantime. Llama Stack, the Swift client and the Kotlin client are published under the MIT license.

Update, December 6, 2024. Meta released version 0.0.54 of the Kotlin client, which adds on-device inference on Android. The README names ExecuTorch as the local inference distributor, has developers run a script that fetches a prebuilt executorch.aar with the XNNPACK delegate into the app’s libs directory, and shows the only difference between the two modes as the client builder, LlamaStackClientLocalClient with a model and tokenizer path against LlamaStackClientOkHttpClient with a base URL. The chatCompletion call that follows is identical.

Meta releases Llama 3.2 1B and 3B for phones and edge devices

Meta released Llama 3.2 on September 25, 2024, including text-only 1B and 3B models built for phones and edge hardware. Both carry a 128K token context window and are aimed at summarisation, instruction following and rewriting that run locally, with the data staying on the device.

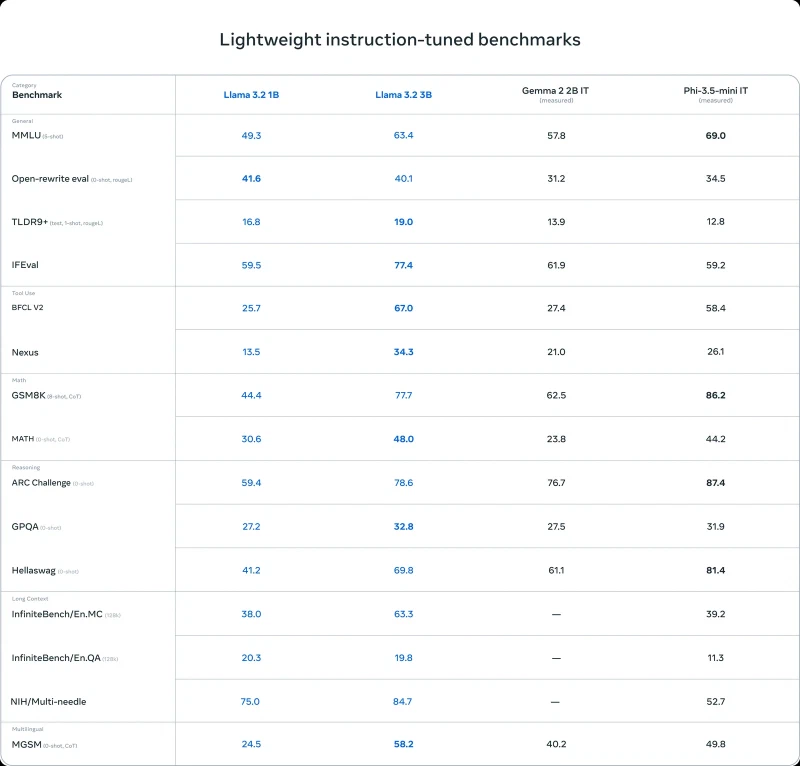
Meta built them by structured pruning from Llama 3.1 8B, then recovered quality through knowledge distillation using logits from the 8B and 70B models during pretraining. The company reports the 3B model ahead of Gemma 2 2.6B and Phi 3.5-mini on instruction following, summarisation, prompt rewriting and tool use, and puts the 1B model on a par with Gemma. In Meta’s own table the 3B model scores 77.4 on IFEval against 61.9 for Gemma 2 2B and 59.2 for Phi-3.5-mini, and 67.0 on BFCL V2 for tool use against 27.4 and 58.4.

Benchmark table comparing Llama 3.2 1B and 3B with Gemma 2 2B IT and Phi-3.5-mini IT across general, tool use, math, reasoning, long context and multilingual tasks
Table: Meta. The company measured the Gemma and Phi results itself.

The models shipped with day-one support for Qualcomm and MediaTek silicon and run on Arm, which Meta says covers 99 percent of mobile devices. Weights are on llama.com and Hugging Face, with deployment paths through PyTorch ExecuTorch for devices and Ollama for single-node setups, and the company lists more than 25 partner platforms at launch.

Saturday 21 September 2024

CoMiGS splits on-device fine-tuning into shared generalists and private specialists

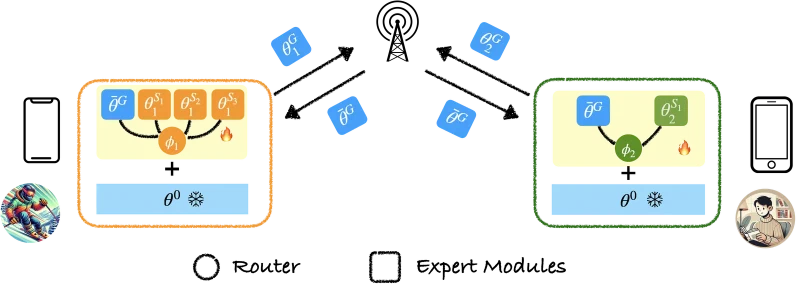
Four researchers at EPFL published CoMiGS on September 20, 2024, a scheme in which many devices fine-tune a language model together, with some of the added model parts shared across everyone and the rest kept on the device that trained them. In a simulation of four users, each holding Wikipedia articles in a different language, the authors measure test perplexity at 47.19 with GPT-2 124M as the base model, against 54.38 when each user trains alone on local data and 58.80 for federated averaging, which pools every user’s update into one shared model. Perplexity measures how surprised a model is by the next token, so lower is better. The paper appeared at ICML 2025.

Nobody retrains the base model. Each device trains small LoRA adapters on top of pretrained weights that stay frozen, and CoMiGS sorts those adapters into two kinds. Generalist adapters are averaged across all devices at every communication round, specialist adapters and a small router never leave the device, and the router decides per token which adapters to use. The authors train that router against a separate validation set rather than the training data, and report that in the first layer of the network common function words such as “and”, “a” and “the” go mostly to the generalists, while for the users trained on maths and programming text the domain-specific terms in the last layer go mostly to the specialists.

Nothing here ran on a phone. The appendix states that every experiment except the centralised baseline ran on a single NVIDIA A100-SXM4-40GB, with four simulated users holding between roughly 400,000 and 1 million training tokens each, drawn from multilingual Wikipedia, SlimPajama, AG News and Common Corpus, and averaged over three seeds. The base models are GPT-2 124M and Llama 3.2 1B. Results in the paper’s table are mixed rather than uniform, with CoMiGS ahead of both baselines on multilingual Wikipedia, SlimPajama and Common Corpus, and behind federated averaging on AG News, at 33.53 against 31.84 with GPT-2 and 16.31 against 15.86 with Llama 3.2 1B, which is the one setup where the test data does not follow the training distribution.

The second set of experiments gives users different numbers of adapters, two to four per device with one of them always a generalist, which is how the method is meant to cope with devices of unequal capacity. Against HetLoRA and FlexLoRA, two methods that vary the LoRA rank per device instead, the authors report lower perplexity on every in-distribution task, for example 18.68 against 21.41 and 24.63 on Common Corpus with Llama 3.2 1B. They put the overhead of their extra router at 1.25 percent more computation per forward pass and 1.25 percent more memory, with communication per round halved against federated averaging because only the generalist weights are sent.

The paper names its own limits. The authors write that differential privacy on the aggregated generalist weights is something they “do not pursue here”, that robustness against attackers is beyond the scope of the work and that their aggregation carries no guarantee against adversarial parties, and that there is a limit to how much the generalists can prevent overfitting when the local task is easy. They also note that fine-tuning Llama 3.2 1B on multilingual Wikipedia or SlimPajama produced negligible improvements, which they attribute to overlap with its pre-training data, and that is why the Llama runs use Common Corpus instead. The code is on GitHub under the Apache 2.0 licence.

Diagram of two users, one with a generalist and three specialist adapter modules feeding a router, the other with a generalist and one specialist, both stacked on frozen base weights, with only the generalist weights travelling out for averaging and back
Diagram: Fan et al., Figure 2 of the paper, licensed CC BY 4.0. The router and the specialists stay on the device.

Sunday 8 September 2024

ElastiLM resizes a shared phone LLM per request and switches in 0.31 seconds

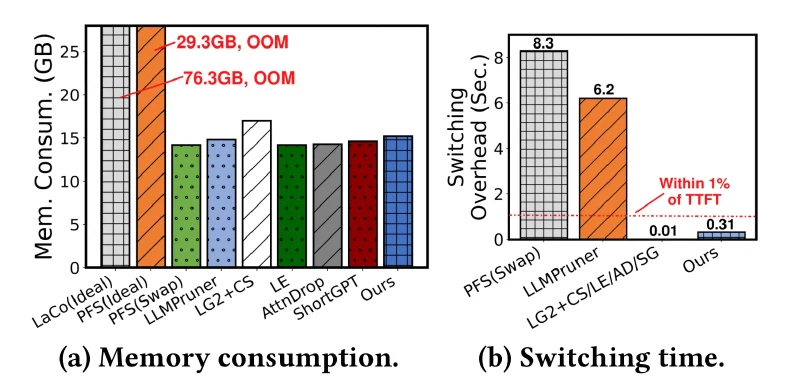
Researchers at Peking University and Beijing University of Posts and Telecommunications published ElastiLM on September 8, 2024, a phone-side language model service that resizes itself for every request. Running LLaMA-7B on a Redmi K60 Champion Edition with a Snapdragon 8 Gen 2, the authors measure 0.31 seconds to switch from one sub-model to another, against 8.3 seconds for swapping in a separately pretrained model of the right size and 6.2 seconds for the pruning method LLMPruner.

The setup the paper assumes is one model held by the operating system that every app calls, the way Android AICore serves apps like Gboard smart reply. Those callers want different things from it, and the authors put an always-on voice assistant that needs an answer almost immediately next to a background screen-event recorder that can wait. ElastiLM takes a latency budget along with each request and then picks how much of the model to run and how much of the prompt to keep, in steps of 10 percent, rather than running one fixed model at one fixed speed.

Accuracy is what pays for the speed. Cutting the prompt drops words the model might have needed and pruning removes whole attention heads and MLP neurons, and the split matters as much as the total, since the authors show one science question that half the prompt with an 80 percent sub-model answers correctly while 80 percent of the prompt with a half-size sub-model gets wrong. Preparing a model costs 68.3 GPU hours on a server with NVIDIA A40s, which the authors price at about $100 of rented time and put at 21.7 to 68.2 hours more than the pruning baselines. The service runs on four big CPU cores, and the authors state that as of August 2024 no mobile GPU or NPU could run ElastiLM or its baselines end to end, so their accelerator figures are projected from profiled latency rather than measured on a device.

Across the Redmi K60 Champion, a Mi 14 and a Redmi K70 Pro, the last two on Snapdragon 8 Gen 3, the authors report ElastiLM answering more requests correctly than seven baselines by 6.60 to 14.83 percent in absolute accuracy, 10.45 percent on average, on traces of 600 requests drawn from six datasets. Peak memory for LLaMA-7B sits at 15 to 17 GB, level with the baselines, while keeping a dedicated model per latency budget would take 29.3 GB or 76.3 GB and runs out of memory on all three phones, which carry 19 GB to 24 GB of RAM. Weight-only quantisation to 8 bits costs almost no accuracy and 4 bits about 3 percent absolute, by the authors’ measurement. The paper appeared at MobiCom 2025 in Hong Kong in November 2025 and is on arXiv under a CC BY 4.0 license.

Two bar charts for LLaMA-7B, peak memory with ElastiLM at about 15 GB among baselines at 14 to 17 GB and two out-of-memory cases at 29.3 and 76.3 GB, and switching time with ElastiLM at 0.31 seconds against 8.3 and 6.2 seconds for the swap and LLMPruner baselines and 0.01 seconds for the layer-level ones
Charts: Yin et al. Online overhead measured on a Redmi K60 Champion Edition, with the dashed line marking 1 percent of average time to first token.

Tuesday 3 September 2024

Ai2 releases OLMoE, 7B parameters with 1B active per token

Ai2 published OLMoE-1B-7B on September 3, 2024, a language model with 6.9B total parameters of which only 1.3B run on any given token. It is a sparse mixture of experts, meaning each layer holds 64 small feedforward networks and a small router picks 8 of them per token, so the rest of the model stays idle. Compute per token lands near that of a dense 1B model, while all 6.9B parameters still have to be held in memory.

Ai2 pretrained the model on 5 trillion tokens and reports in the paper that it leads every open model in its active-parameter class. On MMLU the paper puts OLMoE-1B-7B at 54.1, against 48.5 for DCLM-1B, 33.6 for TinyLlama-1B and 32.1 for Ai2’s own dense OLMo-1B. The paper states the model matches or outperforms the dense OLMo-7B at the end of pretraining while using less than half the training FLOPs, and that it beats Llama2-7B on MMLU, scored at 46.2, despite needing roughly 6 to 7 times less compute per forward pass. The instruction-tuned version is reported above Llama2-13B-Chat and DeepSeekMoE-16B.

For the training-cost claim the authors ran a controlled comparison, training a 1.3B dense model and a 1.3B active, 6.9B total mixture of experts on 128 H100 GPUs for 130B tokens each. Ai2 reports the sparse model reaching the dense model’s final quality with about 3 times fewer tokens and FLOPs, but only about 2 times faster in wall-clock time, because the larger weight set dropped throughput to 23,600 tokens per second per GPU against 37,500 for the dense run. The full pretraining run used 256 H100 GPUs for around 10 days.

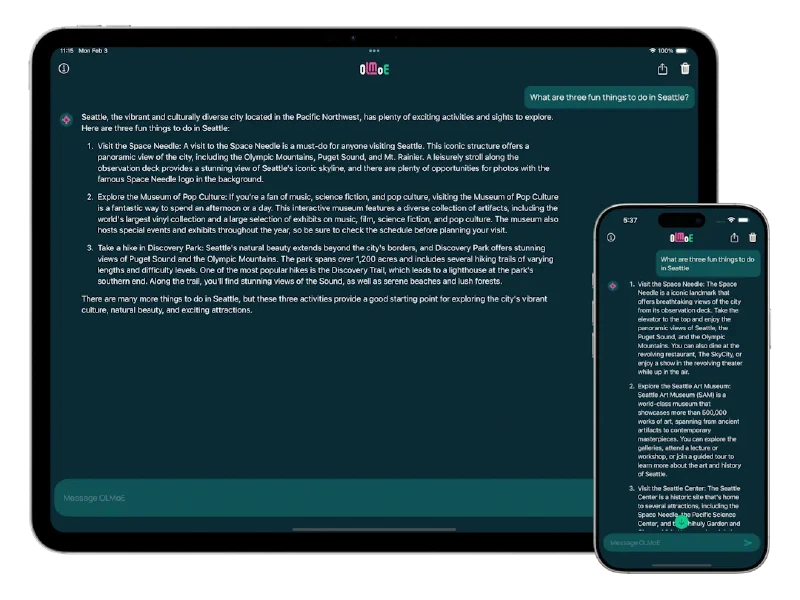
Ai2 shipped an iOS app on February 11, 2025 that keeps the whole model on the device, so prompts and responses never reach a server and generation keeps working in airplane mode. Ai2 names the iPhone 15 Pro and 15 Pro Max, the four iPhone 16 models and M-series iPads going back to the 2021 iPad Pro, and states that the first version needs an iOS device with 8 GB of memory. The app runs a 4-bit quantised build of the January 2025 instruction-tuned model, which Ai2 measures at 41 tokens per second on average on an iPhone 16 Pro, on a stack Ai2 built with GenUI on top of llama.cpp.

Weights, the training data mix, the training code and the run logs are all published under Apache 2.0, together with 244 intermediate checkpoints. The comparison table in the paper lists OLMoE as the only mixture-of-experts release that opens all four, with most of the other models in the table offering a single checkpoint and no logs. The app is in the App Store and its source code is on GitHub.

The OLMoE app on an iPad and an iPhone, both answering the same prompt about things to do in Seattle with a numbered list
Screenshot: Ai2.

Update, April 14, 2025. Ai2 kept working on the app after the February launch and added macOS support on March 7, 2025 through Mac Catalyst, Apple’s compatibility layer that runs the same iOS code natively on a Mac, together with a counter that shows how many tokens a reply used. A later version reworked the panel that reports generation metrics, and the most recent release, from April 14, 2025, renamed the app to Ai2 OLMoE. Nothing has shipped in the repository since.

Wednesday 31 July 2024

Gemma 2 2B is distilled from a larger model and scores 1126 on Chatbot Arena

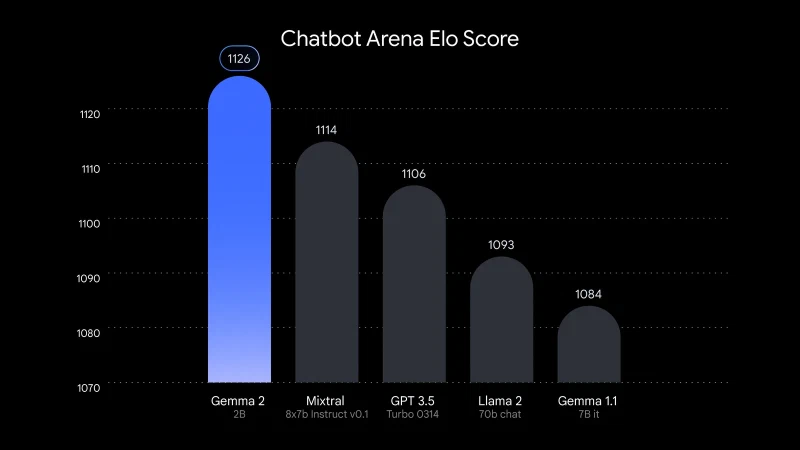
Google released Gemma 2 2B on July 31, 2024, an open model of 2.6B parameters that Google says produces outsized results by learning from larger models through distillation. Google reports it at 1126 Elo on the LMSYS Chatbot Arena leaderboard, captured on July 30, 2024, ahead of Mixtral 8x7B Instruct at 1114, GPT 3.5 Turbo 0314 at 1106 and Llama 2 70B chat at 1093, and states that the model surpasses all GPT-3.5 models there.

Bar chart of Chatbot Arena Elo scores showing Gemma 2 2B highest at 1126, above Mixtral 8x7B Instruct v0.1 at 1114, GPT 3.5 Turbo 0314 at 1106, Llama 2 70b chat at 1093 and Gemma 1.1 7B it at 1084
Chart: Google, from the announcement. Scores are Google's own reading of the leaderboard on July 30, 2024.

The technical report describes training the 2B size on 2 trillion tokens with knowledge distillation, where a bigger teacher model supplies a probability for every token in context and the small student is trained to match those probabilities rather than to predict the next token. In an ablation the authors ran, a 2B model trained over 500B tokens distilled from a 7B teacher averaged 67.7 across three benchmarks, against 60.3 for the same model trained from scratch. The released model holds 2.02B non-embedding parameters plus 590M embedding parameters, which come from the 256k-entry Gemini vocabulary, and it interleaves local sliding-window attention with global attention over an 8192-token context. Google DeepMind trained it on 512 TPUv5e chips.

Google names edge devices and laptops as deployment targets next to cloud serving on Vertex AI and Google Kubernetes Engine, and says the model is small enough for the free tier of T4 GPUs in Google Colab. For running it locally Google points to Ollama and to Gemma.cpp, its own lightweight C++ inference engine, and says support in MediaPipe, the on-device inference stack for Android, iOS and the web, is coming. Google adds that NVIDIA optimised the model with the TensorRT-LLM library for GeForce RTX cards and for Jetson modules at the edge.

Google put the weights on Kaggle, Hugging Face and Vertex AI Model Garden under the Gemma terms, which it calls commercially friendly for research and commercial applications, and made the model available to try in Google AI Studio. The same announcement added ShieldGemma, a set of safety classifiers built on Gemma 2 that filter hate speech, harassment, sexually explicit and dangerous content, and Gemma Scope, over 400 sparse autoencoders for inspecting the inner workings of Gemma 2 2B and 9B.

Tuesday 30 July 2024

torchchat runs Llama 3 8B on a Galaxy S23 and iPhone at more than 8 tok/s

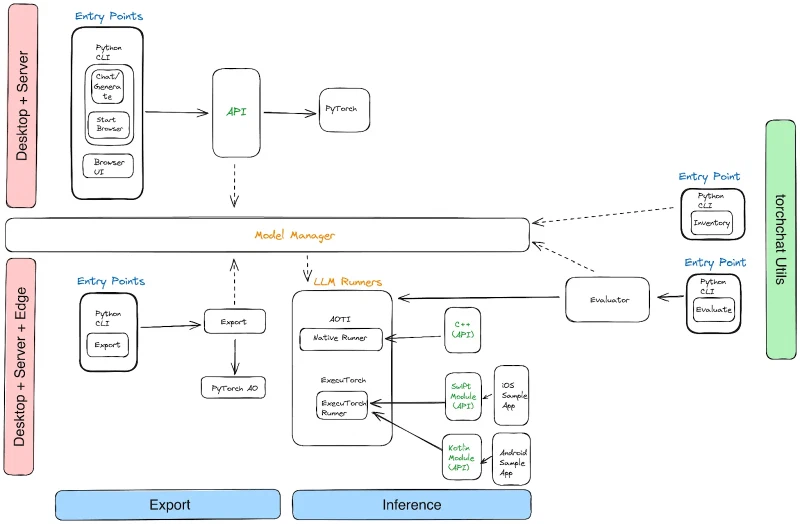
PyTorch released torchchat on July 30, 2024, a small codebase showing how to run Llama 3 and other language models on laptops, desktops and phones. For the phone path the team reports more than 8 tok/s for Llama 3 8B Instruct on a Samsung Galaxy S23 and on iPhone, using 4-bit GPTQ quantisation through ExecuTorch.

Architecture diagram separating a desktop and server path through the Python command line from an export path that feeds an AOTInductor native runner and an ExecuTorch runner with iOS and Android sample apps
Diagram: PyTorch.

The repository names iOS 17 or later with at least 8 GB of RAM as its requirement, which it narrows to iPhone 15 Pro and newer or an iPad with Apple silicon, and on Android any device covered by the XNNPACK CPU backend, with 12 GB of RAM and 20 GB of storage recommended. Its model table marks Llama 3.2 1B and 3B, Llama 3.1 8B, Llama 2 7B, Mistral 7B, IBM Granite 3.1 and DeepSeek R1 Distill 8B as mobile friendly. The 11B vision version of Llama 3.2 and the 13B and 70B Llama 2 checkpoints carry no such mark.

Getting a model onto a phone is one export step that turns a downloaded checkpoint into a .pte file for ExecuTorch, the PyTorch edge runtime that reached version 1.0 in October 2025. The mobile preset shipped in the repository quantises the embedding table to 4-bit in groups of 32 values and the linear layers to 4-bit weights whose activations are quantised to 8-bit at runtime, in groups of 256. The quantisation guide offers 4-bit and 8-bit embeddings at group sizes from 32 to 256 across all execution modes, lists the dynamic-activation scheme as the supported one for ExecuTorch, and notes that smaller groups preserve accuracy while larger ones run faster.

Both demo apps are sample harnesses rather than shipped products. On iOS the repository points at the ExecuTorch LLaMA example project in Xcode, which needs a provisioning profile carrying Apple’s increased memory limit entitlement, after which the model and tokenizer files are copied into the app’s folder on the device. On Android the repository carries its own app skeleton for Android Studio, built against a prebuilt ExecuTorch library, with the model and tokenizer pushed to the phone over adb.

The other two paths in torchchat do not touch phones. One runs the model in Python through a chat and generate command line, a browser interface or a local server, the other compiles it ahead of time with PyTorch’s AOTInductor into a binary that a C++ runner loads on a desktop or server. The code is under a BSD 3-Clause license, and PyTorch halted active development on May 19, 2025, saying vLLM had become the dominant option for server-side inference.

Wednesday 17 July 2024

Spectra ships ternary 3.9B models that match 4-bit quantisation at half the bits

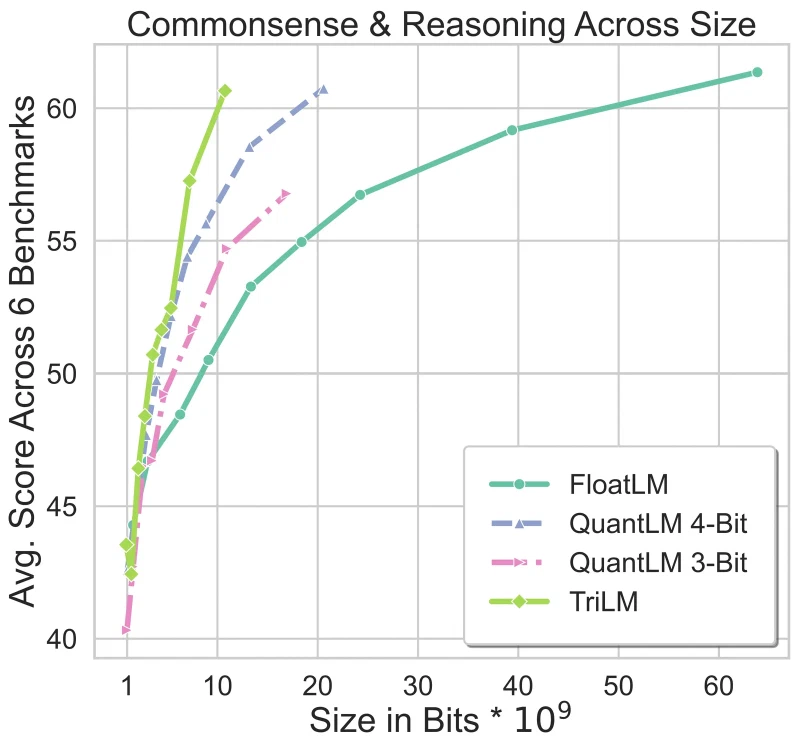
Nolano AI, the University of Montreal and Mila published Spectra on July 17, 2024, a suite of 54 language models covering nine parameter counts from 99M to 3.9B, each trained on the same 300B tokens of SlimPajama. Every size exists as a half-precision model the authors call FloatLM, as GPTQ-quantised copies at 3, 4, 6 and 8 bits called QuantLMs, and as a TriLM, a model trained from scratch with every linear-layer weight restricted to -1, 0 or 1. The paper’s size table puts TriLM 3.9B at 10.76 billion bits, roughly 1.3 GB, against 63.83 billion bits for the half-precision model of the same parameter count, a factor of 5.9.

That is the comparison the suite is built for, since what fits on a device is bits rather than parameters. Averaged over six commonsense and reasoning benchmarks, the paper’s tables put TriLM 3.9B at 60.7 against 61.4 for FloatLM 3.9B, level with the 4-bit QuantLM 3.9B at 60.7 which needs 20.59 billion bits. Set against the models nearest to it in size, TriLM 3.9B beats the half-precision 830M model, 60.7 against 53.3 at 13.34 billion bits, and the 3-bit QuantLM 2.4B, 60.7 against 54.7 at 10.95 billion bits. On LAMBADA it reaches 61.6 against 61.1 for FloatLM 3.9B, and on TriviaQA 21.3 against 21.5.

Line chart of average score across six commonsense and reasoning benchmarks against model size in billions of bits, with the TriLM curve rising above the 4-bit, 3-bit and half-precision curves and ending at 60.7 near 11 billion bits
Chart: Kaushal et al. Averages across Arc Easy, Arc Challenge, BoolQ, HellaSwag, PIQA and WinoGrande.

During training a TriLM keeps floating-point latent weights and ternarises them on the fly in the forward pass, with one scale value per weight matrix shard and gradients passed through by a straight-through estimator, so only the ternary states and the scales are needed at inference. Embeddings and the output head stay in half precision across the suite. The authors position TriLM against BitNet b1.58, which also trains ternary weights from scratch, and say they normalise once before each linear layer instead of normalising, scaling and quantising activations to 8 bits four to seven times per transformer block; their own replication of the BitNet architecture at 1.1B, trained on 100B tokens, scores below TriLM 1.1B on the same benchmarks.

The paper names the weaknesses it measured. At 1.1B parameters the ternary model does not reach its half-precision counterpart, 51.6 against 54.9 on the six-benchmark average, and the 2.4B one still trails at 57.3 against 59.2, so the match with a half-precision model of the same parameter count holds at 3.9B only. On CrowsPairs, which measures how often a model prefers a stereotyped sentence, TriLM 3.9B lands at 65.4 percent against 64.7 for FloatLM 3.9B and 62.6 for the smaller FloatLM 830M, so the ternary model stereotypes more than the half-precision model closest to it in bits. No model in the suite beats random guessing on TruthfulQA, and while TriLM 3.9B holds up on Penn Treebank and LAMBADA perplexity, it stays behind FloatLM 3.9B on web corpora including Dolma, C4 and RefinedWeb, which the authors read as weaker memorisation of training data.

The weights and more than 500 intermediate checkpoints are on Hugging Face under Apache 2.0. The TriLM checkpoints are published unpacked to FP16, which the model cards say makes them compatible with ordinary half-precision matrix multiplication and leaves the released files at full half-precision size. The authors list smartphones, laptops and automobiles among the resource-constrained devices they see for ternary models, and end by calling for work on the toxicity, stereotyping and web-corpus gaps they measured.

Tuesday 16 July 2024

Hugging Face releases SmolLM at 135M, 360M and 1.7B parameters

Hugging Face released SmolLM on July 16, 2024, a family of three base models at 135M, 360M and 1.7B parameters. The team says the models are designed to be small enough to run locally across a range of hardware, from smartphones to laptops, and cites the iPhone 15 with 6 GB of DRAM and the iPhone 15 Pro with 8 GB as reference points. Hugging Face trained the 135M and 360M models on 600B tokens each and the 1.7B model on 1T tokens.

The substance is the training data, released as SmolLM-Corpus. Cosmopedia v2 contributes 28B tokens of synthetic textbooks, stories and articles generated by Mixtral-8x7B-Instruct, 39 million documents built from a predefined list of 34,000 topics taken from the BISAC book classification instead of from unsupervised clustering. FineWeb-Edu contributes 220B deduplicated tokens of educational web pages, pulled out of FineWeb by a quality classifier trained on annotations from Llama3-70B-Instruct. Python-Edu applies the same idea to code, keeping 4B tokens of the 40B Python tokens in The Stack that scored 4 or higher on an educational code classifier.

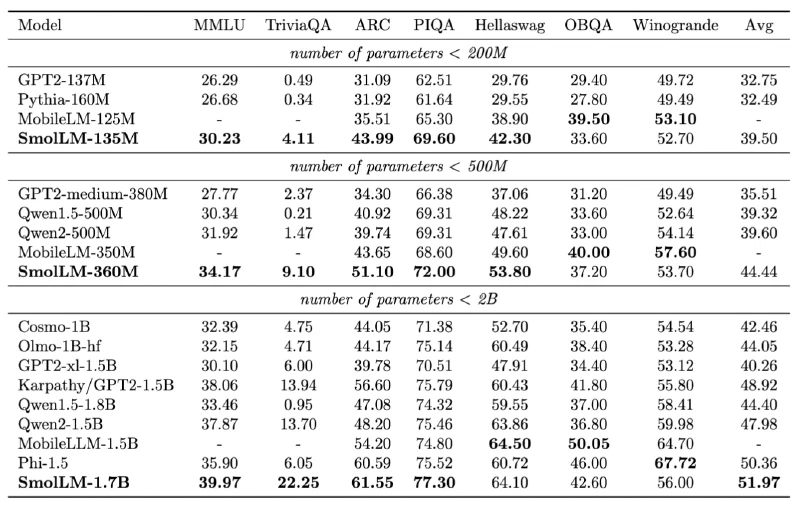
On Hugging Face’s own evaluation, run with the same lighteval setup for every model it could download, SmolLM-135M averages 39.50 across MMLU, TriviaQA, ARC, PIQA, HellaSwag, OpenBookQA and Winogrande, against 32.75 for GPT2-137M and 32.49 for Pythia-160M. SmolLM-360M averages 44.44 against 39.60 for Qwen2-500M and 39.32 for Qwen1.5-500M, and SmolLM-1.7B averages 51.97 against 50.36 for Microsoft’s Phi-1.5 and 47.98 for Qwen2-1.5B. Meta’s MobileLLM is not publicly available, so Hugging Face took its per-benchmark numbers from the paper and reports no average for those rows.

Table of benchmark scores grouped by parameter count, with SmolLM-135M averaging 39.50, SmolLM-360M 44.44 and SmolLM-1.7B 51.97, each the highest average in its group
Table: Hugging Face's own figures, evaluated with the same setup for every model except MobileLLM.

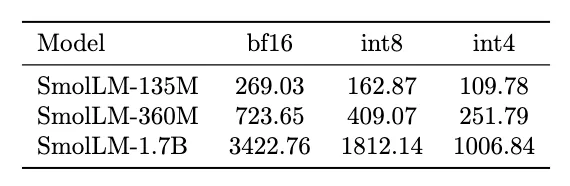
Hugging Face also benchmarked the memory footprint of each size. SmolLM-135M takes 269.03 MB in bf16, 162.87 MB at int8 and 109.78 MB at int4. SmolLM-360M takes 723.65 MB, 409.07 MB and 251.79 MB across the same three precisions, and SmolLM-1.7B takes 3422.76 MB, 1812.14 MB and 1006.84 MB.

Table of memory footprints in megabytes, listing SmolLM-135M at 269.03 in bf16 and 109.78 at int4, SmolLM-360M at 723.65 and 251.79, and SmolLM-1.7B at 3422.76 and 1006.84
Table: Hugging Face.

The weights are on Hugging Face under Apache-2.0, with ONNX checkpoints published beside the transformers ones and a GGUF build for llama.cpp announced as planned. Hugging Face also put up browser demos of the instruction-tuned 135M and 360M models that run client-side through WebGPU, with no server call. The corpus is released separately under ODC-By.

Monday 15 July 2024

Alibaba builds Qwen2's 0.5B and 1.5B sizes for phones, earphones and glasses

Alibaba’s Qwen Team published the Qwen2 Technical Report on July 15, 2024, covering five models from 0.5B to 72B parameters. The report states that the two smallest, Qwen2-0.5B and Qwen2-1.5B, are designed for easy deployment on portable devices such as smartphones, earphones and smart glasses, while the larger sizes target GPUs. Qwen2-1.5B scores 56.5 on MMLU, a multiple-choice knowledge test, against 52.7 for Microsoft’s Phi-2, which the same table credits with about twice the non-embedding parameters.

Both small sizes tie the input embedding to the output layer, so a single weight matrix does both jobs and the shared vocabulary of 151,646 tokens is stored once rather than twice. The report puts non-embedding parameters at 0.3B for Qwen2-0.5B and 1.2B for Qwen2-1.5B. All five models use grouped query attention, where several query heads share one set of key and value heads, with 14 query heads over 2 key-value heads at 0.5B and 12 over 2 at 1.5B, which the authors say lowers the key-value cache size per token against Qwen1.5 and with it the memory footprint during long-context inference.

Alibaba trained Qwen2-0.5B on a 12 trillion token dataset and the other dense models on a 7 trillion token one, reporting that the larger corpus did not pay off at the bigger sizes. For the instruction-tuned versions the report gives Qwen2-1.5B-Instruct 52.4 on MMLU, 61.6 on the GSM8K grade-school maths set and 29.0 on IFEval, which checks whether a model obeys explicit formatting instructions, against 37.9, 40.1 and 20.0 for Qwen2-0.5B-Instruct. The authors attribute the gain over the similarly sized Qwen1.5 models mainly to that data scaling.

Context length differs across the family. The authors tested retrieval from long documents with Needle in a Haystack and report that the two small models handle 32K tokens, Qwen2-57B-A14B-Instruct 64K, and the 7B and 72B instruction-tuned models 128K with the YARN extension applied. The pre-training data covers approximately 30 languages, among them English, Chinese, Spanish, French, German, Arabic, Russian, Korean, Japanese, Thai and Vietnamese.

Alibaba put the weights on Hugging Face and ModelScope. The Qwen2 blog post of June 7, 2024 states that Qwen2-0.5B, 1.5B, 7B and 57B-A14B carry the Apache 2.0 license while Qwen2-72B and its instruction-tuned variant stay on Alibaba’s own Qianwen License, and it names MLX, llama.cpp, Ollama and LM Studio among the projects that run the models locally.