All updates

News and context on AI running on mobile devices.

Monday 8 July 2024

llm.npu prefills 1,106 tok/s for Qwen1.5-1.8B on a Snapdragon 8 Gen 3

Researchers at Peking University and the Beijing University of Posts and Telecommunications published llm.npu on July 8, 2024, an inference engine that runs the prefill stage of a language model on a phone’s NPU. They tested it on a Redmi K70 Pro with a Snapdragon 8 Gen 3 and a Redmi K60 Pro with a Snapdragon 8 Gen 2, using Qwen1.5-1.8B, Gemma-2B, Phi-2 2.7B, LLaMA2-7B and Mistral-7B. On 1024-token prompts on the K70 Pro the authors report prefill 7.3x to 38.4x faster than the CPU engines MNN and llama.cpp and 1.27x to 43.6x faster than the GPU engines TFLite and MLC-LLM, and for Qwen1.5-1.8B they measure 1,106 tok/s against 151 tok/s for MNN on the CPU and 57 tok/s for llama.cpp on the CPU. Energy was measured on the K60 Pro, the only device they could root, where prefill used 1.85x to 59.5x less energy than the same baselines.
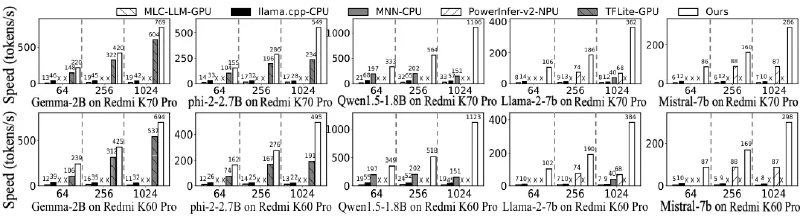
Bar charts of prefill speed in tokens per second for five models on a Redmi K70 Pro and a Redmi K60 Pro, with llm.npu reaching 1106 tokens per second for Qwen1.5-1.8B at a 1024-token prompt against 151 for MNN on the CPU
Chart: Xu et al., published under CC BY 4.0. The prompts come from the LongBench 2WikiMultihopQA dataset.

Prefill is the stage where the model reads the whole prompt before it writes its first token, and the paper puts it at 88.3% to 98.8% of total latency on a mobile CPU for UI automation, chat summaries and context-aware generation, and at 54.2% to 91.7% on a mobile GPU. A mobile NPU is fast at integer matrix multiplication but expects fixed tensor shapes, while prompts arrive at any length, so every new length means rebuilding the graph. Quantised activations also contain outliers, single values far outside the usual range, and the accurate remedy is per-group quantisation, which mobile NPUs cannot execute directly and which the authors measure at up to 10.7x overhead when it is split into sub-tensor multiplications.

llm.npu answers both by cutting a prompt into fixed 256-token chunks that run on pre-built graphs, sharing the operators that do not depend on prompt length so the memory cost drops by up to 4x, pulling the outlier values out to the CPU or GPU to run in parallel, and scheduling transformer blocks across the processors out of order. Accuracy stays within 1% of FP16 on LAMBADA, HellaSwag, WinoGrande, OpenBookQA and MMLU. Across three application workloads, UI automation, context-aware email replies and chat summaries, the authors measure end-to-end latency 1.4x to 32.8x lower than the baselines, with decoding still running unoptimised on the CPU.

The system is built on the group’s own mllm inference framework and Qualcomm’s QNN SDK, in about 10,000 lines of C, C++ and assembly, and the code is public in the mllm repository under an MIT license. The paper appeared at ASPLOS 2025 in Rotterdam in spring 2025. PowerInfer-v2, the one comparison system that also uses the NPU for prefill, is not open source, so the authors took its figures from its paper and report a 3.28x to 5.6x speedup over it.
Friday 21 June 2024

Apple's MobileCLIP-S0 encodes an image in 1.5 ms on an iPhone 12 Pro Max

Five Apple researchers presented MobileCLIP at CVPR 2024 on June 20, a family of image-text models built for phones. They exported each model with Core ML Tools 7.0 and timed it at batch size 1 on an iPhone 12 Pro Max running iOS 17.0.3, and their Table 7 gives the smallest variant, MobileCLIP-S0, 1.5 ms for the image encoder and 1.6 ms for the text encoder at 67.8% zero-shot accuracy on ImageNet. The same authors measure OpenAI’s ViT-B/16 CLIP on that phone at 11.5 ms and 3.3 ms for 68.3%, and both models average 58.1 across the 38 datasets of the DataComp evaluation suite.

Multi-modal reinforced training, the method the paper introduces, moves the expensive part of distillation out of the training loop and into the dataset. Apple reinforces the DataComp dataset once, writing five synthetic captions per image with the CoCa model in OpenCLIP, storing the parameters of strong random image augmentations, 30 per image for the 12M subset and 10 for the billion-sample set, and storing the embeddings that two ViT-L/14 teacher models produce for those augmented images and for the real and synthetic captions. Training afterwards reads the captions and the teacher embeddings from disk, so the captioning model and the teachers never run again however many models are trained on the set.

The paper puts numbers on what that saves. One epoch over the 12.8M samples of the reinforced set on a single node of 8 A100-80GB GPUs takes 1.3 hours, the same as an epoch on the unreinforced data, against 21.1 hours when the captioning model and the teacher ensemble run during training, according to Table 4d. The cost moves to storage, and Table 4c puts DataComp-1B at 90 TB against 140 TB for the reinforced DataCompDR-1B, with the 12M subset going from 0.9 TB to 1.9 TB.

MobileCLIP comes in four sizes, and Table 7 lists image and text encoder parameters separately. S0 pairs an 11.4M-parameter image encoder with a 42.4M-parameter text encoder, S1 uses 21.5M and 63.4M at 2.5 ms and 3.3 ms, S2 uses 35.7M and 63.4M at 3.6 ms and 3.3 ms, and MobileCLIP-B keeps a standard ViT-B/16 image encoder at 86.3M and 10.4 ms. Zero-shot ImageNet accuracy across the four runs 67.8%, 72.6%, 74.4% and 76.8%, and a version of B trained on 39B seen samples instead of 13B reaches 77.2%. All three small variants replace the vision transformer with a convolution-transformer hybrid derived from Apple’s FastViT, and S0 also swaps the text encoder for one that mixes 1-D convolutions with four self-attention layers, which the authors report as 5% smaller and 15.8% faster than the 12-layer transformer text encoder that S1 and S2 keep.

Apple released the code, the weights and the reinforced data at apple/ml-mobileclip, with checkpoints for all four variants and the longer-trained B, and with DataCompDR-1B and DataCompDR-12M on Hugging Face as synthetic captions, augmentation parameters and teacher embeddings keyed to DataComp images rather than as the images themselves. The repository lists the code under MIT, the models under Apple’s own machine learning research model terms, and the data under CC BY-NC-ND. Apple showed zero-shot scene classification running in real time on an iPhone in the CVPR exhibit hall, and added an iOS app for the same task to the repository in November 2024.

Thursday 13 June 2024

TensorOpera releases Fox-1, a 1.6B model trained on 3 trillion tokens

TensorOpera released Fox-1 on June 13, 2024, a decoder-only language model with 1.6B parameters trained on 3 trillion tokens of text and code. The company says the run followed a three-stage data curriculum at 8K sequence length, without saying what each of the three stages contained.

Fox-1 uses grouped query attention, where several attention heads share one set of key and value vectors to cut memory traffic, with 16 attention heads over 4 key-value heads. TensorOpera describes the model as deeper than others of its size, 78% deeper than Gemma-2B, 33% deeper than Qwen1.5-1.8B and StableLM-2-1.6B, and 15% deeper than Apple’s OpenELM-1.1B.

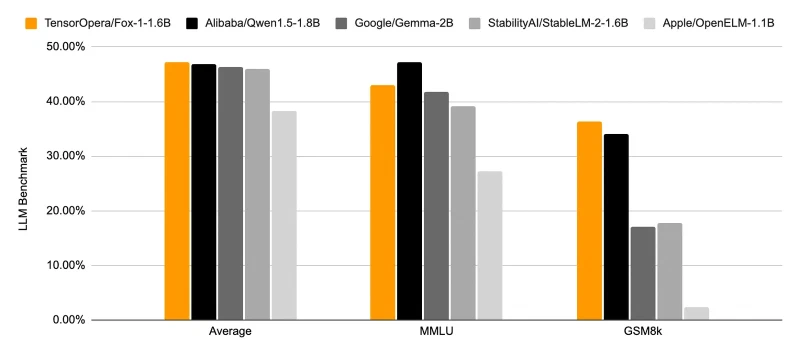
TensorOpera reports an average of 47.13% across ARC Challenge, HellaSwag, MMLU, TruthfulQA, Winogrande and GSM8k, which it ran in the Open LLM Leaderboard setup on one machine with 8 H100 GPUs. It puts Qwen1.5-1.8B at 46.81%, Gemma-2B at 46.36%, StableLM-2-1.6B at 45.92% and OpenELM-1.1B at 38.28%. Fox-1 leads that group on GSM8k with 36.39% against 34.04% for Qwen1.5-1.8B and 17.06% for Gemma-2B, and trails Qwen1.5-1.8B on MMLU with 43.05% against 47.15%.

Bar chart comparing Fox-1-1.6B against Qwen1.5-1.8B, Gemma-2B, StableLM-2-1.6B and OpenELM-1.1B on the six-benchmark average, MMLU and GSM8k, with Fox-1 highest on the average and on GSM8k and second on MMLU
Chart: TensorOpera's own figures.

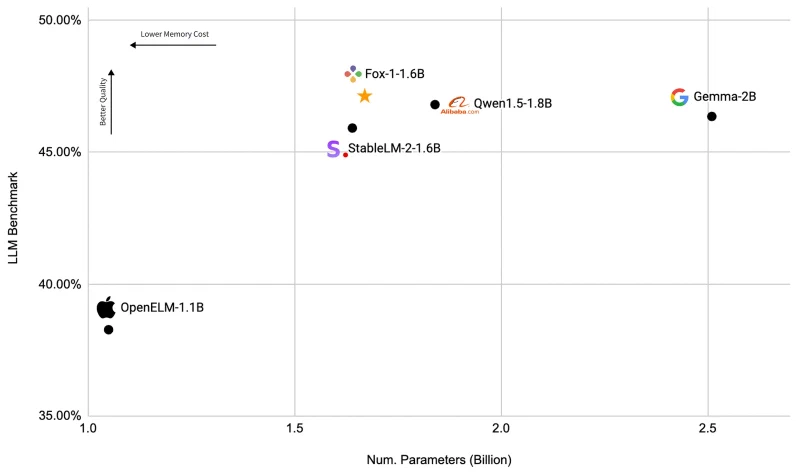
The device claim in the announcement is a target rather than a measurement. TensorOpera puts the model’s FP16 memory use at 3,703 MiB, against 5,379 MiB for Gemma-2B, 4,739 MiB for Qwen1.5-1.8B and 3,852 MiB for StableLM-2-1.6B, and says that makes Fox-1 comparable for on-device deployment. The stated plan is that developers train on the company’s cloud platform and then deploy, personalise and monitor models on smartphones and AI-enabled PCs through its FedML platform. No figure for speed or latency on a phone appears in the post, and the throughput number it does give, over 200 output tokens per second per user, was measured with vLLM on a single H100.

Scatter plot of benchmark average against parameter count showing Fox-1-1.6B at 1.67B parameters scoring above Qwen1.5-1.8B, StableLM-2-1.6B and the larger 2.51B Gemma-2B, with OpenELM-1.1B lowest
Chart: TensorOpera's own figures.

TensorOpera published the base model under the Apache 2.0 license on Hugging Face and on its own platform, and said an instruction-tuned version would follow.

Tuesday 11 June 2024

BUPT measures 22 LLMs on four Android phones at about 200 ms per token

Five researchers at Beijing University of Posts and Telecommunications measured language model inference on four Android phones and presented the results at the EdgeFM workshop of MobiSys 2024, deploying 22 models from 0.5B to 7B parameters through llama.cpp. For the 18 models they charted at 4-bit quantisation, accuracy for most of them sat between 55 and 60 percent, averaged across Winogrande, HellaSwag and MMLU, and latency came out at about 200 ms per token averaged over the four devices. The phones were a Xiaomi 14 with a Snapdragon 8 Gen 3 and 16 GB of RAM, a Pixel 7 Pro with a Tensor G2 and 12 GB, a Xiaomi 12S with a Snapdragon 8 Gen 1+ and 12 GB, and a Meizu 18 Pro with a Snapdragon 888 and 8 GB.

Most of the 7B models needed about 4 GB of memory, which the authors put at half or a third of a current phone’s RAM. Their memory leaderboard has Bloom-7B highest, at 1.27 times the footprint of MPT-7B at the same parameter count, and Qwen1.5 0.5B lowest at under 1 GB. Memory use did not move with input or output length in their runs, with Baichuan holding at 4.83 GB whether the prompt was 10 or 50 tokens long and whether 1 or 1000 tokens were generated, which they trace to llama.cpp allocating one large pool at startup rather than sizing it per phase.

Newer chips helped the two inference phases unevenly. Against the Snapdragon 888, the authors measured the Snapdragon 8 Gen 3 raising prefill throughput on LLaMA 2 by 81% but decode throughput by only 43%, with the Snapdragon 8 Gen 1+ at 45% and 34%. Decode is the phase that emits one token at a time and so governs how fast text appears on screen, and there the gap between the 8 Gen 3 and the 8 Gen 1+ was 7%. Continuous prefill runs also pushed the Xiaomi 12S, Xiaomi 14 and Meizu 18 Pro into thermal throttling, with per-token times drifting during a test series.

The processor comparison went against the GPU in most cases. In the engine test llama.cpp on the 8 Gen 3 CPU prefilled 1.63 times faster than MLC LLM on the same phone’s GPU, 10.3 tokens per second against 6.3, while MLC on the GPU decoded faster at 9.8 against 6.6. On the mid-range Snapdragon 7 Gen 2 the CPU was ahead of the GPU in both phases, 4.59 and 4.65 against 3.3 and 3.5. The authors put this down to mobile GPUs being built for rendering rather than general-purpose compute, and to the extra cost of moving data.

Quantisation cost less than the hardware choices did. Testing eight bit-widths on LLaMA 2, the authors report 4-bit as the best compromise, giving up 0.6% average accuracy against the 32-bit model while cutting model size 8 times, where 2-bit halves the size again for four times the accuracy loss. Code and results are published as TinyLLMLeaderBoard on GitHub, and the six-page paper is free to read in the ACM Digital Library.

Monday 10 June 2024

Apple Intelligence pairs a 3-billion-parameter on-device model with a server model

Apple introduced Apple Intelligence on June 10, 2024, built on a roughly 3-billion-parameter language model that runs on the device and a larger model that runs on Apple silicon servers through Private Cloud Compute. The on-device model uses a 49K token vocabulary, the server model 100K.

Apple compresses the on-device model with a mix of 2-bit and 4-bit weights, averaging 3.7 bits per weight, and says an option at 3.5 bits per weight costs no significant quality. On an iPhone 15 Pro the company reports a time to first token of about 0.6 milliseconds per prompt token and 30 tokens per second, both measured before token speculation.

Rather than ship a separate model per feature, Apple swaps LoRA adapters on top of the shared base model. The adapters are stored in 16 bits and, at rank 16, take tens of megabytes each. Apple says human graders preferred its models over comparable ones including GPT-3.5, GPT-4, Llama, Mistral and Gemma across its evaluations.

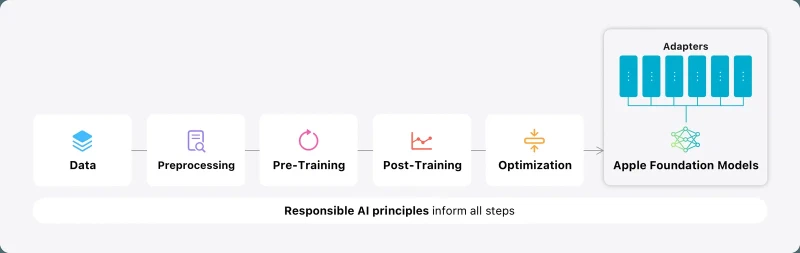
Pipeline diagram running from data, preprocessing, pre-training, post-training and optimisation to Apple Foundation Models, with a stack of adapters on top
Diagram: Apple.

PowerInfer-2 runs a 47B model on a OnePlus 12 at 11.68 tokens per second

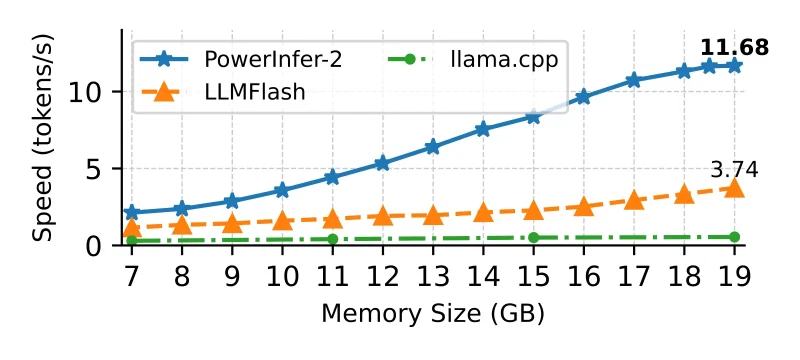
Researchers at the IPADS lab of Shanghai Jiao Tong University published PowerInfer-2 on June 10, 2024, an inference framework for running language models that exceed a phone’s memory. On a OnePlus 12, a Snapdragon 8 Gen 3 device with 24 GB of DRAM of which 19 GB can be occupied by an app, the authors measure TurboSparse-Mixtral-47B decoding at 11.68 tokens per second, and describe it as the first system to serve a 47B model on a smartphone. In the same configuration they report 3.12 times the speed of LLMFlash and 21.2 times the speed of llama.cpp. LLMFlash here is their own reimplementation of Apple’s LLM in a flash techniques inside llama.cpp, which they built because that work was never released as code.

PowerInfer-2 splits each feedforward layer into neuron clusters, small groups of neurons that tend to activate together, and treats a cluster rather than a whole matrix as the unit of work. Frequently activated clusters go to the phone’s NPU for dense arithmetic, while rarely activated ones go to the CPU, which copes better with irregular sparse work. Weights that are not already in an in-memory cache are read from UFS flash on demand, and those reads are overlapped with computation so that a core can work on one cluster while the next is still arriving. For prompt processing the system loads whole layers with sequential reads, which the authors measure at 3 times the throughput of random reads, and prefetches the next layer while the current one computes.

The authors vary how much memory the app may use from 7 GB to 19 GB with the 47B model. At 7 GB the cache holds only 1.8 percent of the feedforward weights, so nearly every neuron has to be fetched from flash for every token and decoding falls to 2.13 tokens per second, which is still 1.84 times LLMFlash. The 47B model activates only about 3B parameters per token thanks to its mixture-of-experts structure and added sparsity, which is why it decodes at roughly the pace of a 7B model in the same test. Streaming weights off storage to fit a large model into a small budget is the same bet Edge0 makes at the level of whole experts rather than individual neurons.

Line chart of decoding speed against available memory from 7 to 19 GB for TurboSparse-Mixtral-47B on a OnePlus 12, with PowerInfer-2 climbing to 11.68 tokens per second while LLMFlash reaches 3.74 and llama.cpp stays near 0.5
Chart: Xue et al. LLMFlash is the authors' own reimplementation of Apple's method.

On OpenCompass at 4-bit weights, the authors put PowerInfer-2 at an average of 78.38 across Arc-Challenge, Arc-Easy, MMLU and GSM8K for Qwen2 7B against 79.25 for llama.cpp, and at 68.35 against 70.12 for Bamboo-7B, with Qualcomm’s QNN engine at 56.93 and 63.26. Token latency is uneven, and for the 47B model with half the feedforward weights offloaded they report a mean of 99.76 ms per token and a 99th percentile of 140.56 ms, tracking a cache miss rate that averages 3.5 percent but reaches 18.9 percent at the 99th percentile. Prompt processing for Bamboo-7B runs at 404.6 tokens per second with half the weights offloaded, against over 700 tokens per second with everything in memory. They measure energy at 0.257 joules per token against 0.373 for QNN and 0.672 for llama.cpp.

PowerInfer-2 uses privileged system calls such as memory locking, so the authors built and ran it on rooted Android phones, and they state that nothing in the design requires kernel changes and that it should port to iOS. It also needs models with predictable sparsity, which is why the group trained sparsified TurboSparse versions of Mistral and Mixtral, and on an unmodified SiLU-based Mistral-7B the gain over LLMFlash drops to 2.4 times against 4.6 times for the ReLU-based Bamboo-7B. The system is 12,000 lines of C++ added to the group’s PowerInfer engine for PCs, which is MIT-licensed, but the announcement there links the paper and the model weights rather than a release of the PowerInfer-2 code. The paper was last revised in December 2024.

Wednesday 29 May 2024

BUPT proposes one 9.2B model in the OS that all apps call through adapters

Researchers at Beijing University of Posts and Telecommunications proposed that a phone ship one shared multimodal model instead of letting every app bundle its own, in a paper published in the ACM MobiCom 2024 proceedings on May 29, 2024. The operating system and the hardware co-manage that model like firmware, unchangeable by apps or by the OS itself, exposed to applications as a system service, and each app reaches it through a small adapter fine-tuned offline for its own task. Their prototype, called M4, holds 9.2B parameters and needs 7.5 GB of peak memory, and the authors report it reaching accuracy comparable to purpose-built models on 85% of the 50 datasets in a benchmark they assembled from 38 mobile AI tasks across five input types.

What the shared model replaces is one small model per app per task. The paper’s baselines are 50 task-specific models of 1M to 500M parameters each, one per dataset, against which M4’s adapters run from 1,000 to 10 million parameters, so each added task costs under 10 MB. Measured on an Nvidia Jetson Orin NX, 4-bit M4 needs 6.1 GB of storage to serve all 50 tasks against 15.2 GB for the 50 separate models, with the crossover at about 15 tasks, and 7.5 GB of peak memory against roughly five times that. The authors state that on a device with 12 GB of memory the 4-bit model plus all 50 adapters fits, where only 20 of the 50 task-specific models would.

The prototype is slower than the models it replaces. On the Jetson Orin NX with 16 GB, the authors measured M4 averaging 18 times the inference latency of the task-specific models across the 50 tasks and 19 times the energy, 3.6 s against 0.2 s. On a Pixel 7 Pro CPU they measured an average of 6.8 s against 0.54 s, and their per-task breakdown puts image classification at 2.10 s and question answering at 6.34 s to the first token and 0.24 s per token after it. They state that M4 cannot currently run on a stock smartphone GPU or NPU at all, because those processors lack support for the operators it uses.

The NPU numbers in the paper are a projection rather than a measurement. The authors estimate that M4 on an NPU would average 0.48 s and 1.3 J, under the 0.54 s and 2.9 J they measured for task-specific models on the Pixel 7 Pro CPU, but they derive that by applying the CPU-to-NPU ratio they observed for task-specific models, not by running M4 on an NPU. Their case for a simpler accelerator rests on a separate Pixel 7 Pro measurement, where they converted 110 downloaded models to TensorFlow Lite and only 8% ran entirely on the NPU, those gaining a median speedup above 20 times over the CPU. M4 itself uses 39 operator types against the 156 that the 50 task-specific models need between them.

The authors name their own limits. They write that the accuracy results come from an A100 and the Jetson board rather than from phones, that M4 underperforms task-specific models on some tasks including translation, and that a prototype assembled from off-the-shelf pre-trained models is “still highly inefficient in terms of accuracy and model parameter size”. Its backbone is Meta’s LLaMA-7B at 8-bit, with encoders taken from ImageBind and Whisper, and they note that adapters trained against one backbone stop working when the backbone is upgraded, so the design still needs a stable interface between the two. Code and benchmark are published at github.com/UbiquitousLearning/MobileFM, and the paper carries ACM copyright rather than an open license.

Tuesday 30 April 2024

ExecuTorch alpha runs Llama 2 7B on iPhone 15 Pro and Galaxy phones

PyTorch released ExecuTorch alpha on April 30, 2024, the first version of its edge runtime aimed at large language models rather than small vision and speech networks. PyTorch says the work enables Llama 2 7B to run on iPhone 15 Pro, iPhone 15 Pro Max and Samsung Galaxy S22, S23 and S24 phones, with early support for Llama 3 8B. The example project shipped with the release reports 8.15 to 11.6 tok/s for the quantised 7B model, measured by PyTorch over adb on a Galaxy S22, a Galaxy S24 and a OnePlus 12. The 0.1 preview from October 2023 had no such path.

Fitting a 7B model on a phone came down to quantisation. Every linear layer carries 4-bit weights in groups of 128 or 256 values, with activations quantised to 8-bit at runtime from their observed range. PyTorch measured WikiText perplexity at 9.16 for the full-precision model against 10.2 and 10.7 for the two group sizes, and notes that groups smaller than 128 were not enabled because the resulting files were still too large, since the embedding table and the weight scales remained in 32-bit floats. Support for 16-bit floats was under way.

Arm, Apple and Qualcomm Technologies worked on the release, and PyTorch describes the mobile accelerator paths through Core ML, MPS, TOSA and the Qualcomm AI Stack as ongoing work rather than finished. The release notes add Snapdragon 8 Gen 3 support and 4-bit and 16-bit quantisation on the Qualcomm side, over 100 operators on Apple’s MPS backend, and a Vulkan delegate for mobile GPUs. PyTorch also credits Google for joint work on XNNPACK, the CPU library that carried the language model numbers, and says MediaTek was enabling the Llama models on its own chips.

PyTorch was explicit about what alpha did not yet do. The release notes mark XNNPACK as the only finished performance path for generative models and everything else as in progress, and the announcement calls on-device LLM support early while asking the community for help building GPU and NPU delegates and expanding the quantisation schemes. Meta was already shipping the runtime elsewhere, using it for hand tracking on Quest 3, for several models on the Ray-Ban Meta smart glasses and in a beginning rollout inside Instagram. The Python package became installable from PyPI with this release.

Tuesday 23 April 2024

Apple releases OpenELM at 270M to 3B, with parameters spread unevenly across layers

Apple posted OpenELM to arXiv on April 22, 2024, a family of four language models at 270M, 450M, 1.1B and 3B parameters, each also released in an instruction-tuned version. The name stands for Open-source Efficient Language Models, and the efficiency comes from layer-wise scaling, which spreads the parameter budget unevenly across the transformer’s layers instead of giving every layer the same shape. Table 1 of the paper gives the 1.1B model an average of 45.93% across the OpenLLM leaderboard tasks against 43.57% for OLMo 1.2B, a gap the authors state as 2.36%, reached on 1.5T pre-training tokens against OLMo’s 3.0T.

Layer-wise scaling varies the number of attention heads and the width of the feed-forward network from layer to layer, keeping layers near the input narrower and widening them towards the output, so a layer late in the stack holds more parameters than an early one. Apple trained the four variants for 350k iterations with its CoreNet library on public data only, drawing on RefinedWeb, a deduplicated PILE, a subset of RedPajama and a subset of Dolma v1.6, about 1.8T tokens in total. Text is filtered and tokenised on the fly rather than pre-tokenised, using the same tokeniser as Llama.

The paper benchmarks the models on an Apple MacBook Pro with an M2 Max chip and 64 GiB of RAM running macOS 14.4.1, through a port of OpenELM to MLX v0.10.0, and separately on a Linux workstation with an Intel i9-13900KF and an NVIDIA RTX 4090. On the MacBook in BFloat16, Apple measures the 270M model generating 212.40 tok/s and the 3B model 33.96 tok/s, with the 4-bit versions at 256.35 and 60.33 tok/s. On the CUDA machine OpenELM 1.08B is slower than OLMo 1.18B, at 92.15 tok/s against 203.40, which the authors attribute to a naive RMSNorm implementation and to OpenELM having 113 normalisation layers where OLMo has 33.

Apple presents the release as the complete framework rather than weights and inference code, covering the training and evaluation code for public datasets, the training logs, multiple checkpoints, the pre-training configurations and the code that converts a model to MLX for inference and fine-tuning on Apple devices, with pre-converted bf16 and 4-bit checkpoints for all four sizes. The eight models are on Hugging Face and the code is in CoreNet. Both the model cards and CoreNet name the terms as the Apple sample code license, which is Apple’s own license and not one of the standard open source licenses.

Monday 22 April 2024

Microsoft runs Phi-3-mini offline on an iPhone 14 at over 12 tokens per second

Microsoft introduced Phi-3-mini on April 22, 2024, a 3.8-billion-parameter model trained on 3.3 trillion tokens. The technical report puts it at 69 percent on MMLU and 8.38 on MT-bench, which the authors say rivals models such as Mixtral 8x7B and GPT-3.5.

Quantised to 4 bits the model occupies about 1.8 GB, small enough for a phone. The report describes the test directly.

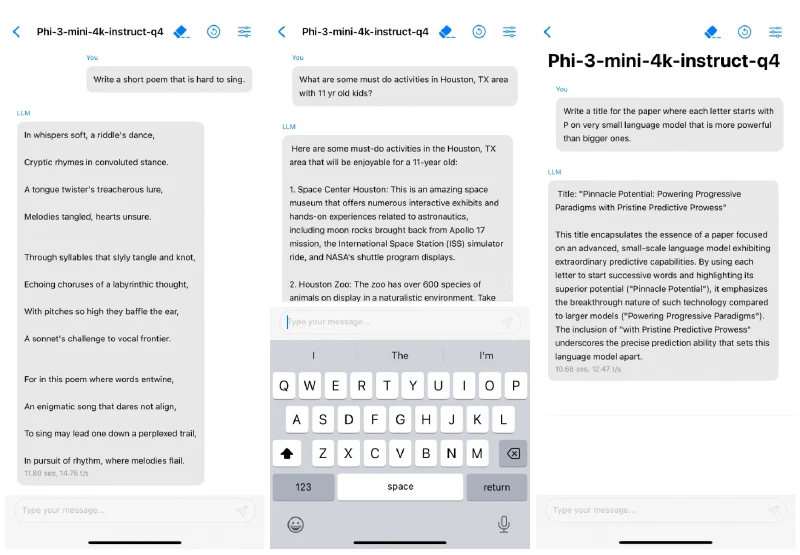
We tested the quantized model by deploying phi-3-mini on iPhone 14 with A16 Bionic chip running natively on-device and fully offline achieving more than 12 tokens per second.

Three iPhone screenshots of a chat app labelled Phi-3-mini-4k-instruct-q4 answering prompts, with timings of 11.80 seconds at 14.75 tokens per second and 10.66 seconds at 12.47 tokens per second
Screenshots: Microsoft, Figure 1 of the technical report.

The same report covers two larger siblings, Phi-3-small at 7B parameters and Phi-3-medium at 14B, both trained on 4.8 trillion tokens. Microsoft reports 75 percent on MMLU for the small model and 78 percent for the medium one.

Wednesday 17 April 2024

Octopus v3 picks an action from an image and a query in under 1B parameters

Wei Chen and Zhiyuan Li posted Octopus v3 on April 17, 2024, a technical report on a multimodal agent model that takes an image alongside a text query and answers with a function call. The model has fewer than 1B parameters, handles English and Chinese in one set of weights, and is built to run on edge devices. The paper lists both authors at Stanford University and gives a Nexa AI address for correspondence.

The model encodes each supported function as a single functional token in its vocabulary, learned the way a language model learns an unfamiliar word from the contexts it appears in, so the output is one token for the action plus its arguments and needs no parser to read. Images run through a CLIP-based encoder, which the authors say they chose after comparing encoding methods. Training runs in stages, with the language model and the image encoder trained apart, then merged and aligned, then taught the functional tokens using the method from Octopus v2, and finally tuned by reinforcement learning with another large language model acting as the reward model.

The evaluation consists of 10 smartphone functions converted into functional tokens and ten worked examples, each printing the model’s output next to the output of GPT-4V feeding GPT-4, which the authors prompted with all the function descriptions and a few examples. The authors write that their model performs comparably to that pair on the selected functions. The report carries no accuracy rate, no success rate and no benchmark table, so the comparison rests on the ten printed generations rather than on a measured score.

The report states that the model runs on devices as constrained as a Raspberry Pi and that it makes converting a Raspberry Pi into something like a Rabbit R1 or a Humane AI Pin practical with an on-device model instead of a cloud service. It names no Raspberry Pi board, no phone and no other hardware it was run on, and gives no latency, no memory footprint and no throughput, so the edge deployment is asserted rather than shown. The authors do name one cost themselves, writing that vision input may introduce considerable latency and that they were optimising inference speed.

Weights and inference code were available only on application when the report went up, which describes the model as still under testing and for research purposes only, and the authors state that the functional token is licensed. The project page that hosted the demo videos no longer resolves. The authors list audio and video as the modalities they want to support next.

Tuesday 2 April 2024

Octopus v2 is a 2B model that calls Android APIs with one token per function

Wei Chen and Zhiyuan Li published Octopus v2 on April 2, 2024, a 2B function-calling model fine-tuned from Google’s Gemma 2B that turns a spoken or typed request into an Android API call. On their own evaluation set built from 20 Android APIs, the authors report 99.524% accuracy and 0.38 seconds per call for Octopus v2, against 98.571% and 1.02 seconds for GPT-4. Both authors give Stanford University as their affiliation on the paper and publish the weights under the name Nexa AI.

The distinguishing idea is what the authors call a functional token. Each of the 20 APIs gets its own special token added to the tokenizer and to the model’s output head, so picking a function becomes a single choice among 20 token candidates instead of writing the function name out as text and hoping every piece of it lands correctly. Since the model learned during fine-tuning what each of those tokens stands for, the function descriptions no longer have to sit in the prompt, which the paper puts at over 95% less context. Retrieval-augmented function calling processes roughly 1,000 tokens per call in their comparison, while Octopus v2 sees the query alone, typically under 30 tokens.

Shorter context is also where the speed comes from. The authors measure Llama-7B with retrieval-augmented function calling at 68.095% accuracy and 13.46 seconds per call on a single NVIDIA A100, and Octopus v2 at 0.38 seconds under the same settings on the same A100, a 35-fold difference. The phone figure is a separate measurement. With the model quantised and the state for the fixed prompt prefix precomputed, they report a function call finishing in 1.1 to 1.7 seconds for queries of 20 to 30 tokens on what the paper calls a standard Android phone, without naming the device, and they estimate 37 times more calls per iPhone battery charge than a 7B model with retrieval.

The authors name limits of their own result. Training with LoRA instead of the full model drops accuracy to 99.048%, and cutting the training set from 1,000 to 100 generated examples per API drops it to 98.095%, which they still put forward as the low end of a usable range. The set of callable functions is fixed at training time, since every API has to exist as a token before the model can emit it, and they price the data generation at 0.0224 USD per 1,000 examples per API. They also note that the GPT-3.5 and GPT-4 latencies were taken through OpenAI’s API on March 18, 2024, and may reflect API traffic or hardware allocation at that moment.

Nexa AI released the weights on Hugging Face under a non-commercial CC BY-NC 4.0 license, on top of Google’s Gemma 2B. The model card said at the time that the team was still preparing the code for an open-source release.