All updates

News and context on AI running on mobile devices.

Tuesday 2 April 2024

Octopus fine-tunes a 2B model to 93 percent on API function calls

Wei Chen, Zhiyuan Li and Mingyuan Ma of Stanford University and Harvard University posted Octopus on April 2, 2024, four open models fine-tuned to pick the right software API for a request and fill in its arguments. On a benchmark the authors built themselves, they report their fine-tuned Gemma 2B answering 93 percent of calls correctly against 96 percent for GPT-4 and 50 percent for GPT-3.5, with the CodeLlama 7B and Gemma 7B versions reaching 97 percent once an output filter is switched on.

The title says on-device, but nothing in the paper runs on a device. The authors fine-tuned the models on A100 80GB GPUs and queried GPT-4 and GPT-3.5 through OpenAI’s API, so every number was measured server-side. The device claim is a single sentence stating that models of this size can already be deployed on mobile, pointing at MLC LLM, and the paper names no phone, no chip and no latency, memory or throughput figure.

The training set starts from roughly 30,000 of the most used APIs on RapidAPI Hub, which GPT-4 cut to about 20,000 by dropping entries with missing arguments or descriptions that did not match their parameters. The authors rewrote each API as a Python function signature with a docstring, had GPT-4 write five answerable queries per API and an equal share of unanswerable ones, and let GPT-4 verify the result, ending at about 150,000 examples as described in the paper. Vector search over the function descriptions pulled in near-identical functions as distractors, and training worked through them from easy to hard.

Base models were CodeLlama 7B, Gemma 2B and 7B and Stable Code 3B, all tuned with LoRA at rank 16 and 8-bit quantisation, using 90 GPU hours for CodeLlama 7B and Gemma 7B, 60 for Stable Code 3B and 30 for Gemma 2B. The output filter the authors call a conditional mask blocks, at each generated token, anything that would break the expected format, so a function name has to come from the known list and an argument has to match its declared type. The authors state that it cannot be applied to GPT-4 or GPT-3.5 because the OpenAI API does not return the underlying token scores, and that GPT-3.5 was not counted wrong for formatting mistakes.

The paper states that the training dataset and the fine-tuned models will be open sourced soon, and names no repository or date. The preprint went up under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 license.
Monday 18 March 2024

One shared on-device LLM keeps a context per app and switches in 0.27 seconds

Researchers at Peking University, the Beijing University of Posts and Telecommunications and Tsinghua University published LLMS on March 18, 2024, an operating system service that keeps a separate conversation context for every app calling one shared on-device language model. Serving eight active contexts of Llama2-7B on a Jetson Orin NX, the authors measure 0.27 seconds to switch to another app’s context. They report switches up to 20 times and on average 9.7 times faster than a baseline that swaps the same chunks but quantises every one to 8 bits, modelled on the server system vLLM.

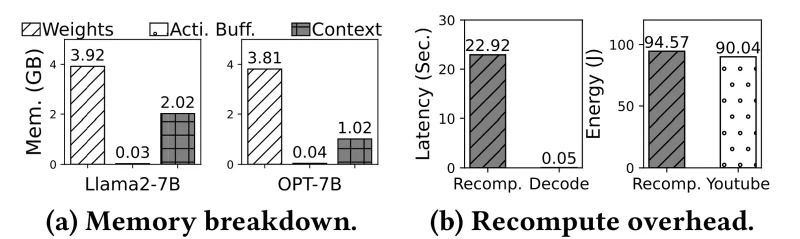
The premise is one model held by the operating system instead of a copy inside each app, the way Android AICore serves Google apps, with every caller keeping its own KV cache, the stored attention state that lets a model continue a conversation without rereading it. On a Xiaomi 14 running llama.cpp, the authors measure one Llama2-7B context at the full 4k-token window at 2.02 GB, against 3.92 GB for the 4-bit weights, so a few apps holding contexts outweigh the model they all share. Letting the phone’s low-memory killer reclaim that memory means rebuilding the context by running the text through the model again, which the authors put at 22.92 seconds and 94.57 J on the same phone, close to the 90.04 J they measure for one minute of YouTube.

What moves to storage is the KV cache, cut into chunks of 16 tokens, while the prompt and output text stay resident. The service quantises each chunk to 8, 4 or 2 bits according to how much attention its tokens draw from the rest of the context, holding a 50 percent average set by the system, then refills a context by reading some chunks from disk while recomputing others from the stored text and overlapping the two. The authors report twice the compression ratio of static quantisation at negligible accuracy loss, where compressing every chunk alike to 4 bits or 2 bits costs up to 59 percent and 99 percent of accuracy.

Each of the three techniques carries part of that 0.27 seconds, which the authors break down as 0.42 seconds without the per-chunk compression, 0.62 seconds without the eviction order and 1.62 seconds without the read-and-recompute pipeline. The prototype is 3.5k lines of Python and C++ on Hugging Face Transformers and mllm, run on a Jetson Orin NX, a Jetson TX2 and a Xiaomi 14 with a Snapdragon 8 Gen 3, each with 8 GB of RAM, using Llama2-7B and OPT-6.7B over 72-hour traces synthesised from six datasets, and the authors state that it leaves token generation speed within 5 percent of running without it. The paper is on arXiv under a CC BY 4.0 license, and the same four authors published the work at SenSys 2026 in Saint-Malo in May 2026 as An Efficient Context Management System for On-Device LLMaaS.

Two chart groups for a Xiaomi 14, memory for Llama2-7B split into 3.92 GB of weights, 0.03 GB of activation buffers and 2.02 GB for one context, with OPT-7B at 3.81, 0.04 and 1.02 GB, and recompute cost at 22.92 seconds against 0.05 seconds to decode a token and 94.57 J against 90.04 J for a minute of YouTube
Charts: Yin et al. Measured on a Xiaomi 14, with the memory breakdown taken on llama.cpp.

Thursday 7 March 2024

Google ships an experimental MediaPipe LLM Inference API for web, Android and iOS

Google released the MediaPipe LLM Inference API on March 7, 2024, an experimental way to run language models fully on device from web, Android and iOS apps. Four open models are supported at launch, Gemma 2B, Phi 2, Falcon 1B and Stable LM 3B.

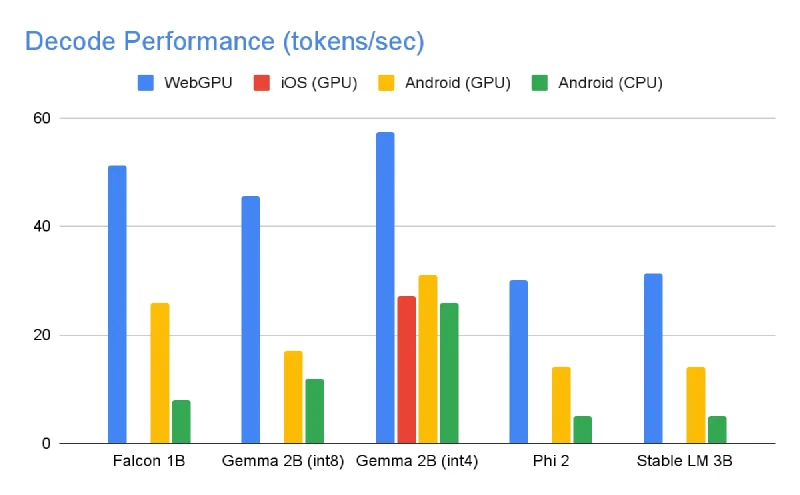
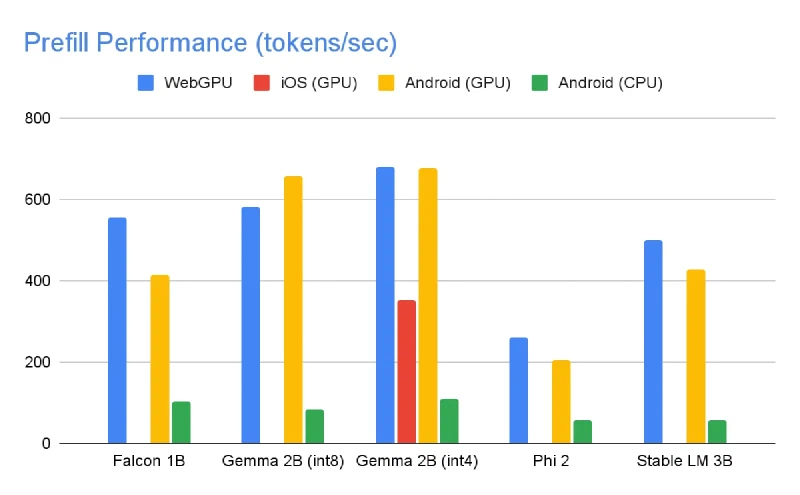
The API quantises weights to int8, with Gemma 2B using mixed 4-bit and 8-bit weights. Google measured throughput on unnamed high-end devices with a 1024-token input prompt and a maximum of 1280 tokens. In its charts, Gemma 2B at int4 prefills at roughly 680 tokens per second on WebGPU and on an Android GPU, and decodes at about 57 tokens per second on WebGPU against 31 on an Android GPU and 27 on iOS.

Bar chart of prefill speed in tokens per second for Falcon 1B, Gemma 2B at int8 and int4, Phi 2 and Stable LM 3B across WebGPU, iOS GPU, Android GPU and Android CPU
Chart: Google.
Bar chart of decode speed in tokens per second for the same five models and four runtimes, topping out near 57 tokens per second for Gemma 2B at int4 on WebGPU
Chart: Google. Gemma 2B at int4 was the only model that ran on iOS.

Google marks the Android version as intended for experimental and research use only, and points production apps to the Gemini API or to Gemini Nano through Android AICore instead. On iOS, Gemma 2B at int4 was the only model the team could run, which Google attributes to the memory available on the platform.

Wednesday 28 February 2024

MeRino designs sub-100M language models that run 4.9 times faster than OPT-350M

Researchers at the University of Central Florida and the University of Technology Sydney published MeRino on February 28, 2024, a method that draws up a transformer architecture to fit a given device’s limits on parameters, arithmetic and latency, instead of shrinking an existing model to fit. Their largest design, MeRino-64M, reaches the same 0.408 average accuracy across twelve zero-shot tasks as Meta’s OPT-350M while carrying 64M parameters against 331M. The authors time it at 114 ms against 559 ms for a 128-token input on an NVIDIA Jetson Nano, or 4.9 times faster.

The search scores a candidate architecture without ever training it. Each candidate shape, meaning how many blocks it has and how wide and how deep each block is, gets a single number that the authors compute from the dimensions of its attention and feedforward matrices and treat as a measure of how much information the network can represent, with a second term that penalises shapes which are deep and narrow, because those train badly. An evolutionary algorithm mutates block widths and depths for 100,000 rounds, discards everything that breaks the budget, keeps the highest-scoring survivors and returns the best one. A precomputed lookup table stands in for the matrix decomposition the score would otherwise need, and the authors put its average error at 0.03 percent.

Because the score is arithmetic over an architecture’s dimensions rather than a forward pass, the search runs on the target board itself. The paper puts one MeRino search at 0.05 hours and 0.75 Wh on the Jetson Nano’s CPU, against 1.2 hours and 300 Wh for the TE-NAS architecture search on an NVIDIA GTX 1080Ti. Every device measurement in the paper comes from that Jetson Nano developer board, taken at batch size 1 and sequence length 128 and averaged over 16 runs, and the authors report no measurements on phones or tablets. Training the designed models is separate and conventional work, at 600,000 steps on 8 NVIDIA H100 GPUs.

The same tables show MeRino-64M behind OPT-350M on language modelling, at 22.47 against 18.51 perplexity on WikiText-2 and 27.06 against 23.08 on Penn Treebank, where lower is better. The smallest design, MeRino-52M, matches Pythia-70M at 0.383 average zero-shot accuracy and 48 ms against 95 ms. The authors state that the weights and evaluation for Meta’s MobileLLM were not released when they submitted, so they do not compare against it, and they report that 8-bit weight quantisation leaves accuracy almost unchanged while 4-bit costs about 1 percent. The work was accepted at AAAI 2025 and the paper names no code release.

Tuesday 27 February 2024

Stability AI trains Stable LM 2 1.6B on seven languages and 2 trillion tokens

Stability AI published the Stable LM 2 1.6B technical report on February 27, 2024, describing a decoder-only model of 1.6B parameters trained from scratch on roughly 2 trillion tokens of public data. The mix is multilingual by design, with web text in German, Spanish, French, Italian, Dutch and Portuguese alongside English, and the report states the finished model handles all seven. The model has 24 layers and a context length of 4096 tokens, which the authors list as one of the things they want to extend.

In the report’s multilingual table, which averages translated versions of four English benchmarks and a next-word prediction set across those seven languages, the base model scores 40.5, above Google’s Gemma 2B at 39.8 with 2.5B parameters and Microsoft’s Phi-2 at 34.6 with 2.7B. The chat variant reaches 41.5 and Stability’s own 3B model 41.7. The authors state they used no multilingual data during fine-tuning, so the language coverage comes out of pre-training alone.

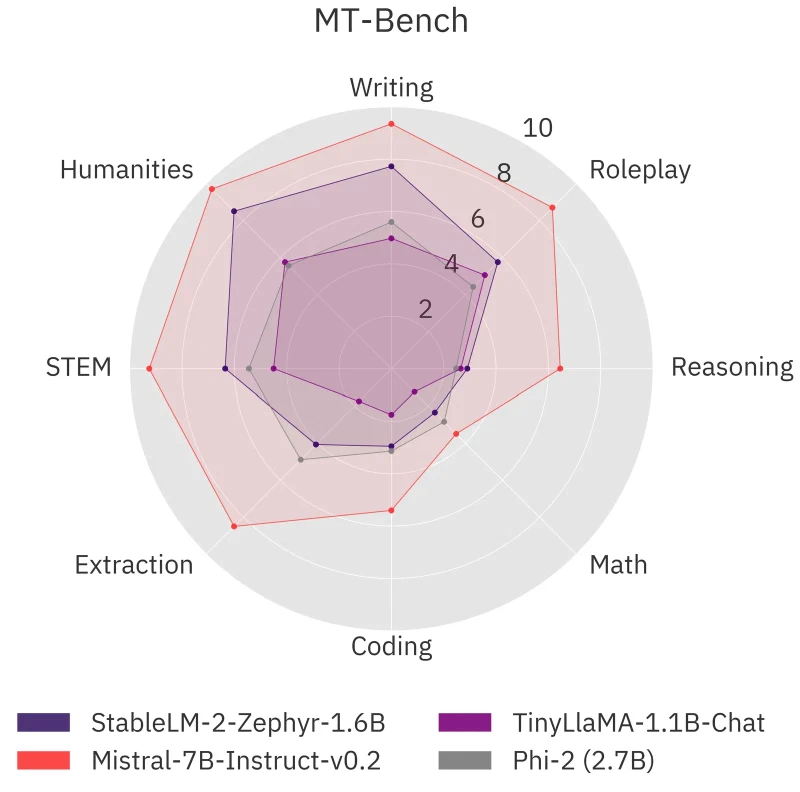
On the six English tasks of the Hugging Face Open LLM Leaderboard, the same report’s table puts the base model at an average of 45.3, behind Alibaba’s Qwen 1.5 1.8B at 46.6 and Gemma 2B at 46.5. The instruction-tuned StableLM 2 Zephyr 1.6B averages 49.7, the highest of the sub-2B entries in that table, ahead of Phi-1.5 at 47.7 and behind the 2.7B Phi-2 at 61.3. The report’s abstract calls Stable LM 2 1.6B the state-of-the-art open model under 2B parameters at the time of publication.

Stability built the Zephyr variant in three stages. It fine-tuned the base model on seven public instruction datasets, 826,938 samples after dropping conversations longer than eight turns, then aligned the result with direct preference optimisation, which trains on pairs of preferred and rejected answers, using UltraFeedback and Intel’s Orca Pairs and borrowing most hyperparameters from the recipe behind Hugging Face’s Zephyr 7B. A third stage taught the model who made it and what a language model cannot do, using 10,000 opening messages the base model wrote for itself. The variant scores 5.42 on MT-Bench, where a larger model judges answers to open-ended questions, above Qwen 1.5 1.8B Chat at 5.29 and Gemma 2B Instruct at 5.19 and below Stability’s own StableLM Zephyr 3B at 6.64.

Radar chart of eight MT-Bench categories comparing StableLM-2-Zephyr-1.6B, Mistral-7B-Instruct-v0.2, TinyLlaMA-1.1B-Chat and Phi-2, with Mistral widest on every axis and the 1.6B model ahead of Phi-2 on writing, humanities and roleplay but behind it on coding and extraction
Chart: Bellagente et al., the authors' own figures.

Stability put both sets of weights on Hugging Face along with quantised builds for llama.cpp, Apple’s MLX and Intel’s OpenVINO. The report measures 127 tok/s at 11 W for the 4-bit MLX build on an M2 Mac mini with 8 GB, against 71 tok/s at 6 W in FP16, and 99 tok/s for a 4-bit GGUF build on a 2023 MacBook Pro with 16 GB, while stating these figures are meant as a practical reference rather than rigorous benchmarking. Neither release is open source. The report says the model ships under a non-commercial licence, the Zephyr model card names the Stability AI Non-Commercial Research Community License and points commercial users to the company, and the base model card now carries the Stability AI Community License with commercial use running through a Stability membership.

BitNet b1.58 gives every weight three values and runs 3B in 2.22 GB

Microsoft Research and the University of Chinese Academy of Sciences published BitNet b1.58 on February 27, 2024, a language model in which every single weight is one of three values, -1, 0 or 1. At 3B parameters the authors measure it at 2.22 GB of memory against 7.89 GB for a full-precision Llama-style model of the same size trained on the same number of tokens, a 3.55 times reduction, with a slightly lower perplexity of 9.91 against 10.04.

Three possible values need log2(3) bits to store, which is roughly 1.58 and where the name comes from. What that buys is a change to the matrix multiplication that dominates the work of running a model. A normal model multiplies each weight by an activation in floating point and sums the products, but multiplying by -1, 0 or 1 is only a sign flip, a skip or a copy, so the paper states that the matrix multiplication of BitNet “only involves integer addition”. Activations stay at 8 bits.

The models are trained from scratch at this precision rather than trained in full precision and squeezed down afterwards, which is how most low-bit models on phones are produced today. The authors trained BitNet b1.58 and their own reproduced Llama baseline on the same data for the same number of tokens at each size, and compare the two directly. They report that BitNet b1.58 starts to match the full-precision baseline in perplexity at 3B and on zero-shot end tasks from 3B as well, where it averages 50.2 against 49.7.

The efficiency figures widen with size. Memory drops 2.60 times at 700M, 2.93 times at 1.3B and 3.55 times at 3B, and latency per output token falls 1.23 times, 1.67 times and 2.71 times across the same three sizes. For throughput the authors ran 70B models on two A100 cards and report a batch size of 176 against 16 and 2977 tokens per second against 333, an 8.9 times gain. They also calculate that on 7nm chips the arithmetic for matrix multiplication costs 71.4 times less energy, because integer addition is far cheaper than floating-point multiply-accumulate.

The paper names no model release and its arXiv listing marks it as work in progress. The authors argue the approach suits CPUs, “which are the main processors used in edge and mobile devices”, and say the lower memory and energy cost is what would let such models run there. They close by calling for new hardware and systems designed specifically for 1-bit models.

Update, April 16, 2025. Microsoft released BitNet b1.58 2B4T, a 2B model trained from scratch on 4 trillion tokens at ternary precision, which the team calls the first open-source native 1-bit model at that scale. The report puts its non-embedding memory at 0.4 GB against 1.4 GB for Gemma-3 1B and 2.6 GB for Qwen2.5 1.5B, measures CPU decoding at 29 ms per token on a 13th Gen Intel Core i7-13800H using 8 threads against 41 ms and 65 ms for the same two models, and estimates energy at 0.028 J against 0.186 J and 0.347 J. Across the benchmark suite it averages 54.19, above Llama 3.2 1B at 44.90 and just under Qwen2.5 1.5B at 55.23. The weights are on Hugging Face, with a custom CUDA kernel for GPUs and CPU inference through bitnet.cpp, the runtime Microsoft published in October 2024 and measured at 2.37 to 6.17 times faster than the baseline on x86 CPUs and 1.37 to 5.07 times faster on ARM.

Monday 26 February 2024

MobiLlama is a fully transparent 0.5B model that runs in 770 MB on a phone

Researchers at MBZUAI published MobiLlama on February 26, 2024, a language model of 0.5B parameters aimed at devices that cannot host a large one. The stated aim is a fully transparent small model rather than open weights alone, so the authors release the complete pre-training data pipeline, the training and evaluation code, the weights and more than 300 intermediate checkpoints. They also derive a 0.8B version from the same design.

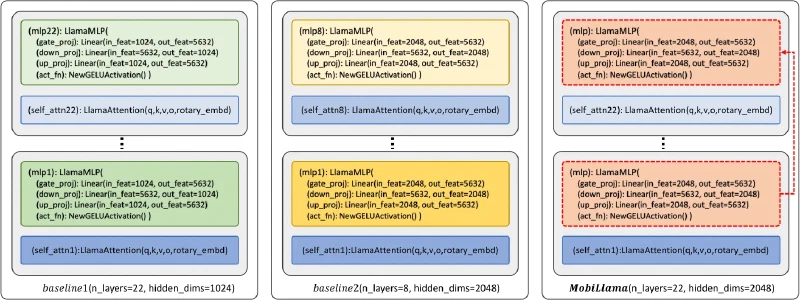
The design point is a single feed-forward block shared by every transformer layer. Each transformer block normally carries its own feed-forward network, the part that reworks each token’s representation after attention, and the authors measure those layers as 65% of all trainable parameters in their 1.2B reference model. Reusing one block across all 22 layers cuts trainable parameters by 60%, from 1.2B to 0.52B, while keeping the 22 layers and the hidden size of 2048 that the reference model has. The authors report pre-training the shared version in 7 days and 26.6K A100 GPU hours, against 12 days and 46.1K hours for the unshared 1.2B model.

Three side-by-side transformer stacks, the two baselines giving every block its own MLP module and MobiLlama routing all blocks to one shared MLP marked in red
Diagram: Thawakar et al.

For deployment the authors measured a smartphone with a Snapdragon 685, a laptop with an i7 CPU and a desktop with an RTX 2080 Ti, using 4-bit GGUF builds on the phone and the laptop. On the phone they put MobiLlama 0.5B at 770 MB of RAM and 7.02 tok/s, drawing 5.32 mAh per 1,000 tokens at 13.02% CPU utilisation. They measured Llama 2 7B on the same phone at 4287 MB, 1.19 tok/s and 10.07 mAh per 1,000 tokens with 77.41% CPU utilisation, and Phi-2 2.7B at 1893 MB and 2.88 tok/s. On the laptop CPU the 0.5B model reaches 36.32 tok/s in 799 MB.

MobiLlama 0.5B averages 46.00 across nine benchmarks from the Open LLM Leaderboard in the authors’ own evaluation, which they compare with 43.57 for pythia-410m, and the 0.8B version, made by widening the shared block, averages 46.67. The models were pre-trained on 1.2T tokens from the Amber dataset of LLM360, where the two largest parts are a curated web crawl and code. Weights and chat-tuned variants are on Hugging Face under Apache 2.0, and the repository carries the training code and an Android app package for running the model on a phone.

Qualcomm AI Hub opens 75 pre-optimised models and profiling on hosted Snapdragon phones

Qualcomm launched Qualcomm AI Hub at Mobile World Congress in Barcelona on February 26, 2024, a developer service built around a model library of more than 75 pre-optimised AI and generative AI models for Snapdragon and Qualcomm platforms. Qualcomm states that spreading each model across the NPU, CPU and GPU of its AI Engine results in 4X faster inferencing times.

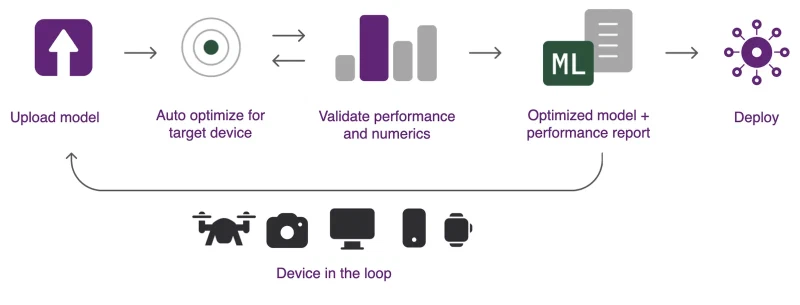
The second half of the service is measurement. A developer uploads a trained model, the hub compiles it for a chosen chip and runtime, then runs it on a physical Snapdragon device in Qualcomm’s cloud and returns latency, memory use and a numerical check against the original, as the documentation describes. The same measurements are published for every catalogue entry, which is why each model page names the handset the figures came from.

Workflow diagram running from upload model, to auto optimize for target device, to validate performance and numerics, to optimized model plus performance report, to deploy, with a loop back through drones, cameras, monitors, phones and watches labelled device in the loop
Diagram: Qualcomm.

At launch the export recipes in Qualcomm’s repository covered two runtimes, TensorFlow Lite and Qualcomm AI Engine Direct, on Android 11 and newer, in FP16, INT8 and INT4. The supported chips ran from the Snapdragon 845 through the Snapdragon 888 to the Snapdragon 8 Gen 3, with Samsung Galaxy S21 to S24, Xiaomi 12 and 13 and Google Pixel 3 to 5 handsets named as targets. Everything is driven from a Python package called qai_hub.

Two of the listed models generate text, Llama-v2-7B-Chat and Baichuan-7B, both quantised to 4-bit weights and 16-bit activations. Qualcomm’s model card puts Llama-v2-7B-Chat at 3.6 GB with a maximum context of 1024 tokens, and reports it measured on a Samsung Galaxy S23 Ultra running Android 13 on a Snapdragon 8 Gen 2, on the NPU, at 117.8 ms for each additional token and 2,578.5 ms to push a full 1024-token prompt through before the first token comes back. Peak memory for the token generator is 66 to 238 MB.

Qualcomm publishes the models on the AI Hub site, on GitHub and on Hugging Face, and names no price for the service, asking only for a Qualcomm ID to sign in and an API token to submit jobs. The licensing is layered. Qualcomm’s export and optimisation code is BSD 3-Clause, each model keeps the licence of the original implementation, so Llama-v2-7B-Chat stays under Meta’s terms, and the compiled assets prepared for on-device deployment carry a separate Qualcomm AI Hub Proprietary License.

Thursday 22 February 2024

Meta's MobileLLM trades width for depth and gains 2.7 and 4.3 points

Meta Reality Labs researchers published MobileLLM on February 22, 2024, a family of language models built to run on a phone rather than in a data centre. The paper argues that below a billion parameters the shape of the network matters more than the parameter count or the amount of training data. Its 125M and 350M models beat the previous best models at those sizes by 2.7 and 4.3 points on eight zero-shot common sense reasoning tasks.

The central finding is that depth beats width. The authors trained 19 models of roughly equal size but different proportions, 9 around 125M parameters and 10 around 350M, and report that 30-layer and 42-layer designs scored higher than the 12-layer shape used by OPT, GPT-Neo and Pythia at the same size. Sharing one weight matrix between the input embedding and the output layer removes 16M parameters, about 11.8% of a 125M model, for a 0.2 point accuracy drop the authors then recover by spending the freed budget on two more layers. Grouped query attention, where several query heads read one shared set of key and value heads, cuts 16 key-value heads to 4 at close to the same accuracy.

The paper sets out what a phone can actually spare. The authors put DRAM on current handsets at 6 to 12 GB, shared with the operating system and every other app, and argue that an app should not claim more than 10% of it. For energy they use a rule of thumb of 0.1 J per token per billion parameters, which puts a 7B model at 0.7 J/token, drains 0.2% of an iPhone battery every 64 tokens and allows under 2 hours of conversation at 10 tok/s. A 350M model with 8-bit weights costs 0.035 J/token by the same arithmetic, which the authors say covers a full day of use.

Meta also profiled the models on hardware rather than estimating. Running the 125M model in FP16 through ExecuTorch on an iPhone 13 with iOS 17.2.1 and the Metal Performance Shaders backend, the authors measured 39.2 ms to load, 1361.7 ms to initialise and 15.6 ms to execute, the last averaged over 50 runs. MobileLLM-LS, the layer-sharing variant, computes each transformer block twice in a row so that 30 blocks of weights behave like 60 layers at the same file size, a pattern the team picked over the alternatives because the repeated weights stay in the roughly 20 MB of on-chip cache instead of being fetched from DRAM again. That costs 2.2% more loading and initialisation time and 2.6% more execution time, against 143% and 86% for a model that really has 60 layers, and adds 0.7 and 0.8 points of accuracy at 125M and 350M.

After fine-tuning, MobileLLM-350M scores 3.28 on the MT-Bench chat benchmark against 1.37 for OPT-350M and 2.24 for the 1.3B OPT, and the layer-shared 350M wins 48.2% of AlpacaEval comparisons against text-davinci-001, a model that wins 50% against itself. For API calling the team built a synthetic set of 5,000 training and 2,500 test conversations that turn requests such as setting an alarm into a function call, and MobileLLM-350M scored 65.3 on intent exact match against 62.8 for Llama 2 7B, while trailing the larger model on the structure of the call and on the wording of the reply. Quantising weights and activations to 8 bits costs under 0.5 points. The work was published at ICML 2024 and the code is in Meta’s repository.

TinyLLaVA's 3.1B model outscores 7B LLaVA-1.5 on seven of nine benchmarks

Researchers at Beihang University and Tsinghua University posted TinyLLaVA on February 22, 2024, a framework for building small vision-language models out of an existing language model and an existing image encoder. Their best configuration, which the paper calls TinyLLaVA-3.1B, scores higher than the 7B LLaVA-1.5 on seven of the nine benchmarks in the paper’s comparison table, ties it on GQA at 62.0, and trails it on MME, where the same table gives LLaVA-1.5 1510.7 against 1464.9. The authors report 79.9 against 78.5 on VQAv2 and 75.8 against 63.4 on LLaVA-Bench-in-the-Wild, and put the model ahead of the 7B Qwen-VL on four of the five benchmarks they share, behind it on TextVQA at 59.1 against 63.8.

The framework treats four things as variables, the small language model, the vision encoder that turns an image into patch features, the connector that maps those features into the language model’s embedding space, and the training recipe. The authors instantiate it with TinyLlama at 1.1B, StableLM-2 at 1.6B and Phi-2 at 2.7B as language models, CLIP at 0.3B and SigLIP at 0.4B as vision encoders, and either the 558k-caption LLaVA-1.5 data or the 1246k-caption ShareGPT4V data. Their base recipe updates only the connector during pre-training, while their share recipe freezes the first 12 layers of the vision encoder and updates the rest of the model.

The ablations put most of the movement in the vision encoder and the recipe. Swapping CLIP for SigLIP raises the Phi-2 variant’s TextVQA score from 51.4 to 55.6 and the TinyLlama variant’s from 45.8 to 49.1, which the authors attribute in part to SigLIP running at 384 pixels against 336 and emitting 729 visual tokens against 576. A two-layer MLP connector beat a resampler on four of six benchmarks in the single comparison the paper runs, 74.0 against 70.1 on VQAv2 and 58.1 against 54.2 on GQA, with the resampler ahead on SQA-I and MM-Vet. The authors report that the share recipe, which fine-tunes part of the vision encoder rather than freezing all of it, improved every variant pre-trained on ShareGPT4V.

Model size still helps when data and recipe are held fixed, and with CLIP under the base recipe the Phi-2 variant leads the StableLM-2 and TinyLlama ones on all seven benchmarks in the appendix table. The ordering flips once the recipe changes, with the 1.5B SigLIP TinyLlama model on the share recipe beating the 1.9B CLIP StableLM-2 model on the base recipe on six of seven benchmarks. The authors add a hallucination caveat, reporting that the share recipe lowers POPE accuracy for the StableLM-2 and Phi-2 variants even as their other scores rise, and they conjecture that smaller language models need more trainable parameters during pre-training while larger ones suffer from them.

The paper carries no on-device measurement. It states no latency, no memory footprint and no target hardware, and argues the small-scale case from training and inference cost rather than from phone or edge deployment. The authors wrote that weights and code would be made public, and the project repository and the 3.1B weights carry the Apache 2.0 license.

Wednesday 21 February 2024

Gemma 2B and 7B open the Gemma line, built on Gemini research

Google released Gemma on February 21, 2024, the first two models in the line, at 2B and 7B parameters and in a pretrained and an instruction-tuned checkpoint each. The technical report presents the 7B as a model for deployment on GPU and TPU and the 2B as one for CPU and on-device applications. Google says Gemma was built from the same research and technology used to create Gemini and shares technical and infrastructure components with it.

Both sizes are decoder-only transformers trained on a context length of 8192 tokens. The 2B has 18 layers, a model dimension of 2048 and a single key-value head, since Google’s ablations found multi-query attention works well at small scale, while the 7B has 28 layers and keeps standard multi-head attention across 16 heads. Both inherit Gemini’s 256k-entry vocabulary, which puts 524M of the 2B’s parameters into embeddings and leaves 1.98B elsewhere. Google reports training the 2B on 3T tokens and the 7B on 6T, mostly English web documents, mathematics and code.

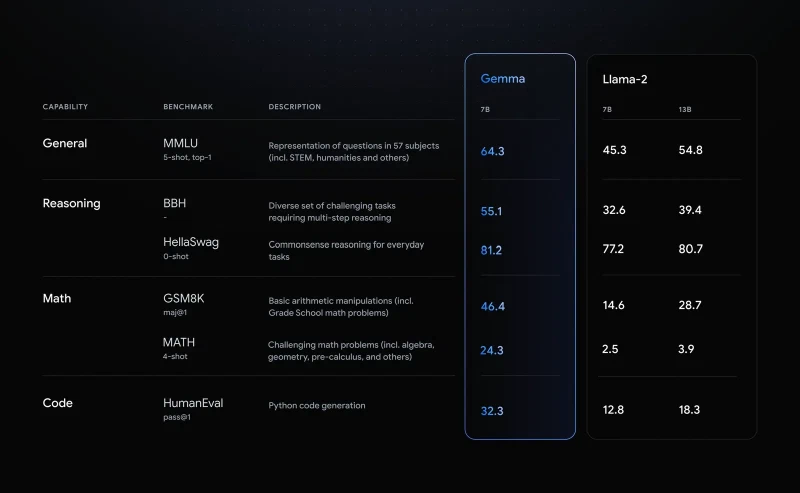
Google reports Gemma 7B at 64.3 on MMLU 5-shot against 54.8 for Llama-2 13B, 46.4 on GSM8K against 28.7, and 32.3 on HumanEval against 18.3, for an average of 56.9 across 18 academic benchmarks. Google puts the 2B at 42.3 on MMLU and 45.0 on average, ahead of Llama-2 7B on the mathematics and coding tasks and behind it overall. Google states that Gemma outperforms similarly sized open models on 11 of the 18 text-based tasks, and notes it could not rerun the Llama-2 evaluations itself because of that model’s licensing, so it cites Meta’s published figures.

Table of Google's benchmark figures showing Gemma 7B at 64.3 on MMLU, 55.1 on BBH, 81.2 on HellaSwag, 46.4 on GSM8K, 24.3 on MATH and 32.3 on HumanEval, each above Llama-2 7B and 13B
Google's own figures for Gemma 7B against Llama-2. Chart: Google.

The weights went up on Kaggle and Hugging Face, with the models also runnable from Colab and Vertex AI, and Google provided toolchains for inference and supervised fine-tuning across JAX, PyTorch and TensorFlow through native Keras 3.0. Hugging Face added Gemma to Transformers 4.38 on announcement day. llama.cpp merged Gemma support the same day, within half an hour of the pull request opening, which is what brought the 2B into quantised local runs on consumer hardware. Google states that the models run across laptop, desktop, IoT, mobile and cloud.

The weights are open but the licence is not a standard open source one. Google publishes them under its own Gemma Terms of Use, which allow use, modification and redistribution provided that downstream recipients get the same terms and the separate Prohibited Use Policy, and which reserve Google’s right to restrict uses it considers non-compliant. Google says the terms permit responsible commercial usage and distribution for all organisations regardless of size. Alongside the models Google shipped a Responsible Generative AI Toolkit with a safety classification method, a tool for debugging model behaviour and written guidance for model builders.

Tuesday 6 February 2024

MobileVLM V2 runs 1.7B, 3B and 7B vision models on 144 image tokens

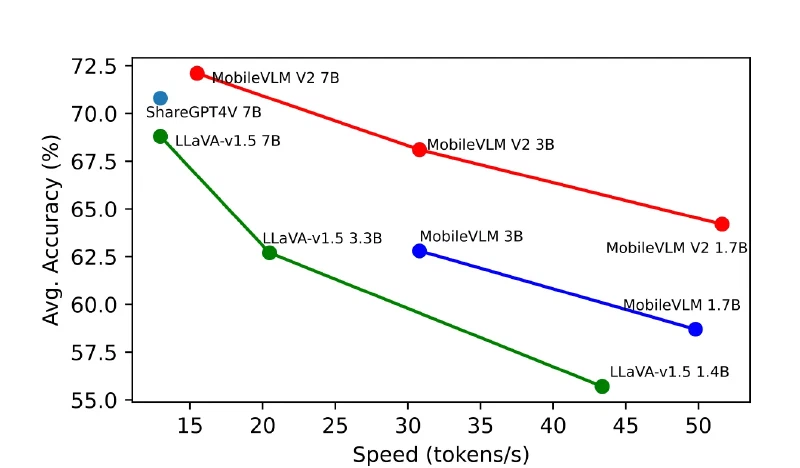
Researchers at Meituan, Zhejiang University and Dalian University of Technology published MobileVLM V2 on February 6, 2024, a family of vision language models at 1.7B, 3B and 7B parameters, each pairing a CLIP ViT-L/14 encoder that reads images at 336 by 336 pixels with a MobileLLaMA or Vicuna language model. Averaged over six benchmarks covering visual question answering, science questions, reading text in images, object hallucination and two multimodal test suites, the authors score the 1.7B model at 64.2 against 62.7 for LLaVA-1.5 3.3B, and the 3B model at 68.1 against 66.7 for MoE-LLaVA-2.7B×4, a mixture of experts where only part of the model is active per token. Their 7B model reaches 72.1, ahead of ShareGPT4V 7B at 70.8 and LLaVA-1.5 7B at 68.8 on the same average.

The authors measured generation over 256 output tokens on an NVIDIA AGX Jetson Orin developer board, not on a phone, with the language model quantised to 4-bit and run through llama.cpp. They report 51.63 tok/s for the 1.7B model, 30.80 tok/s for the 3B and 15.49 tok/s for the 7B, against 43.39, 20.45 and 12.96 tok/s for the three LLaVA-1.5 sizes in the same table. The authors state they wrote their own CUDA implementation of the new projector for that board.

Scatter plot of generation speed against average accuracy on six benchmarks, with the three MobileVLM V2 models on a line above and to the right of the MobileVLM and LLaVA-1.5 lines, reaching 64.2 percent at 51.6 tok/s and 72.1 percent at 15.5 tok/s
Chart: Chu et al., measured on an NVIDIA Jetson Orin with llama.cpp.

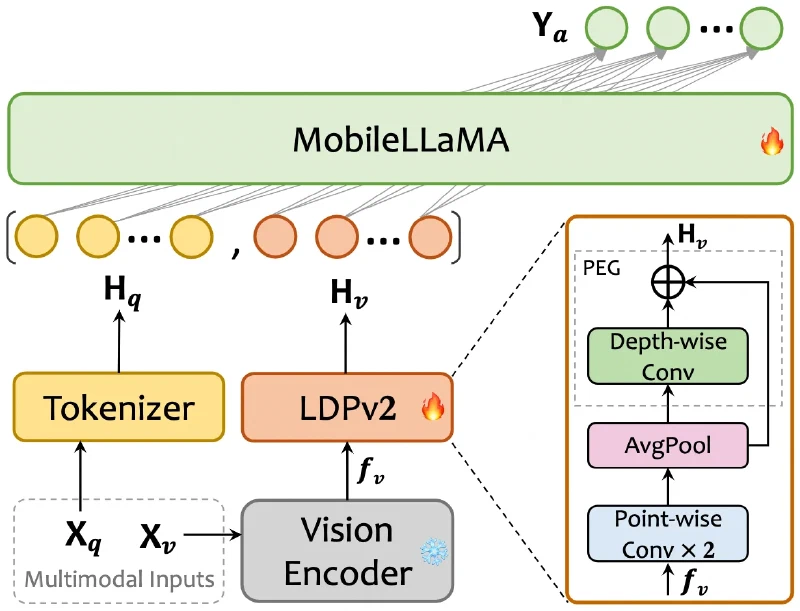
Most of the speed comes from how much of the image reaches the language model. The encoder turns a 336 by 336 picture into 576 patch tokens, and the projector between the two models, which the authors call LDPv2, first runs two 1 by 1 convolutions to match the language model’s width. It then averages every 2 by 2 block of neighbouring patches into a single token, leaving 144, and finally adds a small depthwise convolution back onto the result so each surviving token keeps a sense of where it sat in the picture. That positional part holds 0.02M parameters against 12.64M for the equivalent block in the first MobileVLM, and the whole projector 6.32M against 18.94M, while the six-benchmark average in the authors’ ablation rises from 62.8 to 64.2.

Architecture diagram showing a frozen vision encoder feeding the LDPv2 projector, built from two point-wise convolutions, average pooling and a depth-wise convolution with a skip connection, whose tokens join the tokenised text in MobileLLaMA
Diagram: Chu et al., MobileVLM V2.

Dropping tokens costs accuracy on fine detail. The authors removed the pooling step from the 7B model, which leaves all 576 tokens and puts it at the same latency as ShareGPT4V, and the six-benchmark average rises from 72.1 to 73.5, with most of the gain on TextVQA, a reading task full of small objects. vivo AI Lab took the same 2 by 2 merge further nine months later in BlueLM-V-3B, cutting 729 tokens per image tile to 196 and measuring the result on a phone NPU.

The rest of the gain over the first MobileVLM comes from data and from what stays trainable. The authors pretrain on 1.2 million captioned images from ShareGPT4V, then run a second stage over 2.4 million samples drawn from Visual Dialog, TextVQA, COCO Caption, SBU and other academic sets, 3.6 million in total, and they train the projector together with the language model in both stages while the vision encoder stays frozen, where LLaVA-1.5 and the first MobileVLM keep the language model fixed during pretraining. Both stages together took 8 NVIDIA A100 GPUs for about 14 hours. Meituan put weights for all three sizes on Hugging Face the same day, and the code is published under the Apache 2.0 license.