All updates

News and context on AI running on mobile devices.

Wednesday 17 January 2024

Galaxy S24 becomes the second phone line to run Gemini Nano

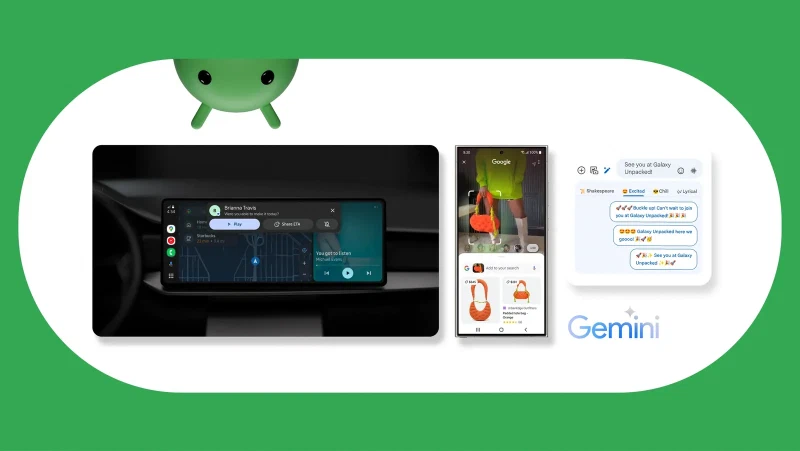
Google announced on January 17, 2024 that the Galaxy S24 series runs Gemini Nano on device, which made it the first phone line outside the Pixel 8 Pro to do so. Google names Magic Compose in Google Messages as the feature that runs locally, and states that the data does not leave the phone.

Product collage showing Android Auto on a car screen, Circle to Search on a Galaxy phone and Magic Compose reply suggestions labelled Shakespeare, Excited, Chill and Lyrical
Image: Google.

The rest of the announced features run in the cloud. Google lists Gemini Pro behind summarisation in Samsung Notes and Voice Recorder as well as keyboard features, with Generative Edit in the Gallery app built on Imagen 2. Gemini Ultra was still in testing at the time.

The launch also introduced Circle to Search, a gesture that searches whatever is circled or highlighted on screen without switching apps. Samsung published its own account of the launch on the Samsung Newsroom.

Arm runs Llama 2 7B at 9.6 tokens per second on three mobile CPU cores

Arm showed a chat assistant running Meta’s Llama 2 7B on existing Android phones using three Cortex-A700 series CPU cores and LPDDR5x memory, at a text generation rate of 9.6 tokens per second. Gian Marco Iodice and Adnan AlSinan published the demo video and the measurement on January 17, 2024, and state that the video runs at actual speed and that everything runs locally on the device. Arm says the rate is faster than average human reading speed.

Integer quantisation is what brought a 7B model into phone memory, according to Arm’s write-up. Arm puts the RAM needed for Llama 2 7B with 16-bit floating point weights at about 14 GB, and says quantising those weights to 4-bit shrinks the model four times, to roughly 4 GB. Arm warns that going down to 3-bit or 2-bit costs accuracy. Pinning each worker thread to a specific core with a thread affinity mask, rather than letting Android’s scheduler place it, improved latency by over 10 percent in Arm’s tests.

Arm then wrote its own 4-bit matrix-by-vector and matrix-by-matrix routines, the two functions that dominate the work in a language model, tuned for Cortex-A700 series cores. The routines are built on two instructions the cores already carry, SDOT for dot products and SMMLA for 8-bit integer matrix multiply and accumulate. Arm reports that they cut the time to the first token by over 50 percent and raised text generation by 20 percent against the native implementation in llama.cpp, and said at the time that the routines would be available soon.

Arm makes the case for the CPU on the shape of the workload rather than on peak throughput, arguing that the typical batch size and the balance of compute and bandwidth in language model inference suit a CPU, and that its programmability lets developers try new compression and quantisation schemes. The post names no NPU or GPU and offers no comparison against one. Arm puts the reach of the approach at around 99 percent of smartphones worldwide and says 70 percent of AI in third-party applications already runs on Arm CPUs.

Arm later extended the same post with a second demo, a teaching assistant chatbot built on Microsoft’s Phi-3 3.8B, which Arm measures at just over 15 tokens per second on the same software optimisations. Arm names the Scalable Matrix Extension for Armv9-A as the next hardware step for these workloads.

Thursday 4 January 2024

TinyLlama pretrains a 1.1B model on 3 trillion tokens

Researchers from the StatNLP group at Singapore University of Technology and Design published TinyLlama on January 4, 2024, a language model of 1.1B parameters pretrained on 3 trillion tokens. The authors set out to see how a small model behaves when it is trained on far more tokens than the compute-optimal scaling law of Hoffmann et al. recommends for its size, and they state that this is, to their knowledge, the first attempt to train a model of around 1B parameters on that much data.

The corpus mixes natural language from SlimPajama with code from the StarCoder training data at a sampling ratio of roughly 7 to 3, which the authors put at about 950 billion tokens once the two are merged and the GitHub part of SlimPajama is dropped to avoid duplication. TinyLlama passes over that set for approximately three epochs, which is how the 3 trillion cumulative figure is reached. Pretraining ran on 16 A100-40G GPUs, and the project repository states that the run started on September 1, 2023 and was budgeted at 90 days.

TinyLlama copies the architecture and tokenizer of Meta’s Llama 2, so it carries rotary position embeddings, RMSNorm pre-normalisation and SwiGLU activations across 22 layers with a hidden size of 2048 and a 2048-token context. It also inherits grouped-query attention, where the 32 query heads share four groups of key and value representations instead of each head holding its own, which the authors use to cut memory bandwidth and speed up inference. They report a training throughput of 24,000 tokens per second per A100-40G GPU, and measure 3,456 GPU hours to cover 300 billion tokens against 4,830 hours for Pythia-1.0B and 7,920 for MPT-1.3B in their own comparison. They attribute that speed to existing open-source components rather than anything new, naming Fully Sharded Data Parallel for spreading training across nodes, FlashAttention-2, fused implementations of layer normalisation, the cross entropy loss and the rotary position embedding, and the fused SwiGLU module from xFormers.

Across seven zero-shot commonsense reasoning benchmarks the authors’ own table puts TinyLlama at an average of 52.99, ahead of OPT-1.3B at 51.44, Pythia-1.4B at 51.33 and Pythia-1.0B at 48.30, with the widest margin on HellaSwag at 59.20 against 53.65 for OPT-1.3B. It does not lead every column, and Pythia-1.4B stays ahead on BoolQ at 63.27 against 57.83. On the InstructEval suite TinyLlama averages 19.87 against 17.72 for Pythia-1.4B and 16.95 for OPT-1.3B, with most of that difference coming from HumanEval, where it scores 9.15 against 4.27.

The authors put the device case briefly, writing in the paper that the compact architecture “can enable end-user applications on mobile devices”, and the repository describes the model as suited to applications with a restricted computation and memory footprint. It puts the 4-bit quantised weights at 637 MB and names offline real-time machine translation and drafting tokens that a larger model then checks as the uses it has in mind. Neither the paper nor the repository reports a measurement on a phone. Weights and all intermediate checkpoints are on Hugging Face under Apache 2.0, with the pre-training code in the repository.
Tuesday 12 December 2023

Microsoft releases Phi-2, a 2.7B model it says matches models 25 times larger

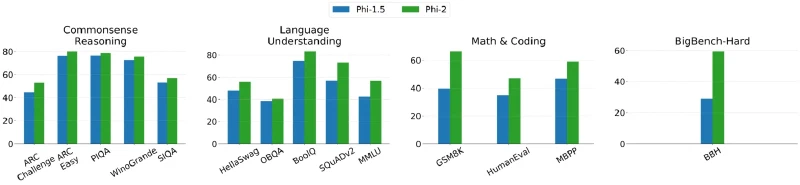
Microsoft released Phi-2 on December 12, 2023, a base language model with 2.7 billion parameters. The company says that on complex benchmarks it matches or outperforms models up to 25 times larger, and that it surpasses Mistral and Llama-2 at 7B and 13B parameters on various aggregated benchmarks. Microsoft’s own table scores Phi-2 at 53.7 on grouped coding benchmarks against 38.3 for Llama-2-70B, and at 61.1 on math against 64.1 for the same model. Against Google’s Gemini Nano 2 at 3.2B, Microsoft reports 59.3 versus 42.4 on BigBench-Hard and 59.1 versus 27.2 on MBPP, using Google’s own reported figures for the comparison.

Microsoft trained the model on 1.4 trillion tokens from multiple passes over a mixture of synthetic and web data for language and code, following what it calls textbook-quality data. The synthetic sets were written to teach common sense reasoning and general knowledge such as science, daily activities and theory of mind, and the web portion was filtered for educational value and content quality. The model card puts the underlying dataset at 250 billion tokens, combining synthetic text generated with GPT-3.5 and web data from Falcon RefinedWeb and SlimPajama that was assessed with GPT-4.

Microsoft did not train Phi-2 from scratch. It started from the 1.3-billion-parameter Phi-1.5 and embedded that model’s knowledge inside the larger one, a step the company says both accelerates training convergence and raises Phi-2’s benchmark scores. Training then took 14 days on 96 A100 GPUs, and the model card lists a context length of 2048 tokens. Phi-2 is a base model that went through neither reinforcement learning from human feedback nor instruction tuning.

Bar chart comparing Phi-1.5 and Phi-2 on commonsense reasoning, language understanding, math and coding, and BigBench-Hard, with Phi-2 ahead in every task and the widest gaps on GSM8K, MBPP and BBH
Chart: Microsoft's own evaluation figures for the two models.

Microsoft published the weights in the Azure AI Studio model catalog and on Hugging Face, where the first model card, dated December 13, 2023, named the Microsoft Research License and limited use to research. Microsoft replaced that file on January 5, 2024, and the model card has since stated “The model is licensed under the MIT license”, which the repository’s commit history dates to that day.

Apple researchers run models twice the size of available DRAM from flash

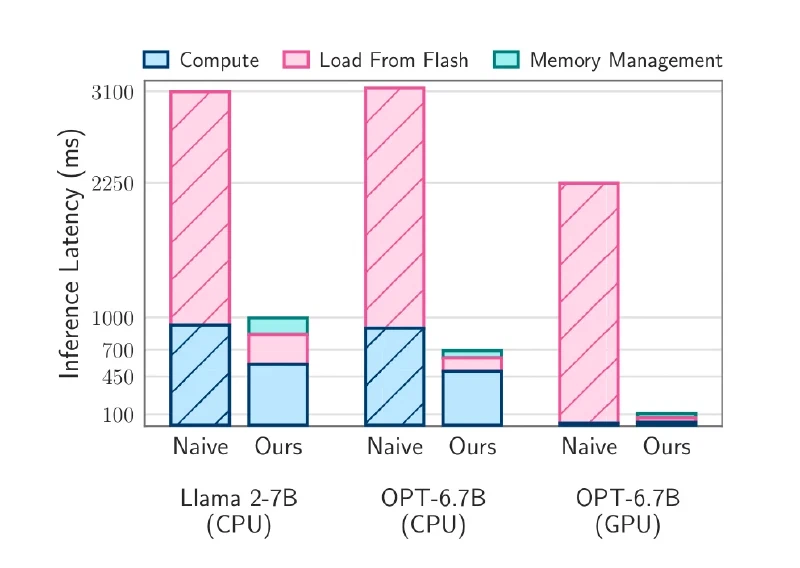
Apple researchers published LLM in a flash on December 12, 2023, a method for running language models that do not fit in a device’s memory. By keeping parameters in flash storage and loading them into DRAM only when needed, the paper reports running models up to twice the size of the available DRAM.

Two techniques carry the result. Windowing reuses neurons that were already loaded for recent tokens, which reduces how much data has to move. Row-column bundling arranges the weights so that reads follow the sequential access patterns flash memory handles best.

Measured against naive loading from flash, the authors report a 4 to 5 times increase in inference speed on CPU and a 20 to 25 times increase on GPU. The paper was last revised in July 2024.

Stacked bar chart comparing naive loading and the paper method for Llama 2 7B and OPT 6.7B, splitting latency into compute, load from flash and memory management
Chart: Alizadeh et al. Latency per token when only half the model fits in memory.

Thursday 7 December 2023

Stability AI releases StableLM Zephyr 3B for edge devices

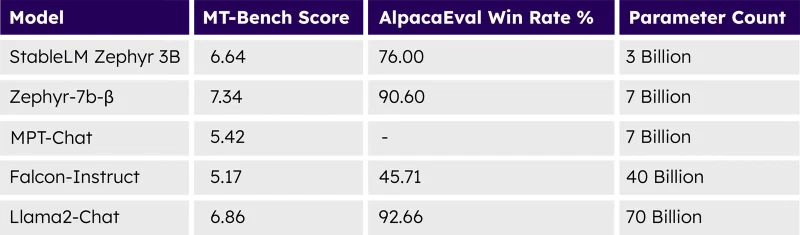
Stability AI released StableLM Zephyr 3B on December 7, 2023, a chat model with 3 billion parameters that the company aims at edge devices and hardware without the compute of dedicated high-end systems. Stability calls the model 60% smaller than 7B models and reports an MT-Bench score of 6.64 and an AlpacaEval win rate of 76.00%.

Both numbers are Stability’s own, measured on two evaluations the company links from the announcement. MT-Bench scores answers to open-ended questions with a larger language model acting as judge, and AlpacaEval measures how often a judge prefers a model’s reply over a reference answer. In the table Stability published with the model card, the 3B model sits above Falcon-Instruct at 40B parameters, which scored 5.17 on MT-Bench, and MPT-Chat at 7B with 5.42, and below Zephyr-7b-beta at 7.34 and Llama2-Chat at 70B with 6.86.

Table comparing MT-Bench scores and AlpacaEval win rates, with StableLM Zephyr 3B at 6.64 and 76.00 percent against Zephyr-7b-beta at 7.34, MPT-Chat at 5.42, Falcon-Instruct 40B at 5.17 and Llama2-Chat 70B at 6.86
Table: Stability AI, the company's own benchmark figures.

The model extends Stability’s earlier StableLM 3B-4e1t and borrows its training pipeline from Hugging Face’s Zephyr 7B, according to Stability. Stability first ran supervised fine-tuning on the UltraChat, MetaMathQA, Evol Wizard and Capybara instruction datasets, then aligned the result with direct preference optimisation, which trains a model on pairs of preferred and rejected answers instead of on correct answers alone. That second stage used UltraFeedback from the OpenBMB research group, a set of 64,000 prompts with model responses.

Stability put the weights on Hugging Face and linked an example notebook for tuning the model’s speed. The release is not open source. Stability states that it ships under a non-commercial community licence permitting non-commercial use, and tells anyone who wants the model in a commercial product to contact the company for separate terms.

Wednesday 6 December 2023

Gemini Nano ships on the Pixel 8 Pro and Android gets AICore

Google brought Gemini Nano to the Pixel 8 Pro in its December 2023 feature drop, where it powers Summarize in Recorder and Smart Reply in Gboard. Google calls the Pixel 8 Pro the first smartphone engineered for Gemini Nano and runs the model on the Tensor G3.

Video: Google. Gemini Nano summarising a recording in the Recorder app. Open the Android Developers post

According to Google, running the model locally helps prevent sensitive data from leaving the phone and lets the features work without a network connection. Summarize in Recorder launched in English. Smart Reply in Gboard launched globally on the United States English keyboard layout, starting with WhatsApp, Line and KakaoTalk.

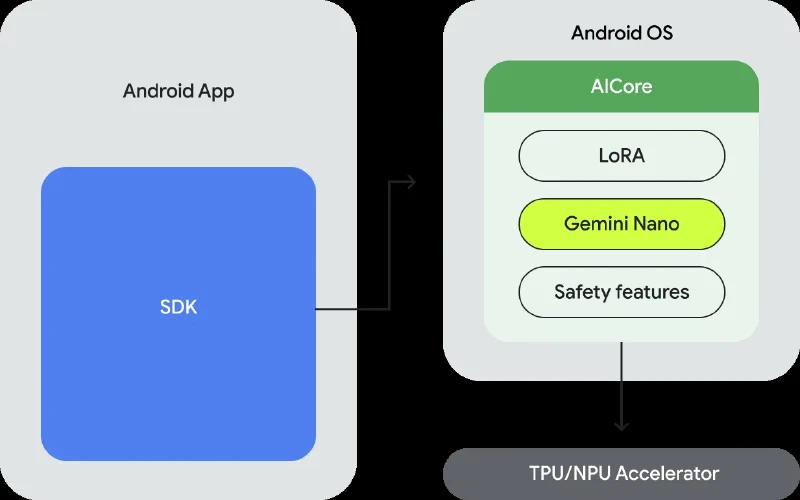
On the same day Google introduced AICore, a system service in Android 14 that handles model management, runtimes and safety features for Gemini Nano. It supports Low Rank Adaptation, so developers can build small adapters trained on their own data, and it targets the Google Tensor TPU as well as NPUs from Qualcomm, Samsung and MediaTek. Google describes the service as isolated from the network by design and opened access through an early access programme.

Diagram showing an Android app calling an SDK that reaches AICore in Android OS, which holds LoRA, Gemini Nano and safety features and drives a TPU or NPU accelerator
Diagram: Google.

Tuesday 5 December 2023

Apple publishes MLX, where CPU and GPU share arrays without copies

Apple machine learning research shipped the first public release of MLX on December 5, 2023, an array framework for machine learning on Apple silicon. The repository carries a v0.0.2 tag dated that day and the same version went up on PyPI minutes later, after an initial commit on November 28. Arrays in MLX live in shared memory, so an operation can run on the CPU or on the GPU without the data being copied from one place to the other.

That behaviour comes from the hardware. Apple silicon uses a unified memory architecture in which the CPU and the GPU have direct access to the same memory pool, and the MLX documentation states that an array therefore has no device of its own. Code names the device when it runs an operation instead of moving an array to a device first, and when two operations on different devices depend on each other, the documentation says the MLX scheduler inserts the dependency between the streams automatically.

Computation is lazy. The documentation states that operations only record a compute graph and that nothing is computed until an eval call asks for a result, which is what lets MLX apply function transformations such as automatic differentiation and automatic vectorisation to the graph. It gives memory as the second reason, since a model whose weights are created as float32 and then replaced with float16 before any evaluation peaks at half the memory eager computation would need.

The MLX Swift bindings followed a week later, with an initial commit on December 12, 2023, and the package manifest lists macOS 14, iOS 17, tvOS 17 and visionOS 1 as supported platforms. The example apps build for iOS as well as macOS and include a chat client for language and vision-language models, a text generation demo that downloads weights from Hugging Face, and Stable Diffusion image generation. The LLMEval example uses the Increased Memory Limit entitlement on iOS, which its README attributes to the size of language model weights, and caps the MLX buffer cache at 20 MB.

MLX LM is the Python package that runs and fine-tunes language models on top of MLX, first published to PyPI on January 12, 2024. It installs the mlx_lm.generate and mlx_lm.chat command line tools, whose default model is a 4-bit quantised Llama 3.2 3B Instruct from the mlx-community organisation on Hugging Face, and it can quantise and upload converted models back to the Hub. MLX is published under the MIT license, and the install documentation lists Apple silicon, macOS 14.0 or newer and Python 3.10 or newer for the macOS package, alongside CUDA and CPU-only builds for Linux added later.

Monday 4 December 2023

LLM.swift wraps llama.cpp for on-device text generation in Swift apps

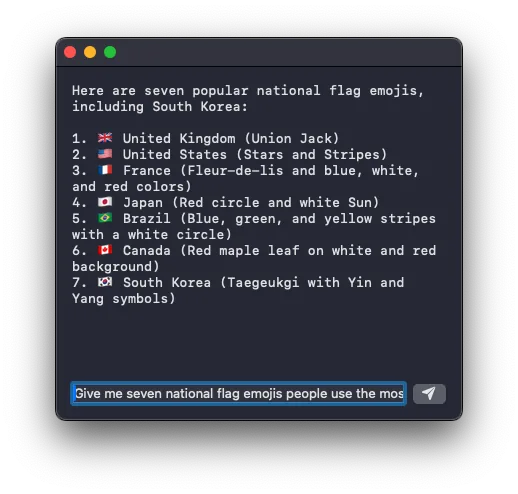
The South Korean developer eastriverlee published the first release of LLM.swift late on December 3, 2023, a Swift package that wraps llama.cpp so an iOS or Mac app can load a GGUF model file and generate text on the device in a few lines. The launch example creates a model object from a file bundled with the app and awaits a reply that streams back token by token into a SwiftUI view. The package declared macOS 12, iOS 14, watchOS 4, tvOS 14 and visionOS 1 as its minimum versions, and required Swift 5.9.

SwiftUI demo window listing seven national flag emojis with their country names, above a text field holding the prompt and a send button
Screenshot: LLM.swift. The test app shipped in the first release README.

Sitting on llama.cpp means the package reads GGUF files and nothing else, and the project states that any model llama.cpp runs should run here too, which is a different route from Hugging Face’s swift-transformers and its Core ML pipeline. Chat formatting was left to the app author at first, a closure that assembled the prompt plus a stop string that ends generation, and the release seven weeks later replaced that with ready-made templates for ChatML, Alpaca and Llama, with Mistral and Gemma added since. A developer adds the package through the Swift Package Manager by pointing at the repository, and the README recommends models of 3B parameters or fewer on mobile devices, reporting a Mistral 7B model running on an iPad Air 5th generation at 5-bit quantisation and on an iPhone 12 mini at 2-bit.

The project has since put out 41 further releases, the most recent in July 2026, and version 3 made the chat template embedded in the GGUF file the default, added function calling and schema-constrained structured output, and switched to a prebuilt llama.cpp framework fetched from an upstream release by URL and checksum. The minimum versions have risen to iOS 16, macOS 13, watchOS 9, tvOS 16 and visionOS 1. Almost all of the roughly 150 commits are eastriverlee’s own, and the package is published under the MIT license.

Tuesday 24 October 2023

Snapdragon 8 Gen 3 targets 10-billion-parameter models on device

Qualcomm launched the Snapdragon 8 Gen 3 at its Snapdragon Summit in Hawaii on October 24, 2023, calling it its first mobile platform designed with generative AI in mind. On the product page the company states support for generative models with up to 10 billion parameters on device and up to 20 tokens per second for large language models.

Qualcomm puts the Hexagon NPU at 98 percent faster than the previous generation and claims 40 percent better performance per watt for sustained AI inference. It lists the Kryo CPU at 30 percent more performance and 20 percent better power efficiency, and the Adreno GPU at 25 percent faster rendering with 25 percent better efficiency.

Among the workloads Qualcomm names for local execution are Stable Diffusion, virtual assistants and chatbots. Devices were announced by ASUS, Honor, iQOO, MEIZU, Nubia, OnePlus, OPPO, realme, Redmi, RedMagic, Sony, vivo, Xiaomi and ZTE.

Render of the Snapdragon 8 Gen 3 chip package on a red circuit board
Image: Qualcomm.

Monday 11 September 2023

Microsoft carries its textbook data recipe from code to reasoning with the 1.3B phi-1.5

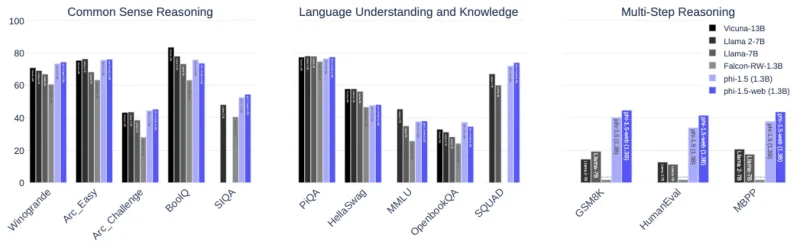
Microsoft Research published phi-1.5 on September 11, 2023, a 1.3-billion-parameter model that applies the synthetic textbook data approach of phi-1 to common sense reasoning and general world knowledge rather than Python code. The authors report common sense benchmark results comparable to models ten times the size trained on more than ten times as much data, and describe natural language performance as comparable to models five times larger.

phi-1.5 scores 0.734 on WinoGrande against 0.691 for Llama2-7B, 0.444 on ARC-Challenge against 0.434, and 0.526 on SIQA against 0.480, all measured in Microsoft’s own evaluation pipeline. The gap widens on multi-step reasoning, with 40.2 on GSM8K grade-school maths against 14.6 for Llama2-7B, 34.1 on HumanEval against 12.8, and 37.7 on MBPP against 20.8, which the authors note puts its coding scores at or above Llama-65B. MMLU runs the other way, at 0.376 for phi-1.5 and 0.453 for Llama2-7B.

Grouped bar charts comparing phi-1.5 and phi-1.5-web at 1.3B parameters with Vicuna-13B, Llama 2-7B, Llama-7B and Falcon-RW-1.3B, showing the phi models level on common sense and language benchmarks and several times ahead on GSM8K, HumanEval and MBPP
Chart: Microsoft, Figure 1 of the technical report.

The training set combines 7B tokens from phi-1 with roughly 20B tokens of newly generated textbook-like text, seeded from 20,000 selected topics spanning science, daily activities and theory of mind. That yields a 30B-token dataset whose only non-synthetic part is 6B tokens of filtered code, and training runs over 150B tokens, 80 percent of them from the new synthetic data. Microsoft puts the cost at 1,500 GPU hours on a single A100-80G, against more than 80,000 hours for Llama-7B.

The same report covers two variants built to test what web data adds. phi-1.5-web-only trains purely on 95B tokens of filtered web text, 88B of it from the Falcon RefinedWeb dataset and 7B of code from The Stack and Stack Overflow, while phi-1.5-web mixes filtered web data, phi-1’s code and the synthetic text in shares of roughly 40, 20 and 40 percent. phi-1.5-web comes out ahead on reasoning at 44.6 on GSM8K, 41.4 on HumanEval and 43.5 on MBPP.

The authors list hallucinations and the potential for toxic and biased generations among the traits phi-1.5 shares with larger models, and write that it “is not immune” despite the absence of web data in its training set. On an 86-prompt probe they wrote themselves, phi-1.5 passed 47 and failed 34, while Llama2-7B and Falcon-7B failed 54 and 50. Microsoft released the raw base model with no instruction fine-tuning and no RLHF, and the weights sit on Hugging Face under the MIT license.

Thursday 24 August 2023

MIT HAN Lab publishes TinyChatEngine for 4-bit LLMs on laptops and Raspberry Pi

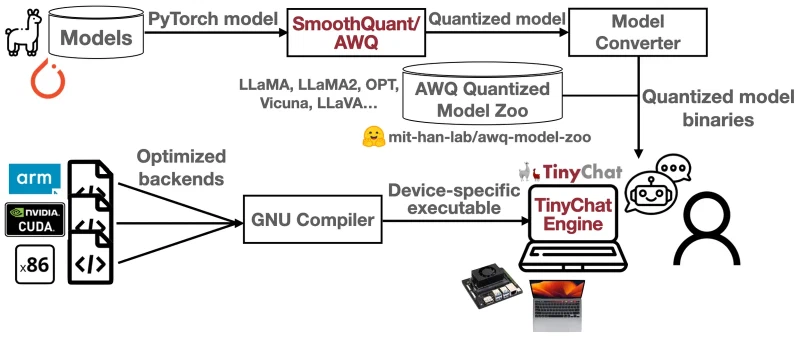
Song Han’s group at MIT pushed the first commit of TinyChatEngine on August 24, 2023, according to the repository’s commit history. The library runs quantised language models in plain C and C++ with no dependency on bulky libraries, and the README names x86 CPUs from Intel and AMD, ARM devices including Apple M1 and M2 Macs and the Raspberry Pi, and Nvidia GPUs through CUDA. The lab’s own slides put LLaMA2-7B at 71 ms per token on an M1 Pro and 210 ms per token on an Intel i7-9750H laptop CPU.

The compression behind it comes from two papers by the same lab. AWQ, for activation-aware weight quantisation, was submitted on June 1, 2023 and works from the finding that protecting only 1 percent of the weights, picked by looking at the activation distribution rather than the weights themselves, keeps most of the accuracy at 4 bits. SmoothQuant, submitted on November 18, 2022, handles 8-bit weights and 8-bit activations by shifting the hard part of the job from activations to weights through a mathematically equivalent transformation, and its authors report up to 1.56x speedup and 2x memory reduction.

Pipeline diagram showing PyTorch models passing through SmoothQuant or AWQ into quantised binaries, then compiled with ARM, CUDA and x86 backends into a device-specific TinyChat executable running on a laptop and a single-board computer
Diagram: MIT HAN Lab.

The backend table lists W4A32, W4A8 and W8A8 on both x86 and ARM CPUs, W4A16 on Nvidia GPUs, and FP32 on CPU. TinyChatEngine reorders the 4-bit weights offline during model conversion rather than at runtime, in a layout tailored to each instruction set, with QM_ARM built for 128-bit SIMD and QM_x86 for 256-bit SIMD. The slides state that expanding the 4-bit weights to int8 and using int8 SIMD multiply-accumulate instead of FP32 gives 1.3x on the Intel i7-9750H and 3x on the M1 Pro.

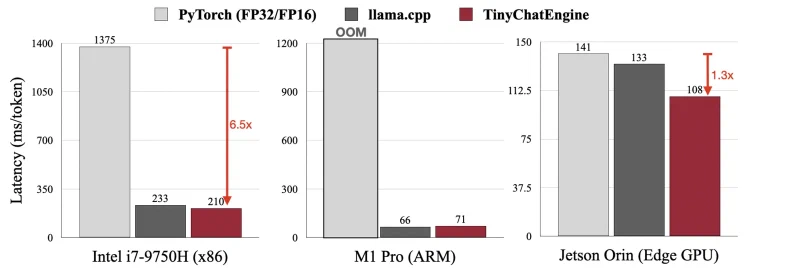
For the device comparison the lab measured LLaMA2-7B against PyTorch and llama.cpp. On the Intel i7-9750H it reports 210 ms per token for TinyChatEngine, 233 for llama.cpp and 1375 for PyTorch, which it labels a 6.5x gap. On an Nvidia Jetson Orin the figures are 108, 133 and 141 ms per token, and on the M1 Pro TinyChatEngine lands at 71 ms per token against 66 for llama.cpp, with PyTorch running out of memory. The lab publishes no Raspberry Pi timing.

Bar chart of LLaMA2-7B latency in milliseconds per token, with TinyChatEngine at 210 against 1375 for PyTorch on an Intel i7-9750H, 71 against 66 for llama.cpp on an M1 Pro, and 108 against 141 for PyTorch on a Jetson Orin
Chart: MIT HAN Lab's own figures, from the project slides.

The model zoo ships LLaMA-7B, LLaMA2-7B-chat and LLaMA2-13B-chat plus OPT at 125M, 1.3B and 6.7B, in FP32, AWQ int4 and SmoothQuant int8 variants, with a download script that takes a per-device quantisation flag. macOS users install boost and llvm through Homebrew, and Xcode for the Metal compiler that enables Apple GPU support. The repository carries an MIT license, added the day after the first commit. For the Raspberry Pi the project recommends a board with 8 GB of RAM and says its testing ran on a Raspberry Pi 4 Model B Rev 1.4 with aarch64.