Gemini Intelligence is coming to the Pixel Watch 5, 9to5Google reports. According to the report, offline Gemini commands on the watch use a separate on-device model when the phone or an internet connection is unavailable. Those commands cover timers and alarms, brightness and modes, music control, opening apps and starting workouts.
On-device smart replies now offer three responses instead of one, which the report attributes to a Gemini Nano upgrade that makes them 50 percent faster.
Other parts of the feature set depend on a connection. Proactive Suggestions, formerly Magic Cue, are generated on a paired Pixel 11 and bridged to the watch, and Personal Intelligence draws on Gmail, Calendar and Keep. The update also brings a new At a Glance space on the watch face for timers, workouts, music, flight details and navigation.
Google has announced the Pixel 11, Pixel 11 Pro and Pixel 11 Pro XL, built around the Tensor G6 chip. Google states that Tensor G6 packs 50 percent more TPU compute and, paired with the latest Gemini Nano model, processes on-device AI tasks up to 3.5 times faster while using up to 3.5 times less energy.
The company also cites an upgraded CPU with 25 percent faster web browsing and 15 percent quicker app launches, and says the chip powers the 30x Super Zoom on the 5x telephoto lens. Google does not publish RAM figures, model sizes or per-task latency in the announcement.
Pre-orders opened on 12 August, with retail availability from 20 August.
▶Meet Google Pixel 11 Pro
Loading connects your browser to www.youtube-nocookie.com, which may process your IP address and use cookies. Privacy details
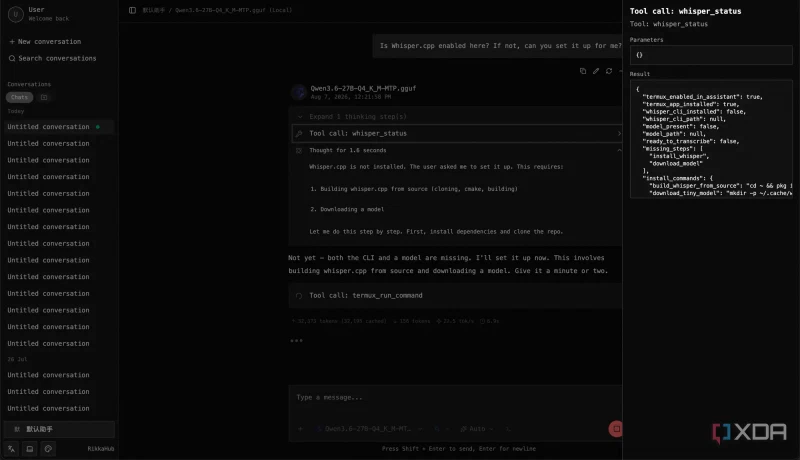
Adam Conway at XDA has testedRikkaHub Agent, a fork by ExTV of the open-source Android LLM client RikkaHub, which adds an agent layer with more than 80 device tools. The phone runs the agent loop and executes the tools; the model itself runs elsewhere on the local network over an OpenAI-compatible endpoint.
The test device was an Oppo Find N5 with a Snapdragon 8 Elite and 16 GB of RAM. Inference ran on a Radeon RX 7900 XTX with Qwen 3.6 27B at Q4_K_M, roughly 16 GB, at 40 to 50 tokens per second. A second configuration used Qwen 3.6 35B on a Lenovo ThinkStation PGX with Nvidia’s GB10 Grace Blackwell.
Screenshot: XDA.
The tool set covers tapping, swiping, scrolling and typing on screen, reading notifications, sending SMS, file management, browser control, SSH, scheduled jobs, a JavaScript runtime and Telegram. All tools are off by default and enabled per assistant, actions with side effects require approval, and a deterministic blocklist rejects destructive commands. The default context is 7,000 input tokens, rising to 32,000 with every tool enabled.
Asked whether whisper.cpp was installed, the agent determined that neither the command-line tool nor a model was present, requested permission, then installed the dependencies, cloned the repository and compiled it inside Termux. The build took seven minutes, and the agent chose the 75 MB small model on speed and accuracy grounds. It then transcribed a Telegram voice message, installing ffmpeg, converting the OGG/Opus file to 16 kHz mono WAV and returning a transcript in about two seconds.
Running the model on the phone itself was slower. With Gemma 4 E2B, a 2.6 GB build accelerated by LiteRT-LM, Conway reports chat worked but agentic tasks were painful, and tool calls were emitted as plain text until an update fixed the behaviour.
Frontier intelligence is never what I’d want from a phone agent, which is why a local LLM works perfectly.
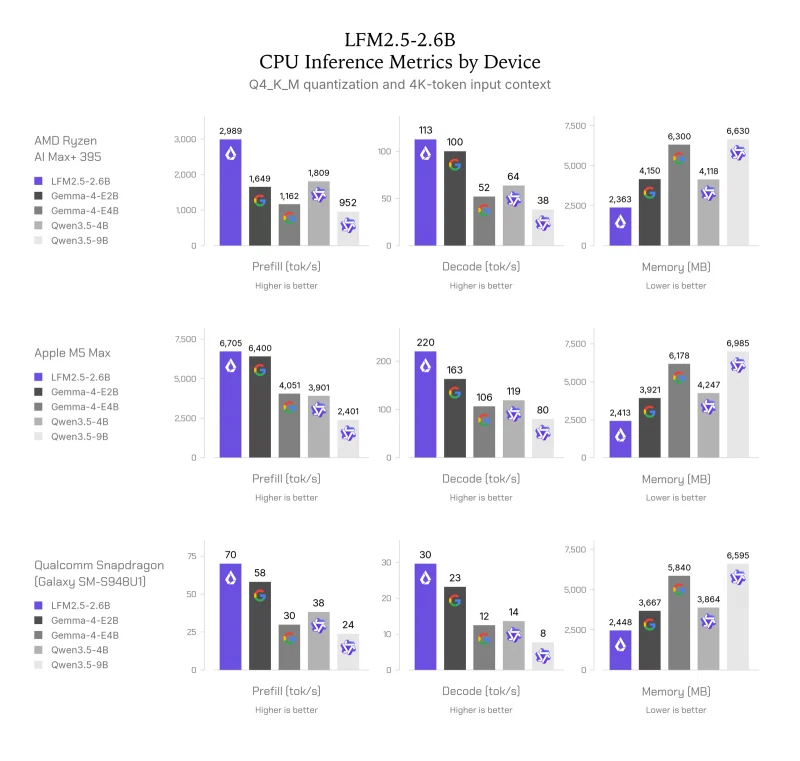
Liquid AI has releasedLFM2.5-2.6B, a 2.6-billion-parameter model built on its LFM2 architecture for edge deployment. The company reports 30 tokens per second on a phone, with CPU inference staying under 2.5 GB of memory. Its published chart identifies the device as a Qualcomm Snapdragon Galaxy (SM-S948U1) and puts memory use at 2,448 MB at Q4_K_M quantisation with a 4K-token input context.
Chart: Liquid AI.
On other CPUs Liquid AI cites 220 tokens per second on an M5 Max and 113 tokens per second on a Ryzen AI Max+ 395. The model was pre-trained on roughly 34 trillion tokens, uses a 128K vocabulary, and its mid-training included a dedicated 128K context-extension phase.
Liquid AI positions the model for agentic use, describing planning, tool calling and multi-step tasks, and states that it is competitive with, and often outperforms, models nearly four times its size on instruction-following and tool use, while larger models keep an advantage in coding. Weights are on Hugging Face in BF16, GGUF for llama.cpp, and ONNX.
Google’s Android developer blog states that Samsung’s new foldable devices come with Gemini Nano 4, which it calls its latest on-device model. The post credits Nano 4 with support for more than 140 languages and better multimodal understanding.
Apps reach the model through ML Kit’s Prompt API, which sends natural language requests on-device to Gemini Nano. It takes text, or a combination of image and text, and returns text or structured output. Google names structured output and thinking mode as the features to use for on-device intelligence.
The ML Kit release notes dated 14 July 2026 record the structured output API, system instructions and thinking mode arriving in the Prompt API, along with multi-image support and an output token limit raised to 4,096 tokens. A note dated 21 July records a fix for Gemini Nano v4 compatibility in the Prompt API on non-Pixel devices. The Prompt API moved from alpha to beta in January 2026 and carries no service level agreement or deprecation policy.
The post also points developers to app functions, which share an app’s capabilities with the Gemini Intelligence system. Its remaining sections cover adaptive layouts, fold-aware design, CameraX and Wear OS widgets.
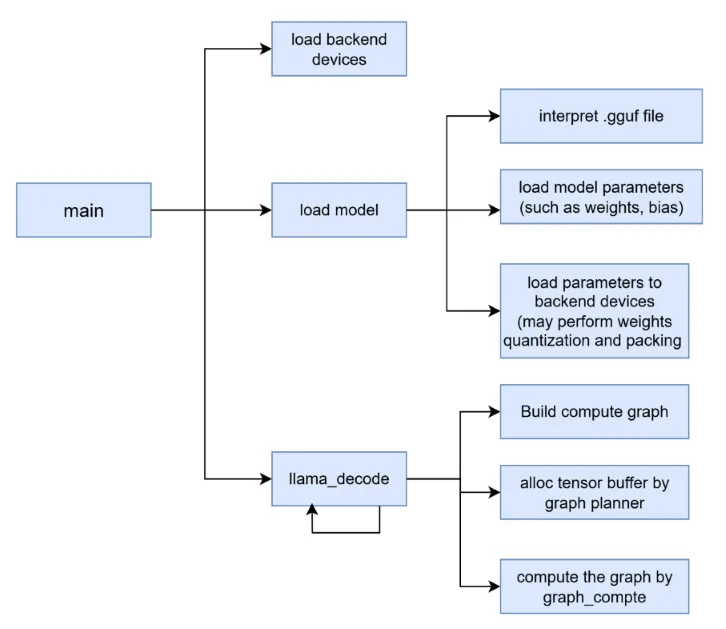
Researchers have published MobiBench, a benchmarking suite built on llama.cpp that measures how small language models behave under limited resources. It covers prefill speed, decode speed, time-to-first-token, memory use and task accuracy. The paper tests Gemma 1B, TinyLlama, Llama 3B and Phi-2, most of them released in 2023 and 2024, plus Q2_K and Q3_K_M quantized variants of Phi-2. A diagram in the paper shows the llama.cpp execution pipeline from runtime initialization and model loading to compute graph construction and iterative decoding.
Figure 1 of the paper, titled high-level execution pipeline of llama.cpp. Credit: MobiBench authors, arXiv
Despite the mobile framing, the authors ran the tests on a gaming laptop with an Intel Core i7 and an RTX 3060 GPU and on a standard laptop with an Intel Core i5 and no dedicated graphics. The paper reports no phone, Android or ARM measurements and no battery or energy data. On the GPU, Llama 3B reaches 225 to 243 tok/s in decode, Phi-2 reaches 102 to 122 tok/s and Gemma 1B reaches 150 to 167 tok/s. The Gemma 1B figure is about 7 to 8 times the 20 to 23 tok/s the authors measured on the CPU.
For TinyLlama, GPU inference cut average wall-clock time per sample from 65.81 s to 1.39 s on MMLU, a 12 to 47 times speedup across the four tasks. On the GPU, Phi-2 used about 2,070 to 2,091 MB of memory, the Q3_K_M variant about 1,982 to 2,000 MB and the Q2_K variant about 1,694 to 1,710 MB. The Q2_K variant decoded at 46 to 56 tok/s and the Q3_K_M variant at 58 to 88 tok/s. On MMLU, Phi-2 scored 0.243, the Q3_K_M variant 0.263 and the Q2_K variant 0.233.
The accuracy tests used 1,000 samples each from RepLiQA, CNN/DailyMail summarization, SciQ and MMLU. Summarization BERTScore F1 stayed between 0.8388 and 0.8458 across all models, and an LLM-based semantic evaluation gave mean scores from 0.4554 for TinyLlama on the GPU to 0.6961 for Gemma 1B on the CPU. The authors list several limitations, namely the restriction to llama.cpp and consumer-grade Intel and RTX 3060 hardware, modest scores on domain-specific reasoning tasks and varying output formats that affect multiple-choice scoring.
Prism ML has released Bonsai 27B, a compressed version of Qwen3.6 27B for Mac, iPhone, iPad and NVIDIA GPUs. The 1-bit variant needs 3.9 GB, which Prism says fits within the memory budget of an iPhone 17 Pro. The company notes that a phone never exposes its full memory to an app and that a 12 GB iPhone offers about 6 GB to a model.
The ternary variant stores each weight as -1, 0 or +1 and takes up 5.9 GB at 1.71 effective bits per weight. The 1-bit variant stores weights as -1 or +1 at 1.125 effective bits. Prism applies the low-bit format to embeddings, attention layers, MLPs and the output head. Both models accept images through a 4-bit vision tower and offer a 262K-token context window.
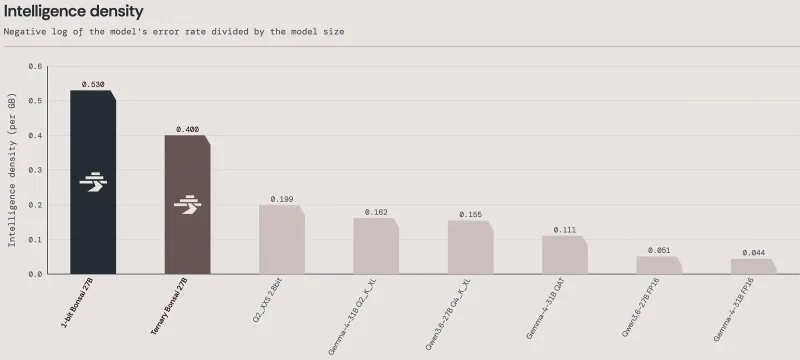
Across a 15-benchmark suite, Prism reports an overall score of 85.0 for Qwen3.6 27B, 80.5 for the ternary model and 76.1 for the 1-bit model, which it describes as retaining 95% and 90% of the original. The largest gaps show up in agentic tool calling, at 80.0 for the original, 74.0 for ternary and 66.0 for 1-bit, and in vision, at 72.6, 65.2 and 59.6. Prism also publishes an “intelligence density” figure, defined as the negative log of the error rate divided by model size in GB, of 0.530 for the 1-bit model and 0.400 for the ternary one.
On an NVIDIA GeForce RTX 5090, Prism measures 163 tok/s for the 1-bit model and 134 tok/s for the ternary model. On an Apple M5 Max the figures are 87 and 58 tok/s. The models also support speculative decoding, where a small draft model proposes tokens that the main model then verifies.
Bonsai 27B is released under the Apache 2.0 license, with builds for MLX on Apple devices and for CUDA on NVIDIA GPUs. Weights are in the Hugging Face collection, and the Bonsai-demo repository covers running them. Prism also lists the Locally AI iOS app and a free, limited-time developer API on Together.ai as ways to try the model.
Researchers at the University of Macau, the University of Georgia and the Hong Kong University of Science and Technology published FBLayout on July 7, 2026, a system that fine-tunes transformer models on a phone’s own GPU, accepted at ACM MobiSys 2026. On a OnePlus Ace 5 Pro with a Snapdragon 8 Elite and its Adreno 830 GPU, the authors measure training on Llama 3.2 1B, Qwen2.5 1.5B and Gemma 2 2B at 3.9 to 4.1 times the speed of MNN, 4.3 to 4.9 times TFLite and 5.4 to 5.7 times TVM. Over the same three baselines they count 3.5 times fewer global memory reads and 4.2 times fewer cache misses.
The authors time inference on the Snapdragon 8 Elite at roughly 6.5 times faster on the GPU than on the CPU, while fine-tuning models of 0.5B to 2B parameters on the GPU comes out level with the CPU or up to 43 percent worse. Their explanation is memory layout, meaning the order in which a tensor’s numbers physically sit in memory. Mobile GPUs hold tensors in a 2D texture grid whose cache rewards reading neighbouring cells, and training reuses forward-pass activations and weights in the backward pass, which sums along a different dimension and so walks the same tensor in strides instead of in rows. Each stride that misses the cache becomes a fetch from DRAM at under 100 GB/s of mobile memory bandwidth, and the GPU stalls waiting for it.
Existing frameworks take one of two ways out, and the paper prices both. MNN reuses the forward layout in the backward pass, which the authors put at up to a 5.3 times slowdown on key operations and at under 21 percent arithmetic-unit utilisation in a matrix-multiply benchmark. TFLite instead inserts explicit transpose and reshape operators, and the paper puts that route at 40.8 to 50.0 percent of total runtime across the three LLMs and at roughly a third of all memory allocations. FBLayout defines one tile-based layout, called R-Tile, that keeps both directions contiguous, then rewrites the remaining reshapes as coordinate arithmetic so no data moves, which they report covers over 86 percent of all layout transformations and over 95 percent of those in the LLMs.
The evaluation covers seven models, adding BERT-Large, ViT-Large, Whisper-Large and Stable Diffusion 1.5 to the three LLMs, with LoRA adapters in the attention and MLP blocks for everything except ViT. Beyond the Snapdragon 8 Elite phone the authors test a OnePlus Ace 10 Pro with a Snapdragon 8 Gen 1 and an Adreno 730 and a OnePlus Ace 5 Ultra with a Dimensity 9400+ and an Arm Mali Immortalis-G925, and report gains on both. Preparing the Llama 3.2 1B training graph takes 6.1 seconds in their measurement, against 723 seconds in MNN, 862 in TFLite and over 4,800 in TVM, and a Monsoon power monitor puts energy use over five training rounds at 3.5 to 6.3 times below the baselines.
FBLayout is built on top of Alibaba’s MNN as about 9.2K lines of C++ and OpenCL, extending it with automatic differentiation so the training graphs exist in the first place. The paper names no code release and points to no repository. It appeared at MobiSys 2026 in Cambridge in June 2026 and is on arXiv under a CC BY-NC-ND 4.0 license.
A team of researchers has published a cross-layer measurement study of mobile LLM inference titled “Is Your NPU Ready for LLMs?”. It covers five frameworks, llama.cpp, MNN, MLC-LLM, MLLM and Qualcomm’s GENIE, on CPU, GPU and NPU backends. The study finds that framework-induced performance gaps grow on NPUs and reach up to 10x.
The tests ran on four Snapdragon phones, the Xiaomi 17, OnePlus 15, Xiaomi 15 and Xiaomi 14, with Llama 3.2 1B and 3B, Qwen 2.5 1.5B and 7B and Phi 3.5 3.8B, mostly with 4-bit weights. At a 256-token context, GENIE on the NPU reaches 1,463.7 tok/s in prefill against 115.1 tok/s for llama.cpp. In decoding the order flips, with the CPU at about 50 to 76 tok/s and the NPU at about 10 to 34 tok/s. The authors attribute this to NPUs preferring large, fixed-shape workloads, which conflicts with the small, dynamic kernels of decoding.
For energy, the team built PowerBench, a lightweight C++ library that maps PMIC power zones to CPU, GPU and NPU for backend-specific attribution. They report that suboptimal configurations waste up to 40% of energy and that a tuned setup cuts NPU energy by up to 54.8%. The recommended settings are a 20 μs RPC polling interval, an NPU sleep latency of 65535 μs, the CPU at its lowest frequency and full-graph offloading with QNN.
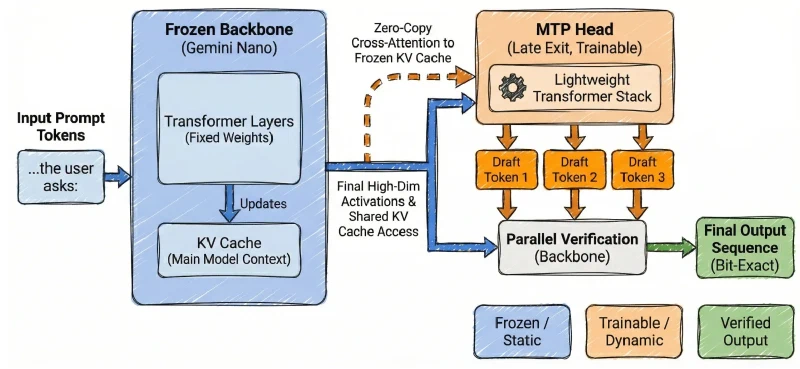
Google Research has retrofitted multi-token prediction (MTP) onto the production Gemini Nano v3 models, which Google says recently rolled out to the Pixel 9 and Pixel 10 series. A small Transformer head attached to the last layers of the model proposes several future tokens per pass, and the unchanged main model verifies them in parallel. According to Google, MTP correctly predicts an average of nearly two additional tokens per inference pass in AI Notification Summaries and Proofread.
Gemini Nano v3 stays frozen and only the MTP head is trained, so Google says the output is bit-for-bit identical to the original model and its capabilities and safety alignment do not change. The head cross-attends to the main model’s existing key-value cache instead of keeping its own, which avoids a second prefill pass. Google reports savings of 130 MB per instance compared with a standalone drafter, a separate small model that proposes tokens in classic speculative decoding, because the head needs no embedding lookup tables, prefill attention variants or application-specific tuning parameters.
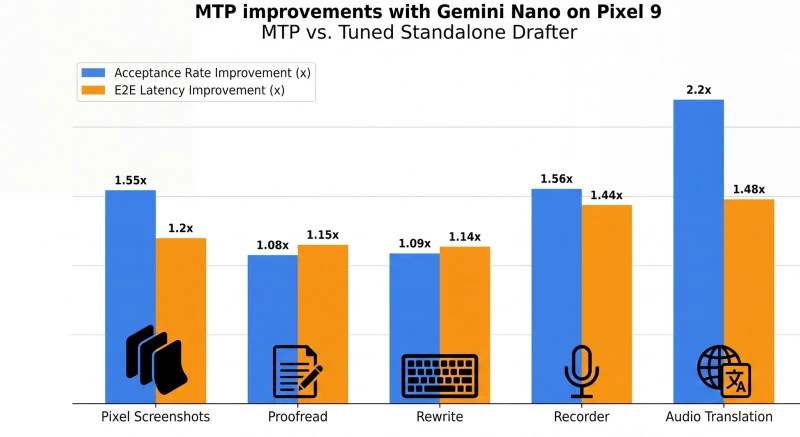
Google measured speedups of 50% or more on Pixel 9 depending on the task, compared with standalone drafters of comparable parameter count. For highly predictable outputs such as smart replies, token acceptance improved by up to 55%. The company says features like notification summaries, Proofread and smart replies now generate text faster and with less energy, and that developers no longer need to fine-tune a separate drafting model for each new task.
Google's own figures show end-to-end latency gains of 1.14x to 1.48x across five Pixel 9 features. Credit: Google Research
Google plans to bring MTP to future Pixel devices. The research team also wants to explore parallel decoding without auxiliary heads to cut draft latency, models that explore several branches in parallel, and a relaxed verification step that no longer requires an exact token match for some use cases.
Qualcomm chief executive Cristiano Amon says the company is working on more than 40 designs of new AI devices, CNBC reports from an interview on its “The Tech Download” podcast. He listed jewellery, earbuds with cameras, pins and watches among the form factors.
Amon described a shift in what devices are organised around:
The phone is around the agent. The new classes of devices … are going to be around the agent as well. And the agent will be the one that will understand human intentions and will do things for you, so there is a shift in what the center of gravity is.
He said phones will not disappear. On software, he told CNBC that apps are “not dead” but “are going to change”, adding: “Those agents are going to be the new app.” His example was an agent that retrieves banking transaction details without the user navigating the app.
On smart glasses, Amon put current shipments in the “order of multiple tens of millions” a year and said that in “a couple of years” the category could reach the “order of hundreds of millions of glasses and could become as big as smartphones”. CNBC cites Counterpoint Research figures of 1.26 billion smartphones shipped in 2025, about 3 percent above the prior year.
Amon linked the entry of AI companies into hardware, such as OpenAI’s purchase of Jony Ive’s startup io, to both agent endpoints and training data, saying the devices will gather data on a scale that is “exponentially larger” than the data used to train current models. He said Qualcomm’s chip roadmap is being reworked in response: “An entire roadmap, because I believe none of the devices we have today are prepared for the future.”
MLCommons announced MLPerf Mobile v6.0 on June 15, 2026, adding generative AI tests that run Llama on an Android device and report token throughput. The new workload comes in 1B, 3B and 8B parameter sizes, using Llama 3.2 1B Instruct, Llama 3.2 3B Instruct and Llama 3.1 8B Instruct.
Each size runs twice, once against TinyMMLU, a small multiple-choice knowledge set, and once against IFEval, which checks whether a model obeys the instructions in a prompt, according to the task configuration in the app repository. MLCommons says the tests run on devices with enough memory through the CPU without tailored acceleration, and that v6.0 adds NPU-accelerated execution of Llama 3.1 8B Instruct on Qualcomm Snapdragon 8 Elite Gen 5. The v6.0 app release of June 9, 2026 also brings support for MediaTek Dimensity 9500 chips and updates support for the Samsung Exynos 2600.
The rest of the suite covers image classification with MobileNetV4 on ImageNet, object detection on COCO 2017, segmentation with MOSAIC on ADE20K, language understanding with MobileBERT on SQuAD 1.1, super resolution with EDSR, and Stable Diffusion 1.5 on COCO captions, as the benchmark page lists them. Almost every test runs in the single stream scenario, where the score is the 90th percentile latency for one query at a time, and image classification also runs an offline pass scored as throughput. Stable Diffusion, the first generative test in the suite, arrived in the v4.1 app release of February 11, 2025. Mostafa El-Khamy, co-chair of the MLPerf Mobile working group, had set out the plan in May 2024.
Looking ahead, the MLPerf Mobile group is working to add generative AI tasks to a future version of the benchmark suite.
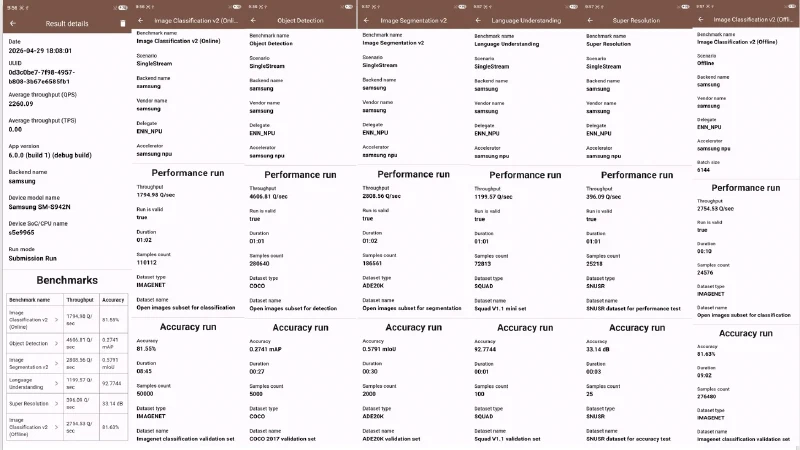
Results come from chip and device makers that run the app and submit their logs. The published v6.0 results hold one submission in the closed division, from Samsung on an Exynos 2600 phone, and it covers the vision tests, language understanding, super resolution and Stable Diffusion rather than the new Llama ones. Samsung’s logs give a 90th percentile single stream latency of 0.56 ms for image classification, 0.83 ms for MobileBERT and 1.87 s for one Stable Diffusion image. The v5.0 round carried submissions from Samsung and Qualcomm Innovation Center.
Screenshots: Samsung's submission to MLPerf Mobile v6.0, published by MLCommons.
Submissions are held back until review closes under the MLCommons submission rules, which keep every result confidential inside a review committee after the deadline and let submitters file objections that the committee then decides. MLCommons publishes the accepted runs in the results table on the MLPerf Inference Mobile page, with the logs and calibration notes in a per-round repository on GitHub. The app is available through Google Play, the Apple App Store and the MLPerf Mobile repository under the Apache 2.0 license.