Prism ML releases 1-bit Bonsai 8B, an 8.2B-parameter model that needs 1.15 GB
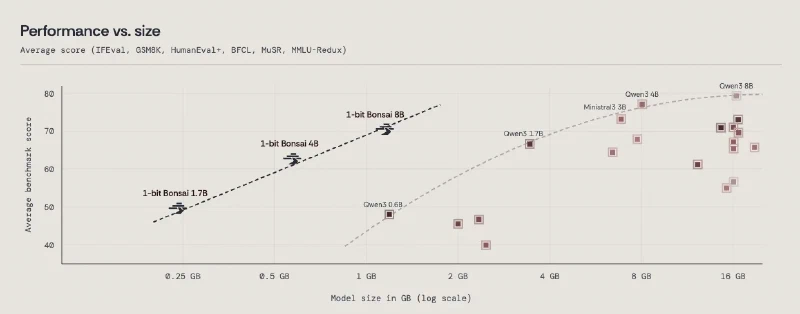
Prism ML has released 1-bit Bonsai 8B, a language model with 8.2 billion parameters that stores every weight in a single bit. Embeddings, attention layers, MLP layers and the LM head are all 1-bit, which brings the model down to 1.15 GB. The company also released 4B and 1.7B versions of the family.
On Apple hardware Prism reports about 40 tok/s on an iPhone 17 Pro and about 44 tok/s on an iPhone 17 Pro Max, against 131 tok/s on an M4 Pro Mac. An NVIDIA RTX 4090 reaches 368 tok/s, compared with 59 tok/s for a 16-bit 8B model in Prism’s chart. The 16-bit model reaches 16 tok/s on the M4 Pro and does not fit on the iPhone 17 Pro Max.
Prism measured 0.074 mWh per token on the M4 Pro and 0.068 mWh per token on the iPhone 17 Pro Max, which it puts at 4 to 5 times less than 16-bit counterparts. On the RTX 4090 the figures are 0.276 mWh for 1-bit Bonsai 8B and 1.134 mWh for the 16-bit model.
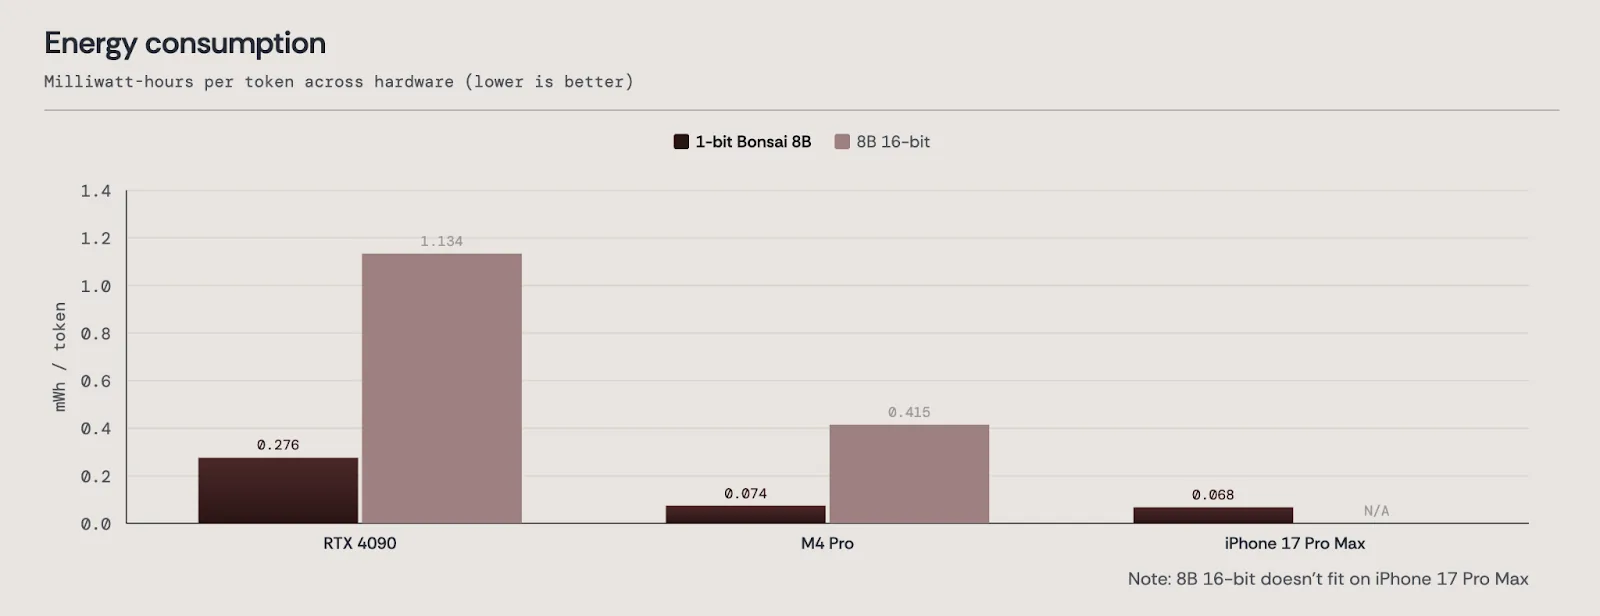
Energy per token for 1-bit Bonsai 8B and a 16-bit 8B model, as measured by Prism ML.Prism ML
The company gives the 8B model an average benchmark score of 70.5, made up of 65.7 on MMLU Redux, 50.0 on MuSR, 88.0 on GSM8K, 73.8 on HumanEval+, 79.8 on IFEval and 65.7 on BFCLv3. It compares the model with 8B-class models such as Qwen3 8B, Llama 3.1 8B, Ministral3 8B and LFM2 8B. On its own “intelligence density” metric, a score per GB of model size, Prism lists 1.06 for Bonsai 8B and 0.10 for Qwen3 8B.
The models are released under the Apache 2.0 license. They run on Apple devices via MLX and on NVIDIA GPUs via llama.cpp CUDA, and the iOS app Locally AI can run them on iPhone. Weights are in the Hugging Face collection, and the demo repository holds a whitepaper and quick start instructions, along with a Colab notebook.