Liquid AI releases d1-3B and d1-omni-600M as open-weight decision models
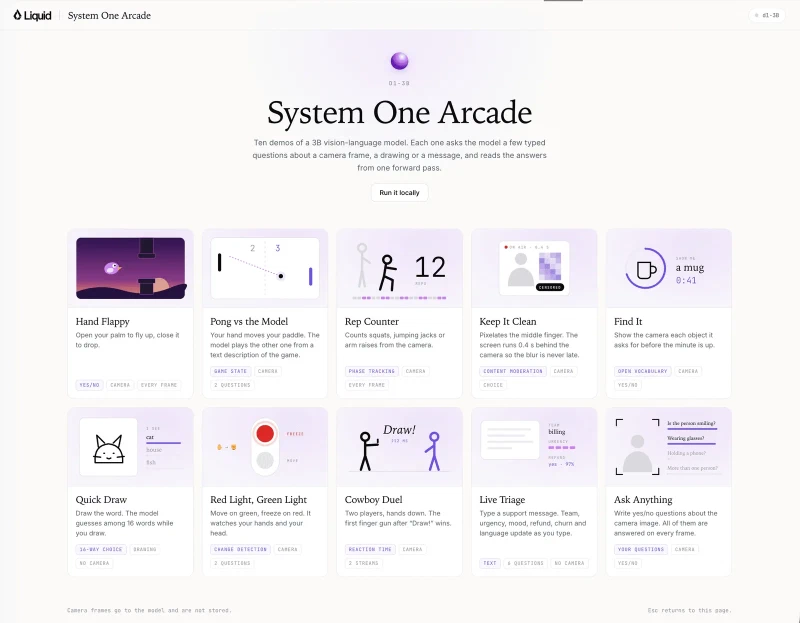
Liquid AI has released two open-weight decision models, d1-3B and d1-omni-600M, which answer a question without generating any tokens. Both produce their answer in a single forward pass, so a yes/no, multiple-choice or scale question costs one pass through the network instead of a decoded response. The company says d1-3B scores 48.57 on the public split of the Decision Index v0.2.1, ahead of every model under 10B parameters and on par with Decider 35B-A3B, a decision model 12 times its size. Liquid AI had previously offered d1 through its API only.
A single question takes 16 ms on an NVIDIA Jetson AGX Thor, 26 ms on a Jetson AGX Orin 64 GB, 30 ms on an Apple M5 Pro and 50 ms on a Jetson Orin Nano, measured end to end from input to output. Three questions cost about 1.3 times as much as one, going from 16 ms to 20 ms on the AGX Thor, and a 384px image adds 35 ms there. On desktop hardware the same model answers in 8 ms on an RTX 4090 and 9 ms on an AMD MI325X. Liquid AI ran the tests one request at a time and reports latency for d1-3B only.
Seven public text benchmarks cover reading comprehension, toxicity detection, intent classification, medical question answering and cross-lingual understanding. d1-3B reaches a mean of 82.9 across them, ahead of Decider 4B at 81.1, while d1-omni-600M lands at 78.4 and beats Decider 2B at a quarter of the parameters. Liquid AI reports no vision scores because the vision split of the Decision Index v0.3 is private, and it calls dedicated audio decision benchmarks an open problem.
Text benchmarks, d1-3B against Decider 4B
| Benchmark | d1-3B | Decider 4B |
|---|---|---|
| SQuAD 2.0 | 85.3 | 76.0 |
| Civil Comments | 93.0 | 92.8 |
| MASSIVE intent | 87.3 | 88.3 |
| PubMedQA | 66.0 | 63.3 |
| BoolQ | 86.7 | 89.0 |
| XNLI | 85.0 | 88.6 |
| PAWS-X | 76.9 | 69.8 |
| Mean | 82.9 | 81.1 |
All figures according to Liquid AI. d1-omni-600M reaches a mean of 78.4 on the same seven benchmarks.
Both models start from existing LFM2.5 checkpoints. d1-3B is an average of LFM2.5-2.6B and the text backbone of LFM2.5-VL-3B, fine-tuned with different random seeds and data mixtures and then merged again, and it takes text and images as input. d1-omni-600M builds on the bidirectional LFM2.5-Encoder-350M and adds a FastConformer audio encoder and the vision encoder of LFM2.5-VL-450M in stages, so it accepts text with either an image or audio. Liquid AI calls it a first experimental checkpoint that is under active development.
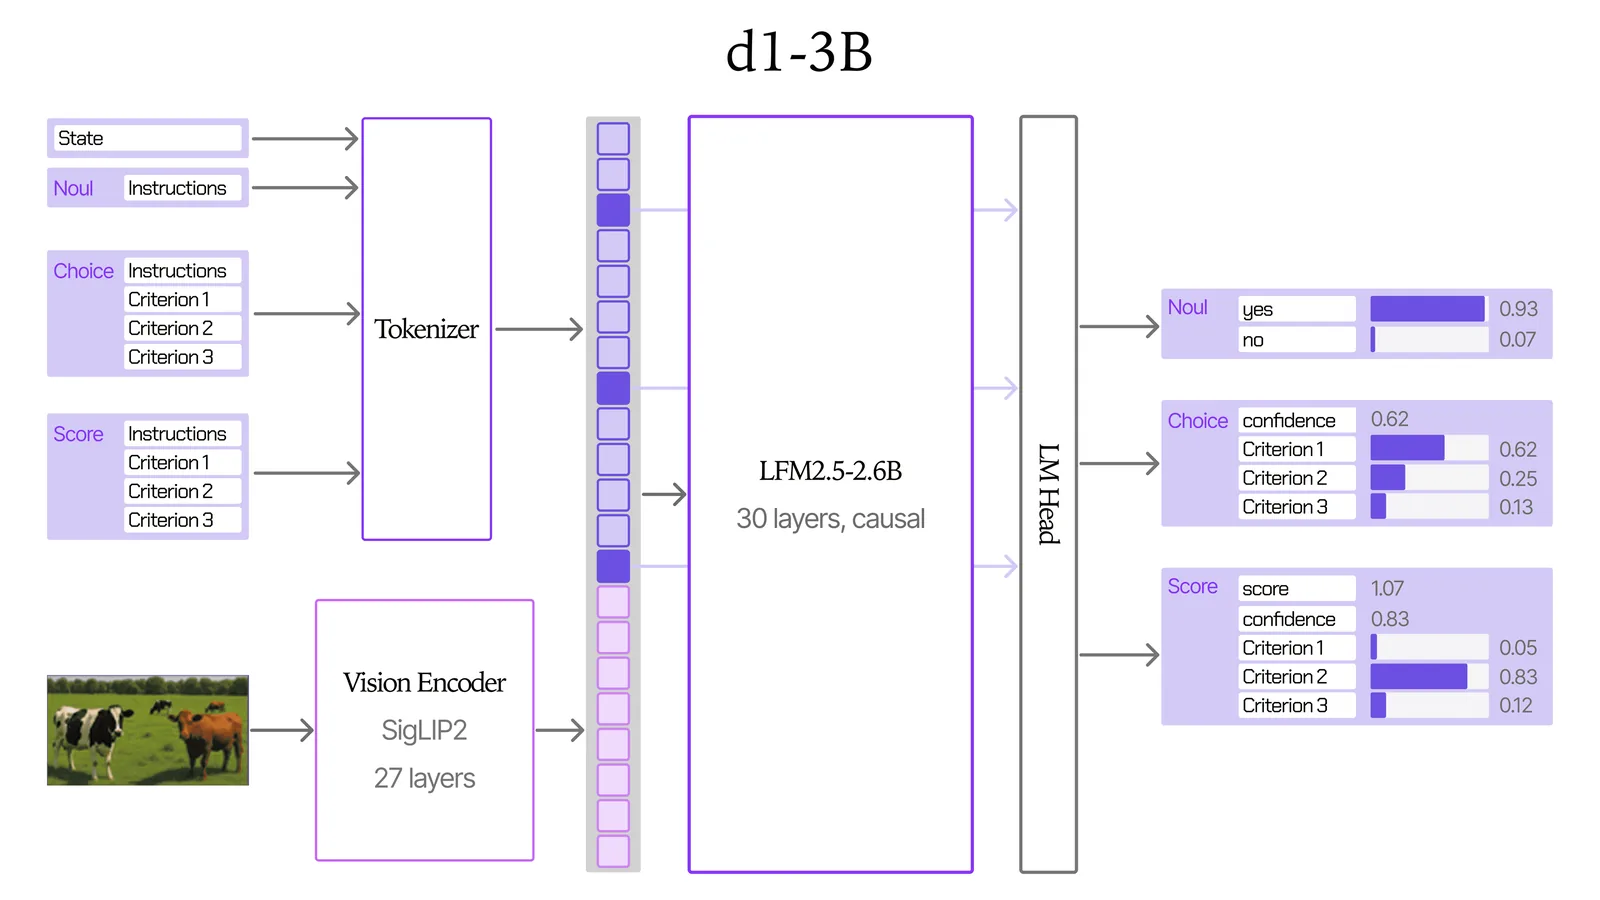
The question types are encoded alongside the image, and the head returns a probability for every answer option.Liquid AI
Day-one support for llama.cpp covers Apple, Qualcomm, AMD and NVIDIA hardware, with NVFP4 on the NVIDIA stack from DGX in the data center down to Jetson at the edge, and Liquid AI documents the local setup. The weights can be downloaded, fine-tuned and deployed without restrictions according to the company, which names no license in the announcement. Ten browser demos run d1-3B in a loop over live camera input in a Hugging Face space, among them gesture-controlled games and live content moderation, and NVIDIA lists both models in its Jetson AI Lab. A further demo has the model steering a simulated robot arm in NVIDIA Isaac Sim, served from a Jetson.
This video could not be loaded. Use the link below to open it directly.