Liquid AI releases LFM2.5-2.6B for on-device agents
Liquid AI has released LFM2.5-2.6B, a 2.6-billion-parameter model built on its LFM2 architecture for edge deployment. The company reports 30 tokens per second on a phone, with CPU inference staying under 2.5 GB of memory. Its published chart identifies the device as a Qualcomm Snapdragon Galaxy (SM-S948U1) and puts memory use at 2,448 MB at Q4_K_M quantisation with a 4K-token input context.
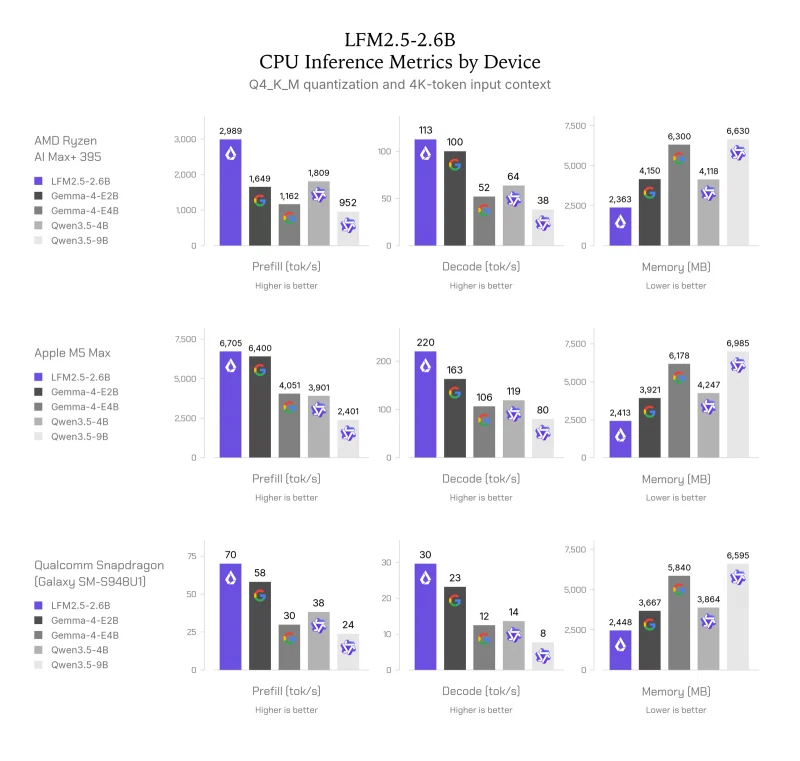
On other CPUs Liquid AI cites 220 tokens per second on an M5 Max and 113 tokens per second on a Ryzen AI Max+ 395. The model was pre-trained on roughly 34 trillion tokens, uses a 128K vocabulary, and its mid-training included a dedicated 128K context-extension phase.
Liquid AI positions the model for agentic use, describing planning, tool calling and multi-step tasks, and states that it is competitive with, and often outperforms, models nearly four times its size on instruction-following and tool use, while larger models keep an advantage in coding. Weights are on Hugging Face in BF16, GGUF for llama.cpp, and ONNX.