Meta ships Llama Stack with Swift and Kotlin clients for on-device inference
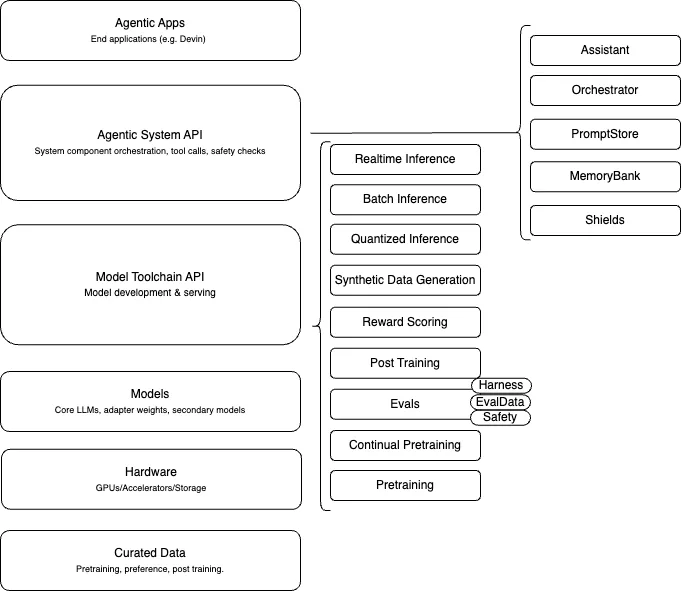
Meta announced Llama Stack at Connect on September 25, 2024, a set of REST APIs plus client SDKs for Python, Node, Swift and Kotlin that cover the same Llama features wherever the model runs. The repository defines APIs for Inference, Safety, Memory, Agentic System, Evaluation, Post Training, Synthetic Data Generation and Reward Scoring, and lists PyTorch ExecuTorch as the on-device provider, covering inference and agents on iOS. The models announced at the same event are covered separately.
Llama Stack separates providers from distributions. A provider is the implementation behind an API, which can be local code or a pointer to a remote service, and a distribution assembles providers behind one endpoint. Meta’s README states that providers can be mixed, that a hobbyist can serve a small model locally and use a cloud provider for a large one, and that the higher level APIs the app works with do not change, including across the server and mobile-device boundary.
On iOS the local provider is a Swift class called LocalInference, which the documentation describes as powered by ExecuTorch. It implements the same Inference interface the Swift client uses for remote servers, so an app that already streams chat completions or agent turns keeps its calling code and swaps the service it was given. Developers export the model to an ExecuTorch .pte file, bundle it with tokenizer.model in the app, and link the XNNPACK, Core ML and MPS backends plus the quantized and optimised kernels, with Meta’s own example loading a SpinQuant build of Llama 3.2 1B.
The Swift package is added through Xcode’s package manager and generates its types from the Llama Stack OpenAPI spec, and Meta listed its first release on October 10, 2024. The same iOS documentation stated that on-device inference for Android was coming soon, and pointed developers to ExecuTorch’s own Android demo app in the meantime. Llama Stack, the Swift client and the Kotlin client are published under the MIT license.
Update, December 6, 2024. Meta released version 0.0.54 of the Kotlin client, which adds on-device inference on Android. The README names ExecuTorch as the local inference distributor, has developers run a script that fetches a prebuilt executorch.aar with the XNNPACK delegate into the app’s libs directory, and shows the only difference between the two modes as the client builder, LlamaStackClientLocalClient with a model and tokenizer path against LlamaStackClientOkHttpClient with a base URL. The chatCompletion call that follows is identical.