Google ships an experimental MediaPipe LLM Inference API for web, Android and iOS
Google released the MediaPipe LLM Inference API on March 7, 2024, an experimental way to run language models fully on device from web, Android and iOS apps. Four open models are supported at launch, Gemma 2B, Phi 2, Falcon 1B and Stable LM 3B.
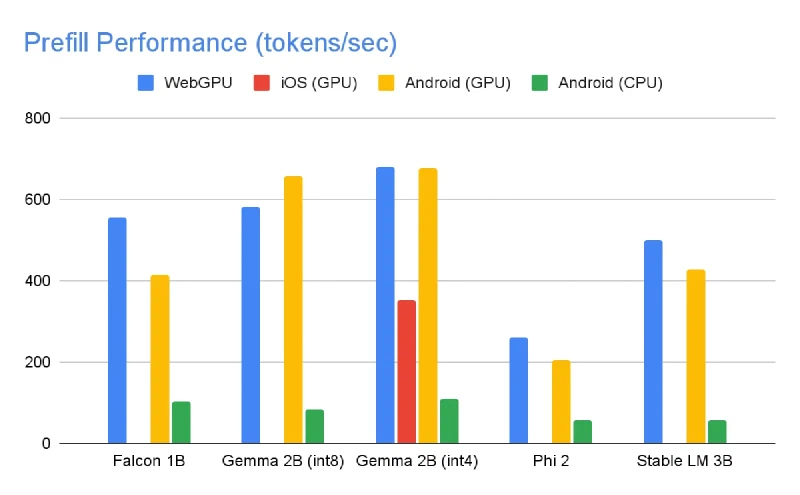
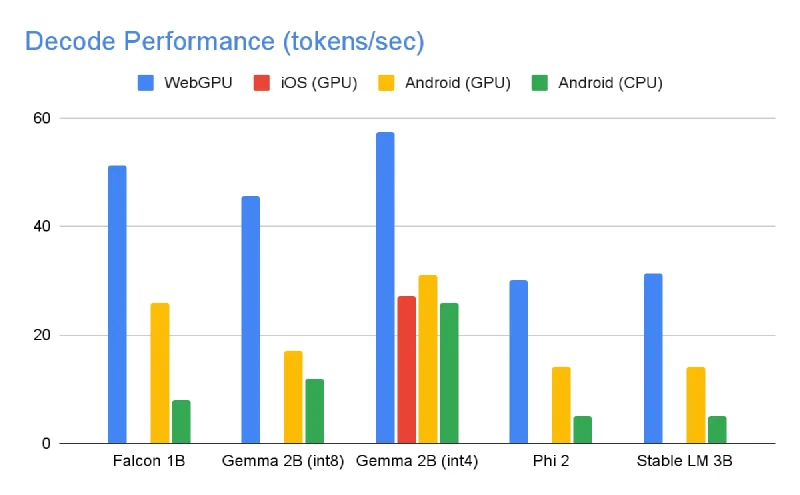
The API quantises weights to int8, with Gemma 2B using mixed 4-bit and 8-bit weights. Google measured throughput on unnamed high-end devices with a 1024-token input prompt and a maximum of 1280 tokens. In its charts, Gemma 2B at int4 prefills at roughly 680 tokens per second on WebGPU and on an Android GPU, and decodes at about 57 tokens per second on WebGPU against 31 on an Android GPU and 27 on iOS.
Google marks the Android version as intended for experimental and research use only, and points production apps to the Gemini API or to Gemini Nano through Android AICore instead. On iOS, Gemma 2B at int4 was the only model the team could run, which Google attributes to the memory available on the platform.