Nvidia fits a 74B Nemotron into 24 GB of memory with 2-bit quantisation
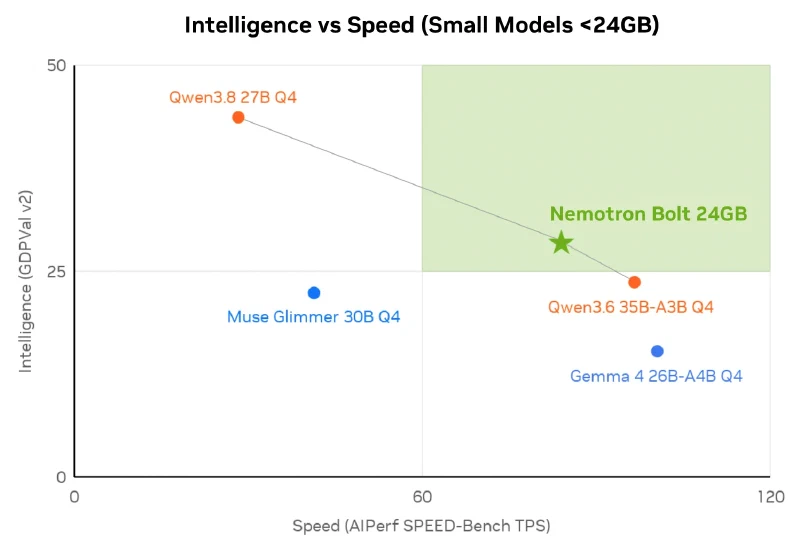
Nvidia has released Nemotron 3.5 Bolt 74B-A9B 24GB, a mixture-of-experts model with 74 billion parameters of which 9 billion are active per token, compressed and quantised to fit into 24 GB of memory. In MoE models only part of the network runs for each token, which keeps compute low while the weights stay large. The company measured 83.99 tokens per second on the AIPerf SPEED-Bench coding benchmark, running llama.cpp on an RTX Spark laptop.
The model is a shrunk version of Nemotron 3.5 Super VL, which holds 120 billion parameters with 12 billion active. Nvidia cut it down with a method it calls Star Elastic, which lowered the number of experts picked per token from 22 to 9, then applied quantisation-aware distillation to the result. Only the weights are quantised and the format varies by layer, with the routed and shared expert layers at IQ2_XXS, or 2.0625 bits per value, the Mamba linear layers at NVFP4, and attention, embeddings and the output head at Q8_0. The backbone interleaves Mamba-2, attention and MoE layers and carries a C-RADIO v4-H vision encoder, so the model reads text, images and video up to two minutes long.
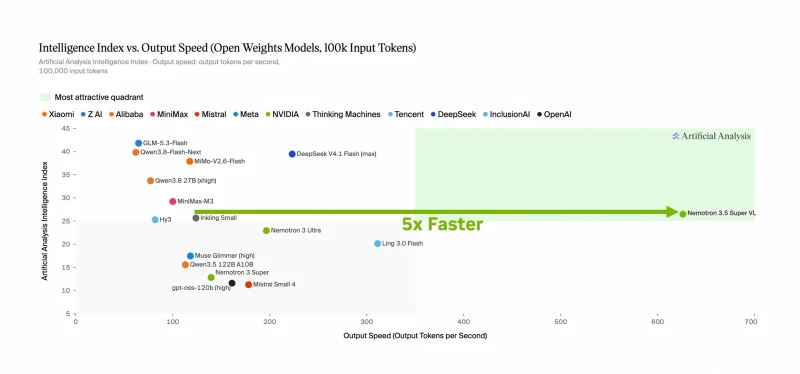
That throughput figure comes from llama.cpp on Windows 11 on a Surface Laptop Ultra with 128 GB, helped by a 1.13B-parameter draft model called LiLiCorr that guesses tokens ahead of the main model. In the same test Nvidia recorded 100.56 tok/s for Gemma 4 26B-A4B and 96.63 tok/s for Qwen3.6 35B-A3B, both at 4-bit, so Bolt decodes slower than the two smaller MoE models it is held against, and roughly three times faster than the dense Qwen3.8 27B at 28.26 tok/s. On the AA AgentPerf Local replay test it also finished last of the three MoE models, at 600.80 seconds against 453.97 for Qwen3.6 and 480.68 for Gemma 4.
On accuracy the ranking flips. Nvidia puts the 2-bit Bolt ahead of the same group on most of its benchmark table, with the widest gap on BrowseComp at 66.75 against 48.74 for Qwen3.6 35B-A3B, while Gemma 4 26B-A4B keeps a wider lead on AA-Omniscience accuracy and Qwen a narrow one on PinchBench. The comparison runs the competitors at BF16 and Bolt at IQ2, and Nvidia selected them because they fit in 24 GB once quantised to 4-bit.
Nemotron 3.5 Bolt 74B-A9B 24GB against Qwen3.6-35B-A3B
| Benchmark | Nemotron 3.5 Bolt | Qwen3.6-35B-A3B |
|---|---|---|
| BrowseComp | 66.75 | 48.74 |
| Terminal-Bench 2.1 | 50.98 | 44.38 |
| WebArena (vision) | 50.86 | 36.60 |
| GPQA Diamond | 86.43 | 83.40 |
| GDPVal-AA-V2 | 28.47 | 25.75 |
| PinchBench | 87.82 | 88.07 |
| AA-Omniscience accuracy | 16.90 | 19.47 |
All figures according to Nvidia. Bolt runs at IQ2, Qwen3.6-35B-A3B at BF16.
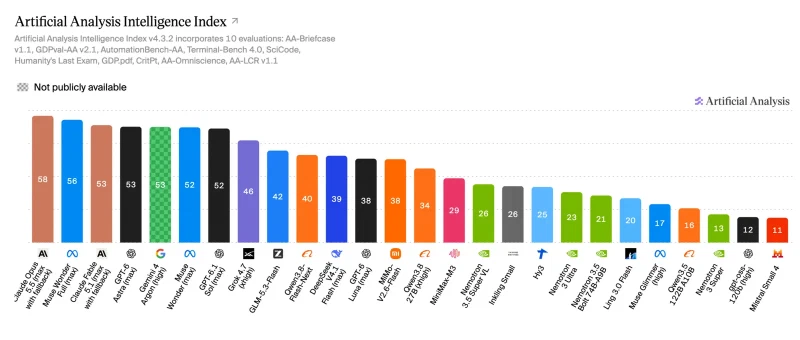
The GGUF weights sit on Hugging Face under the OpenMDW 1.1 licence, which permits commercial use, with context up to 256K tokens and two deployment recipes, a 32 GB one for an RTX Spark with 128 GB or a discrete RTX card from 48 GB up, and a 28 GB one for 64 GB and 32 GB systems. Nvidia names llama.cpp as the runtime engine and points to Ollama, LM Studio, Unsloth and vLLM, and the card lists ten supported languages. A much smaller sibling has since arrived, Nemotron 3.5 Bolt E4B 4GB, post-trained from Google’s Gemma 4 E4B and shipped as a Q4_K_M GGUF with a 64K context, for which Nvidia measured 15.5 tok/s on a Jetson Orin Nano with 8 GB and 133.4 tok/s on a GeForce RTX 5070.