Ornith releases Ornith-1.5, a 9B model with a mobile build for iPhone and Android
Ornith has released Ornith-1.5, a model family with a 9B dense model, a 35B mixture-of-experts model that activates about 3B parameters per token and a 397B mixture-of-experts model. The 9B model also comes as Ornith-1.5-9B-Mobile, a quantized variant (about 1,5 GB on disk) designed for iPhone and Android.
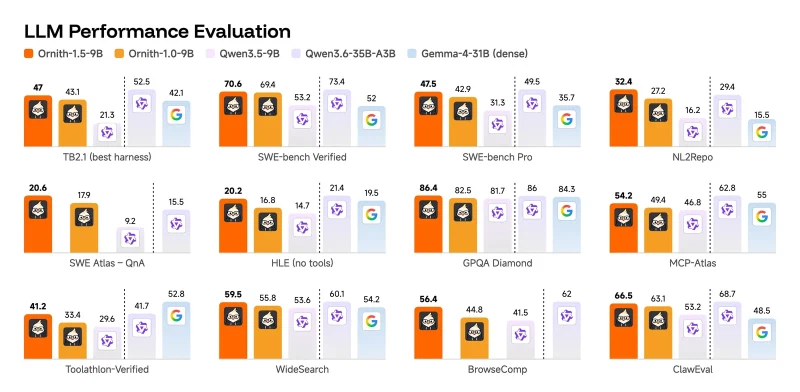
The 9B model scores 47.0 on Terminal-Bench 2.1 with the Claude Code harness and 70.6 on SWE-bench Verified in Ornith’s tests. The company says the model matches or exceeds much larger models such as Gemma 4-31B and Qwen 3.6-35B. In the company’s chart, Qwen3.6-35B-A3B leads on SWE-bench Verified with 73.4 and on Terminal-Bench 2.1 with 52.5, while the 9B model scores 86.4 on GPQA Diamond and 54.2 on MCP-Atlas. The previous Ornith-1.0-9B reaches 43.1 on Terminal-Bench 2.1 in the same chart.
According to Ornith, its training loop lets the model propose new tasks, generate task-specific scaffolds and produce solution rollouts, with the reward from the rollouts propagated across all three stages. The company reports that the 35B model scores 67.8 on Terminal-Bench 2.1 with the Terminus-2 harness, against 52.5 for Qwen 3.6-35B. The models are on Hugging Face, with GGUF builds of all three sizes and MLX builds of the 9B and 35B models.