Prism ML releases Ternary Bonsai, 1.58-bit models with an 8B version at 1.75 GB
Prism ML has released Ternary Bonsai, a model family in 8B, 4B and 1.7B sizes that stores weights as -1, 0 or +1 instead of a single bit. Ternary Bonsai 8B needs 1.75 GB, which Prism says is about 9 times smaller than a standard 16-bit model. The scheme works out to 1.58 bits per weight, with each group of 128 weights sharing an FP16 scale factor, and it applies to the entire architecture.
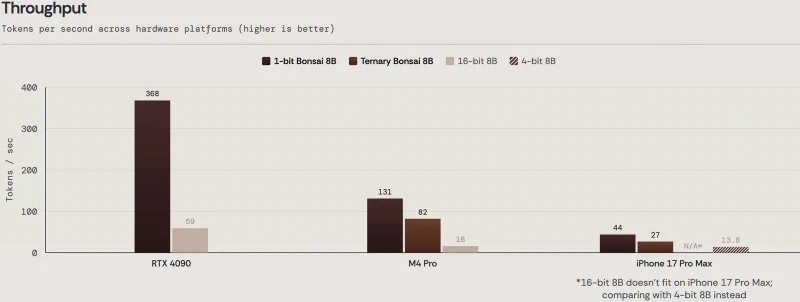
Prism reports 82 tok/s on an M4 Pro and 27 tok/s on an iPhone 17 Pro Max for the 8B model. A 4-bit 8B model reaches 13.8 tok/s on the same iPhone in the company’s chart. Energy use is 0.105 mWh per token on the M4 Pro and 0.132 mWh per token on the iPhone 17 Pro Max, which Prism says is 3 to 4 times better than 16-bit counterparts.
Ternary Bonsai 8B averages 75.5 across Prism’s benchmark set, compared with 70.5 for the earlier 1-bit Bonsai 8B, at about 600 MB more memory. The individual scores are 72.6 on MMLU Redux, 56.2 on MuSR, 91.0 on GSM8K, 77.4 on HumanEval+, 81.8 on IFEval and 73.9 on BFCLv3. According to Prism, only Qwen3 8B (16.38 GB) scores higher among the 8B-class models it compared, and the Bonsai model is 9 to 10 times smaller.
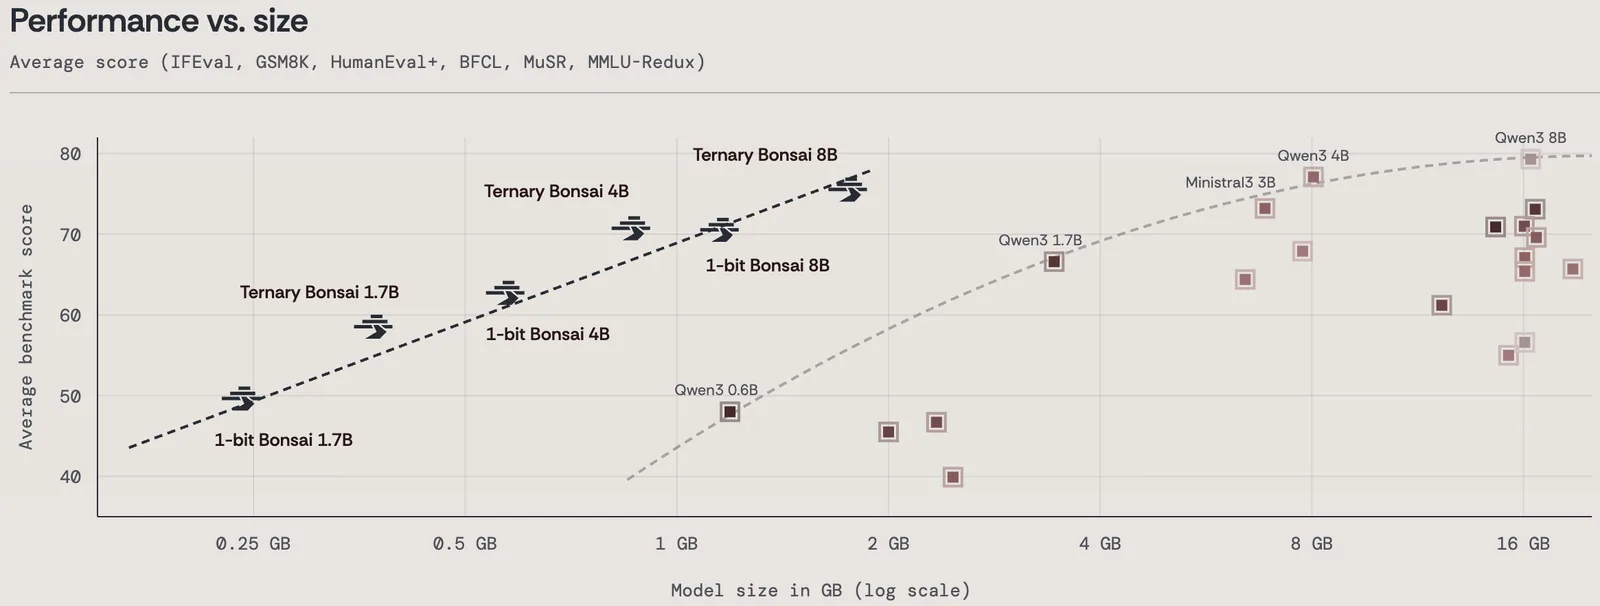
Average benchmark score against model size, as charted by Prism ML.Prism ML
The models are released under the Apache 2.0 license. They are available on Hugging Face and in the GitHub repository, which covers macOS, and run on Apple devices via MLX. On iPhone the iOS app Locally AI runs them, and a whitepaper describes the method.